

ResearchPerplexityConfirmed
Story 7 of 10 in the Wednesday 21 October editionPerplexity’s JOLT trains one model as both privileged teacher and student
Joint On-Policy Learning and Teaching regularises the teacher toward the student’s current behaviour, cutting MATH training tokens by 6.5 times against GRPO.

 Edited by Ashutosh Shrivastava
22 Oct 2026, 10:33 IST · 2 min read
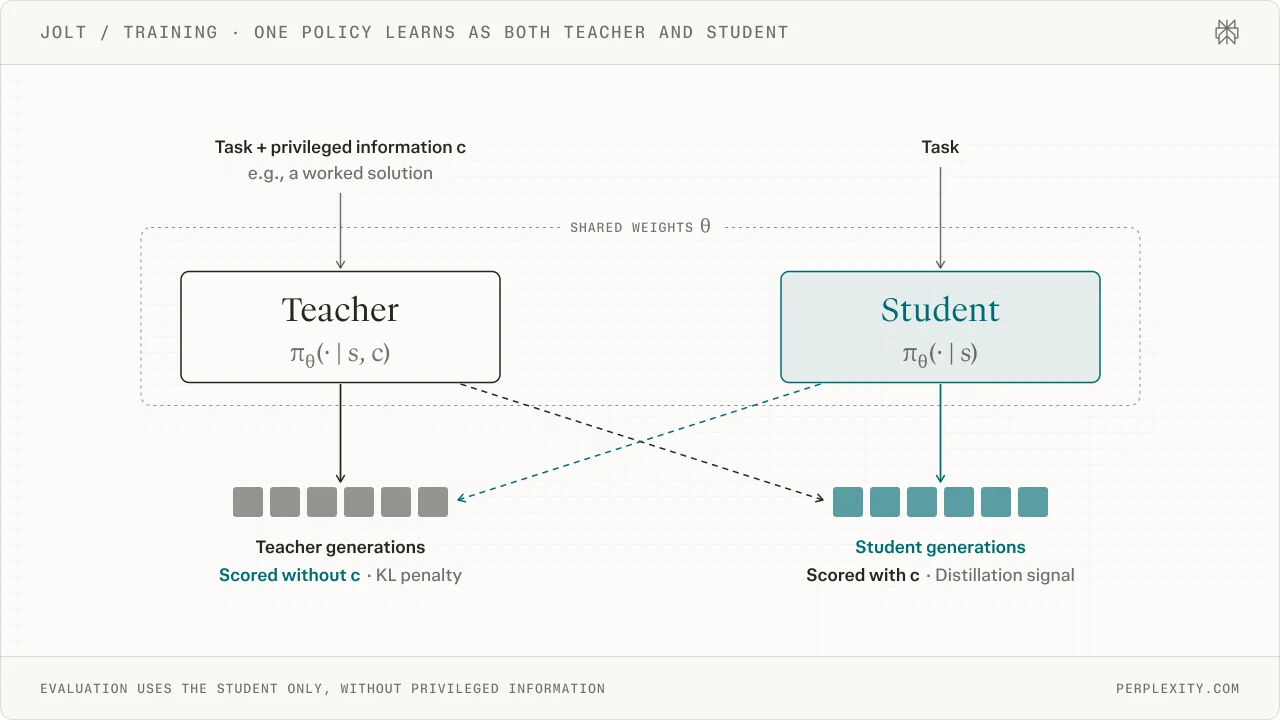
Perplexity published a research paper and blog post on 21 October 2026 introducing Joint On-Policy Learning and Teaching (JOLT), a post-training method for reasoning, coding and agentic tasks. In standard On-Policy Self-Distillation (OPSD), one model acts as its own teacher by reading privileged context such as a verified answer, reference proof or test log, and the unprivileged student learns to imitate it token by token. Perplexity’s authors show that a stronger teacher can actually hurt the student if it relies on shortcuts that the student cannot reproduce without the answer key.
JOLT fixes that mismatch by training both roles jointly inside a single set of weights. The teacher learns from outcome rewards with a Kullback-Leibler (KL) penalty that keeps its token probabilities close to the student’s current policy, while the student learns from the teacher’s dense distillation signal on the student’s own rollouts. A second variant, JOLT+, adds the student’s own centred outcome rewards to the distillation update.
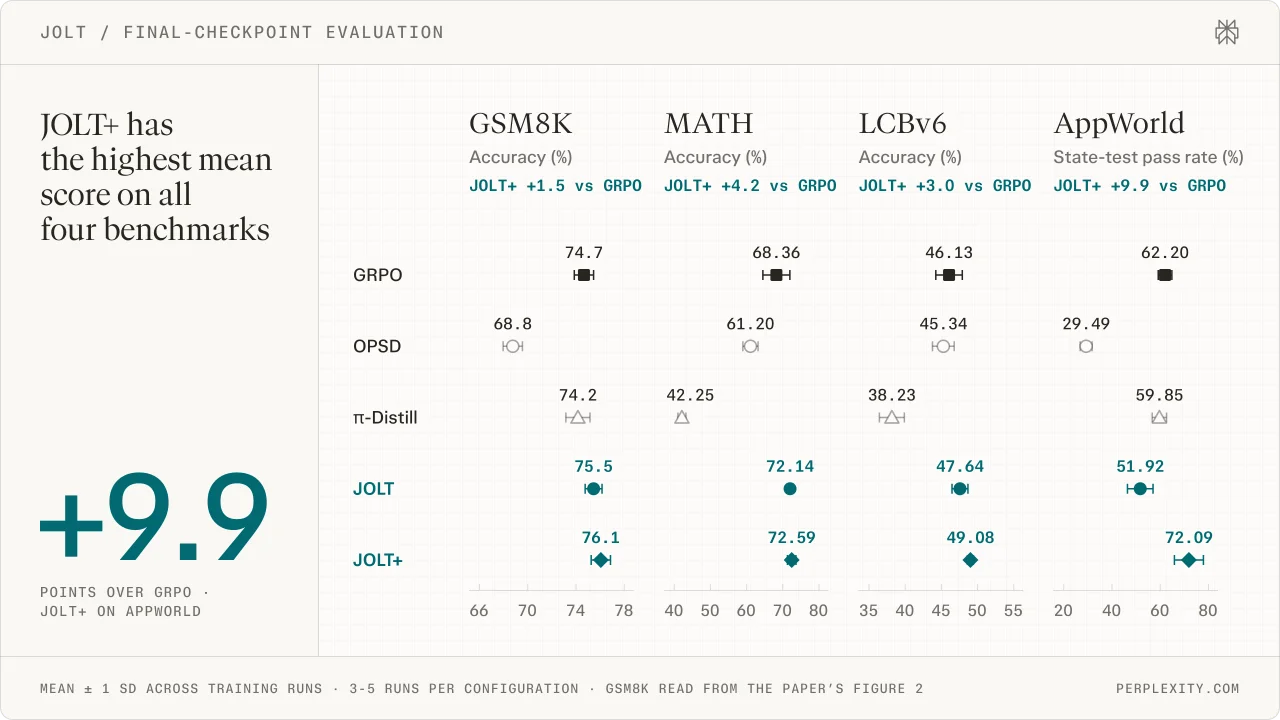
Across five benchmarks (GSM8K on DeepSeek-V2-Lite, MATH on Qwen3-0.6B, LiveCodeBench-V6 on Qwen3-8B, AppWorld on Qwen3-4B-Instruct and Terminal-Bench 2.1 on Qwen3-30B-A3B-Instruct), JOLT+ records the highest mean score in every setting, beating GRPO by 1.5 percentage points on GSM8K, 4.2 points on MATH, 3.0 points on LCBv6, 9.9 points on AppWorld and 4.5 points at pass@32 on Terminal-Bench 2.1.
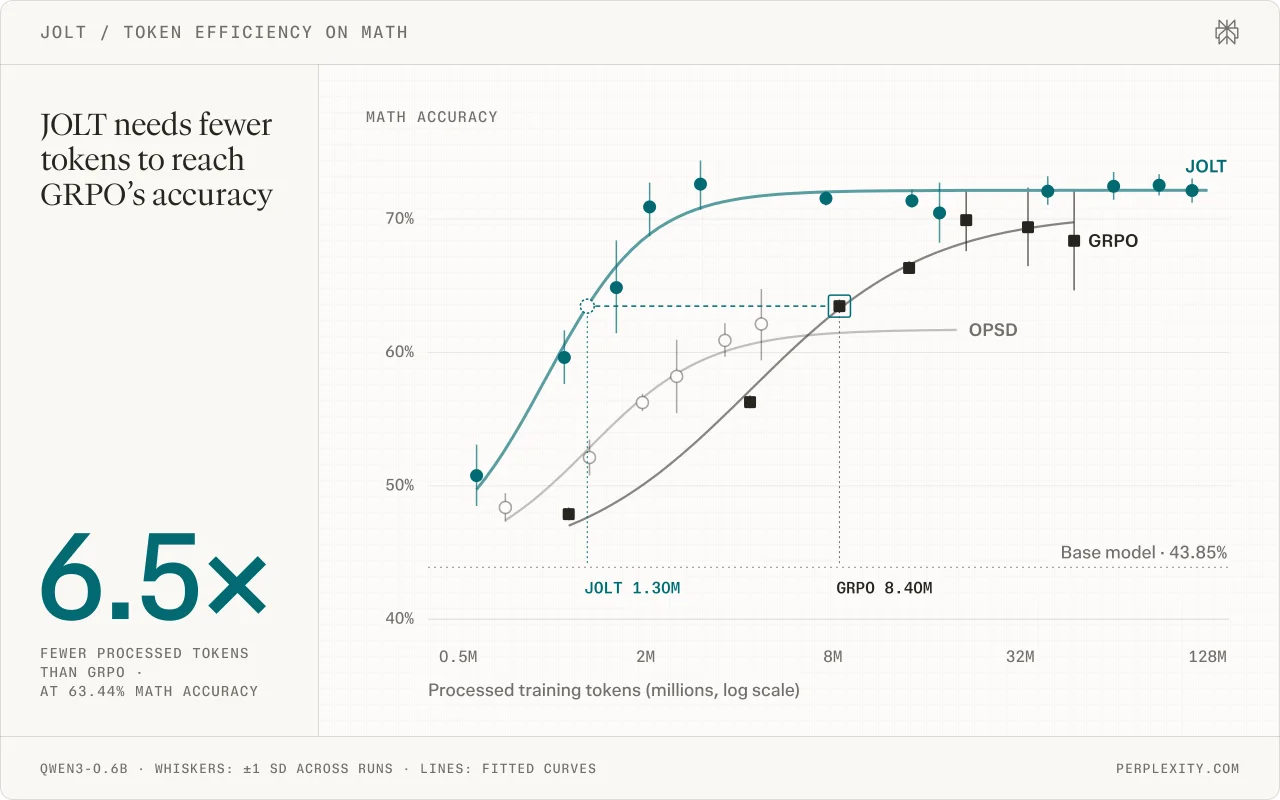
On MATH, JOLT reaches 63.44% accuracy using 1.30 million processed training tokens compared with 8.40 million for GRPO, or 6.5 times fewer processed tokens and 13 times fewer completion tokens. Perplexity says it plans to open-source the code later.
Sources
- PrimaryA good teacher meets the student where they areperplexity.ai · Perplexity research blog post, 21 October 2026
- OfficialA Good Self-Teacher Meets the Student Where They Are: Joint On-Policy Learning and Teachingarxiv.org · Paper by Randy Ardywibowo, Arnav Dalal and Jiantao Jiao (arXiv:2610.10447)
- On X@perplexity_ai on X: Introducing JOLTx.com · Perplexity’s launch thread on X, 21 October 2026
The rest of the day
Read the whole day
01ProductAnthropic
Anthropic previews Claude Duet, a proactive agent built on Claude Opus 5.5
Claude Duet runs on its own cloud virtual machine, sends a morning brief across connected apps, and asks before sending messages, making payments or signing documents.
02ProductOpenAI
OpenAI brings GPT-6 models and Codex workflows to Google Cloud’s Model Garden
GPT-6 Astra, GPT-6.1 Sol and GPT-6 Luna enter private preview in Model Garden, transacted through Google Cloud Marketplace and existing cloud commitments.
03ProductAnthropic
Anthropic adds continuous scanning with Claude Mythos to Claude Security
Now in public beta for Claude Enterprise, Claude Security builds a project threat model, re-scans repositories as commits land, and tracks findings until they are fixed.
04ProductSpaceXSI
SpaceXSI’s Grok Bot now builds live reports, memos and dashboards
Users can ask Grok Bot for an interactive report, memo or dashboard page, edit it together, or have the bot keep the page updated over time.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X