

ModelMiniMaxConfirmed
Story 1 of 7 in the Monday 19 October editionMiniMax releases MiniMax-M3.1-Flash with a 1M-token context window
MiniMax-M3.1-Flash has a 1M-token context and costs $0.15 per million input tokens. Callers set how hard it thinks, and it also takes images and video.

 Edited by Ashutosh Shrivastava
20 Oct 2026, 10:10 IST · 2 min read
MiniMax released MiniMax-M3.1-Flash on 19 October 2026, through the MiniMax API, the M Plan subscription and MiniMax Code. It keeps a context window of 1,000,000 tokens, and it accepts text, images and video, so an agent session can carry a long document and look at pictures or clips in the same request.
Thinking depth is a setting MiniMax calls effort: low, medium, high, xhigh or max. A higher setting makes the model think longer before it answers, which uses more output tokens and adds latency. If the request leaves effort unset, the default is max. Thinking stays on, and MiniMax says a request that tries to turn it off is rejected. On the OpenAI-style API the reasoning comes back in a separate field from the answer.
MiniMax says Space Bunny, which processed more than 200 trillion tokens while running without its name attached, was an early version of this model.
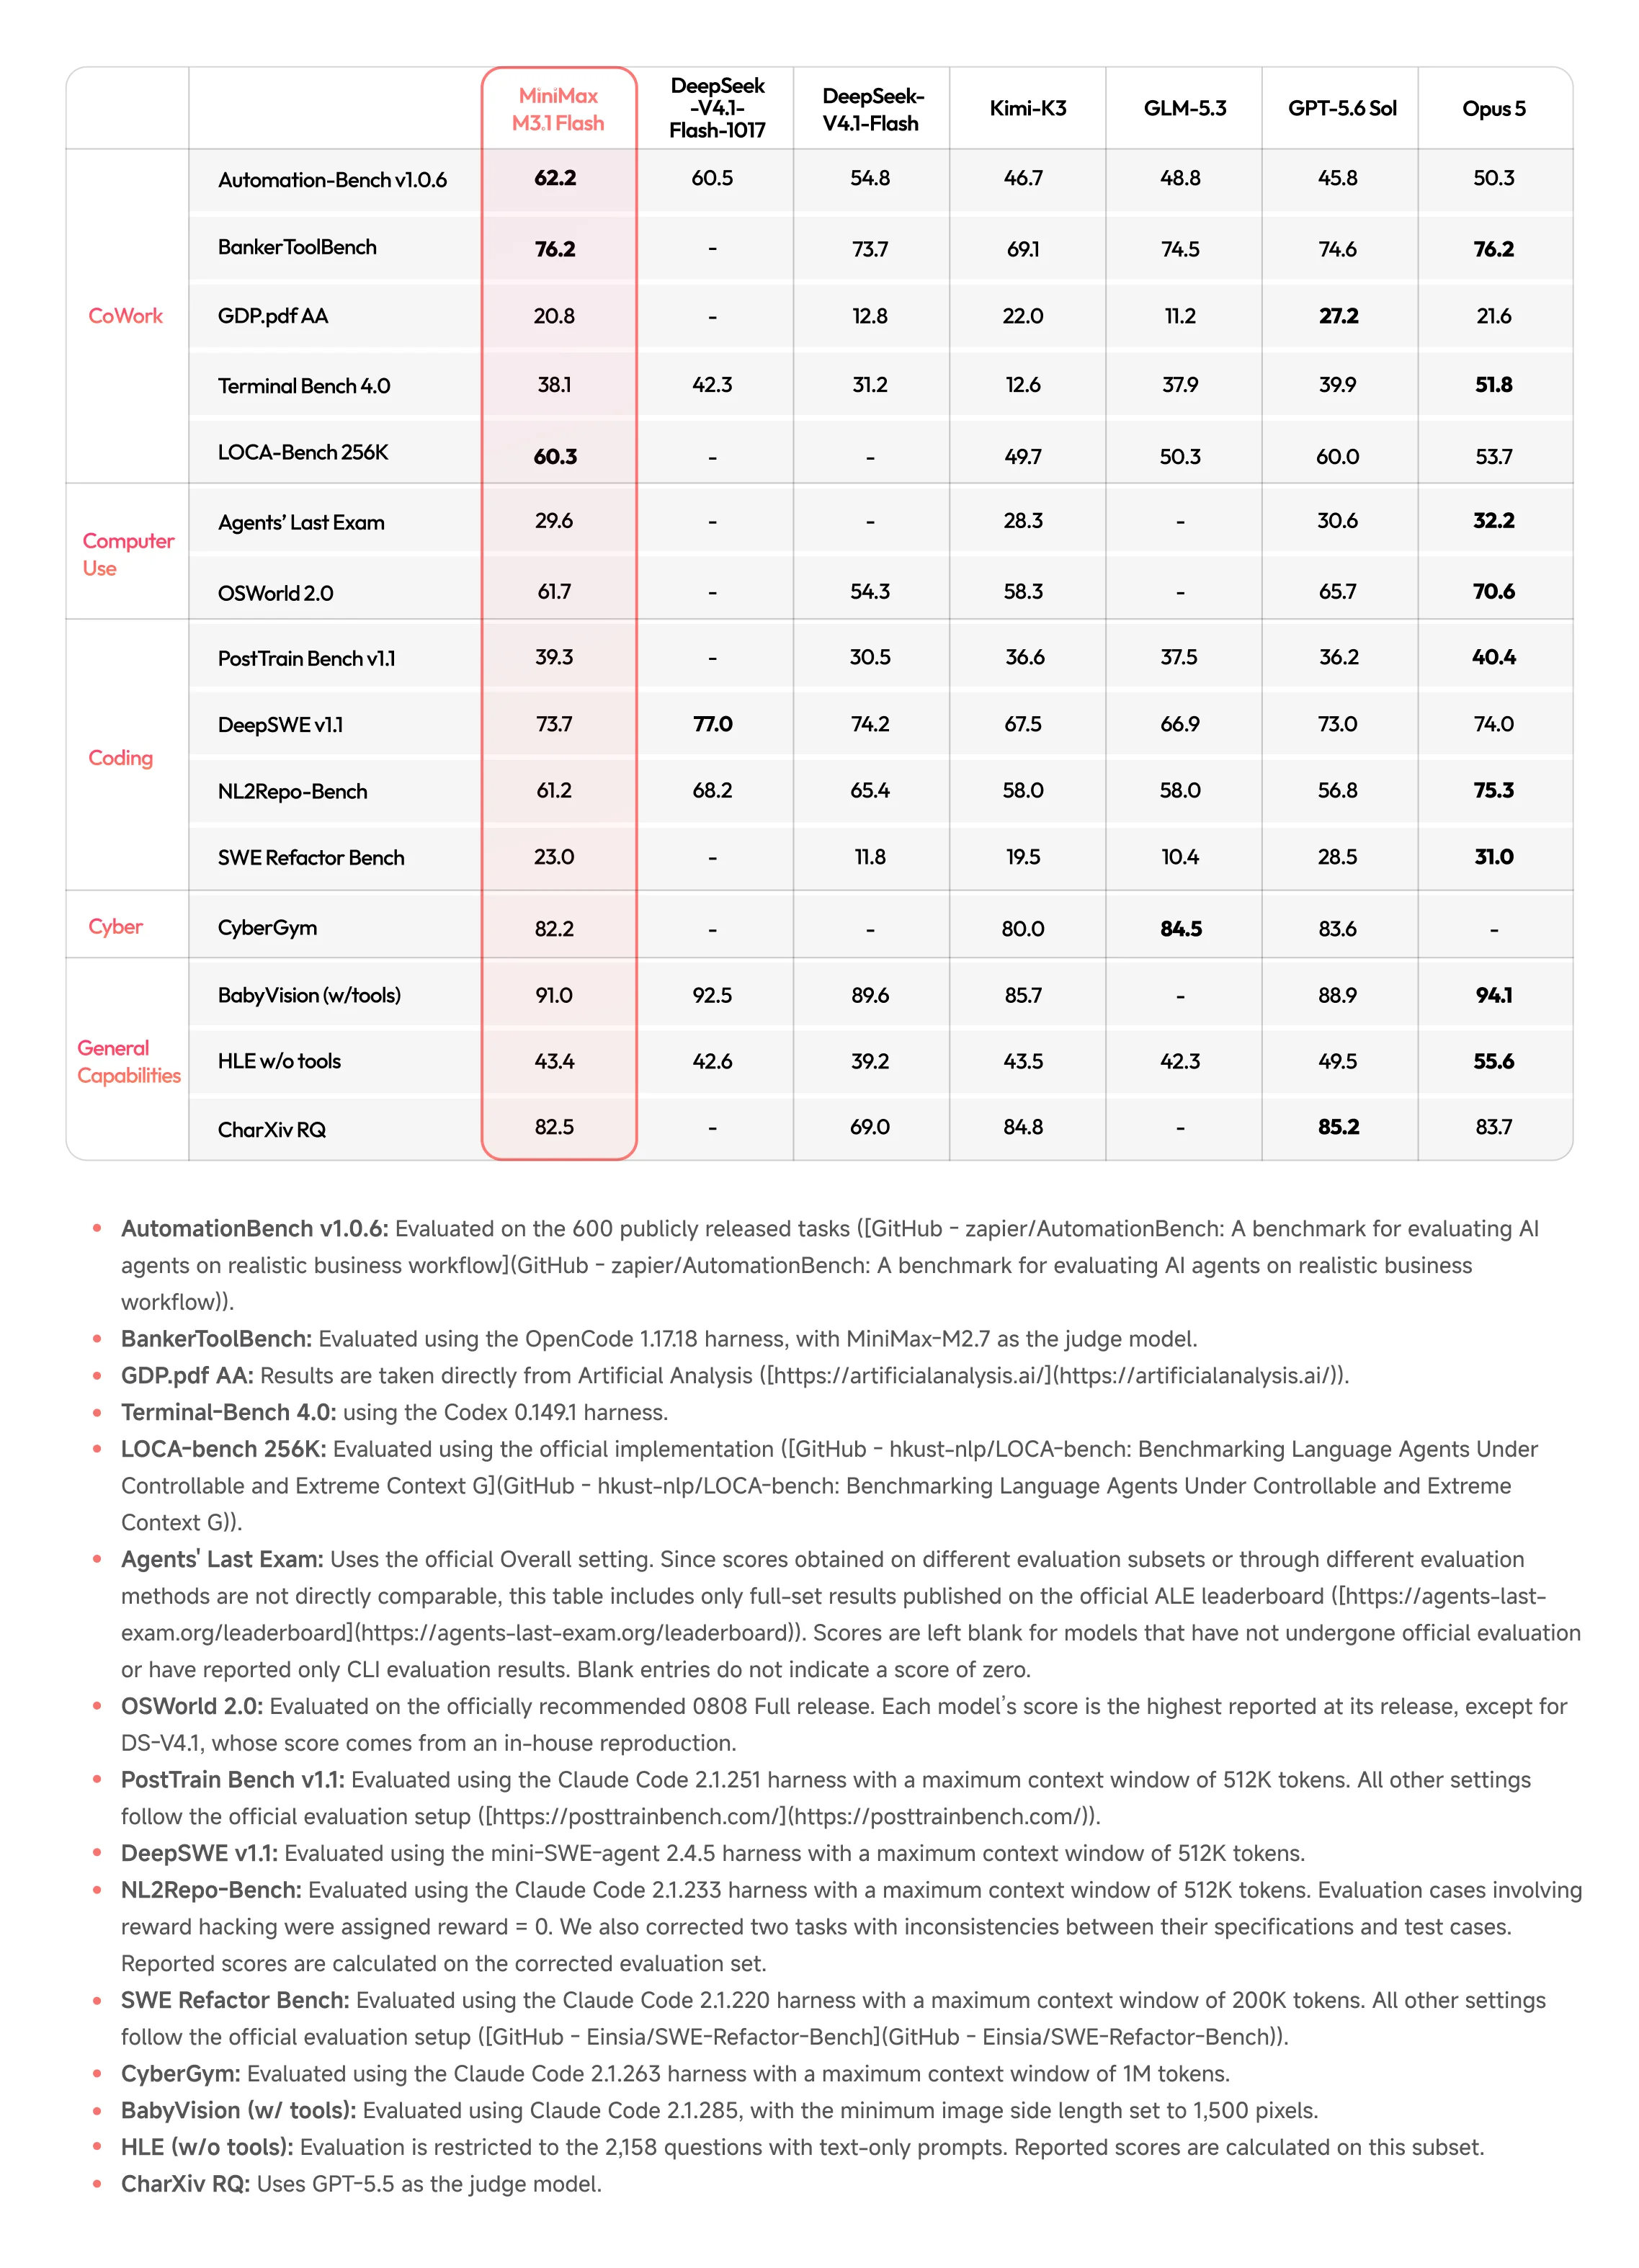
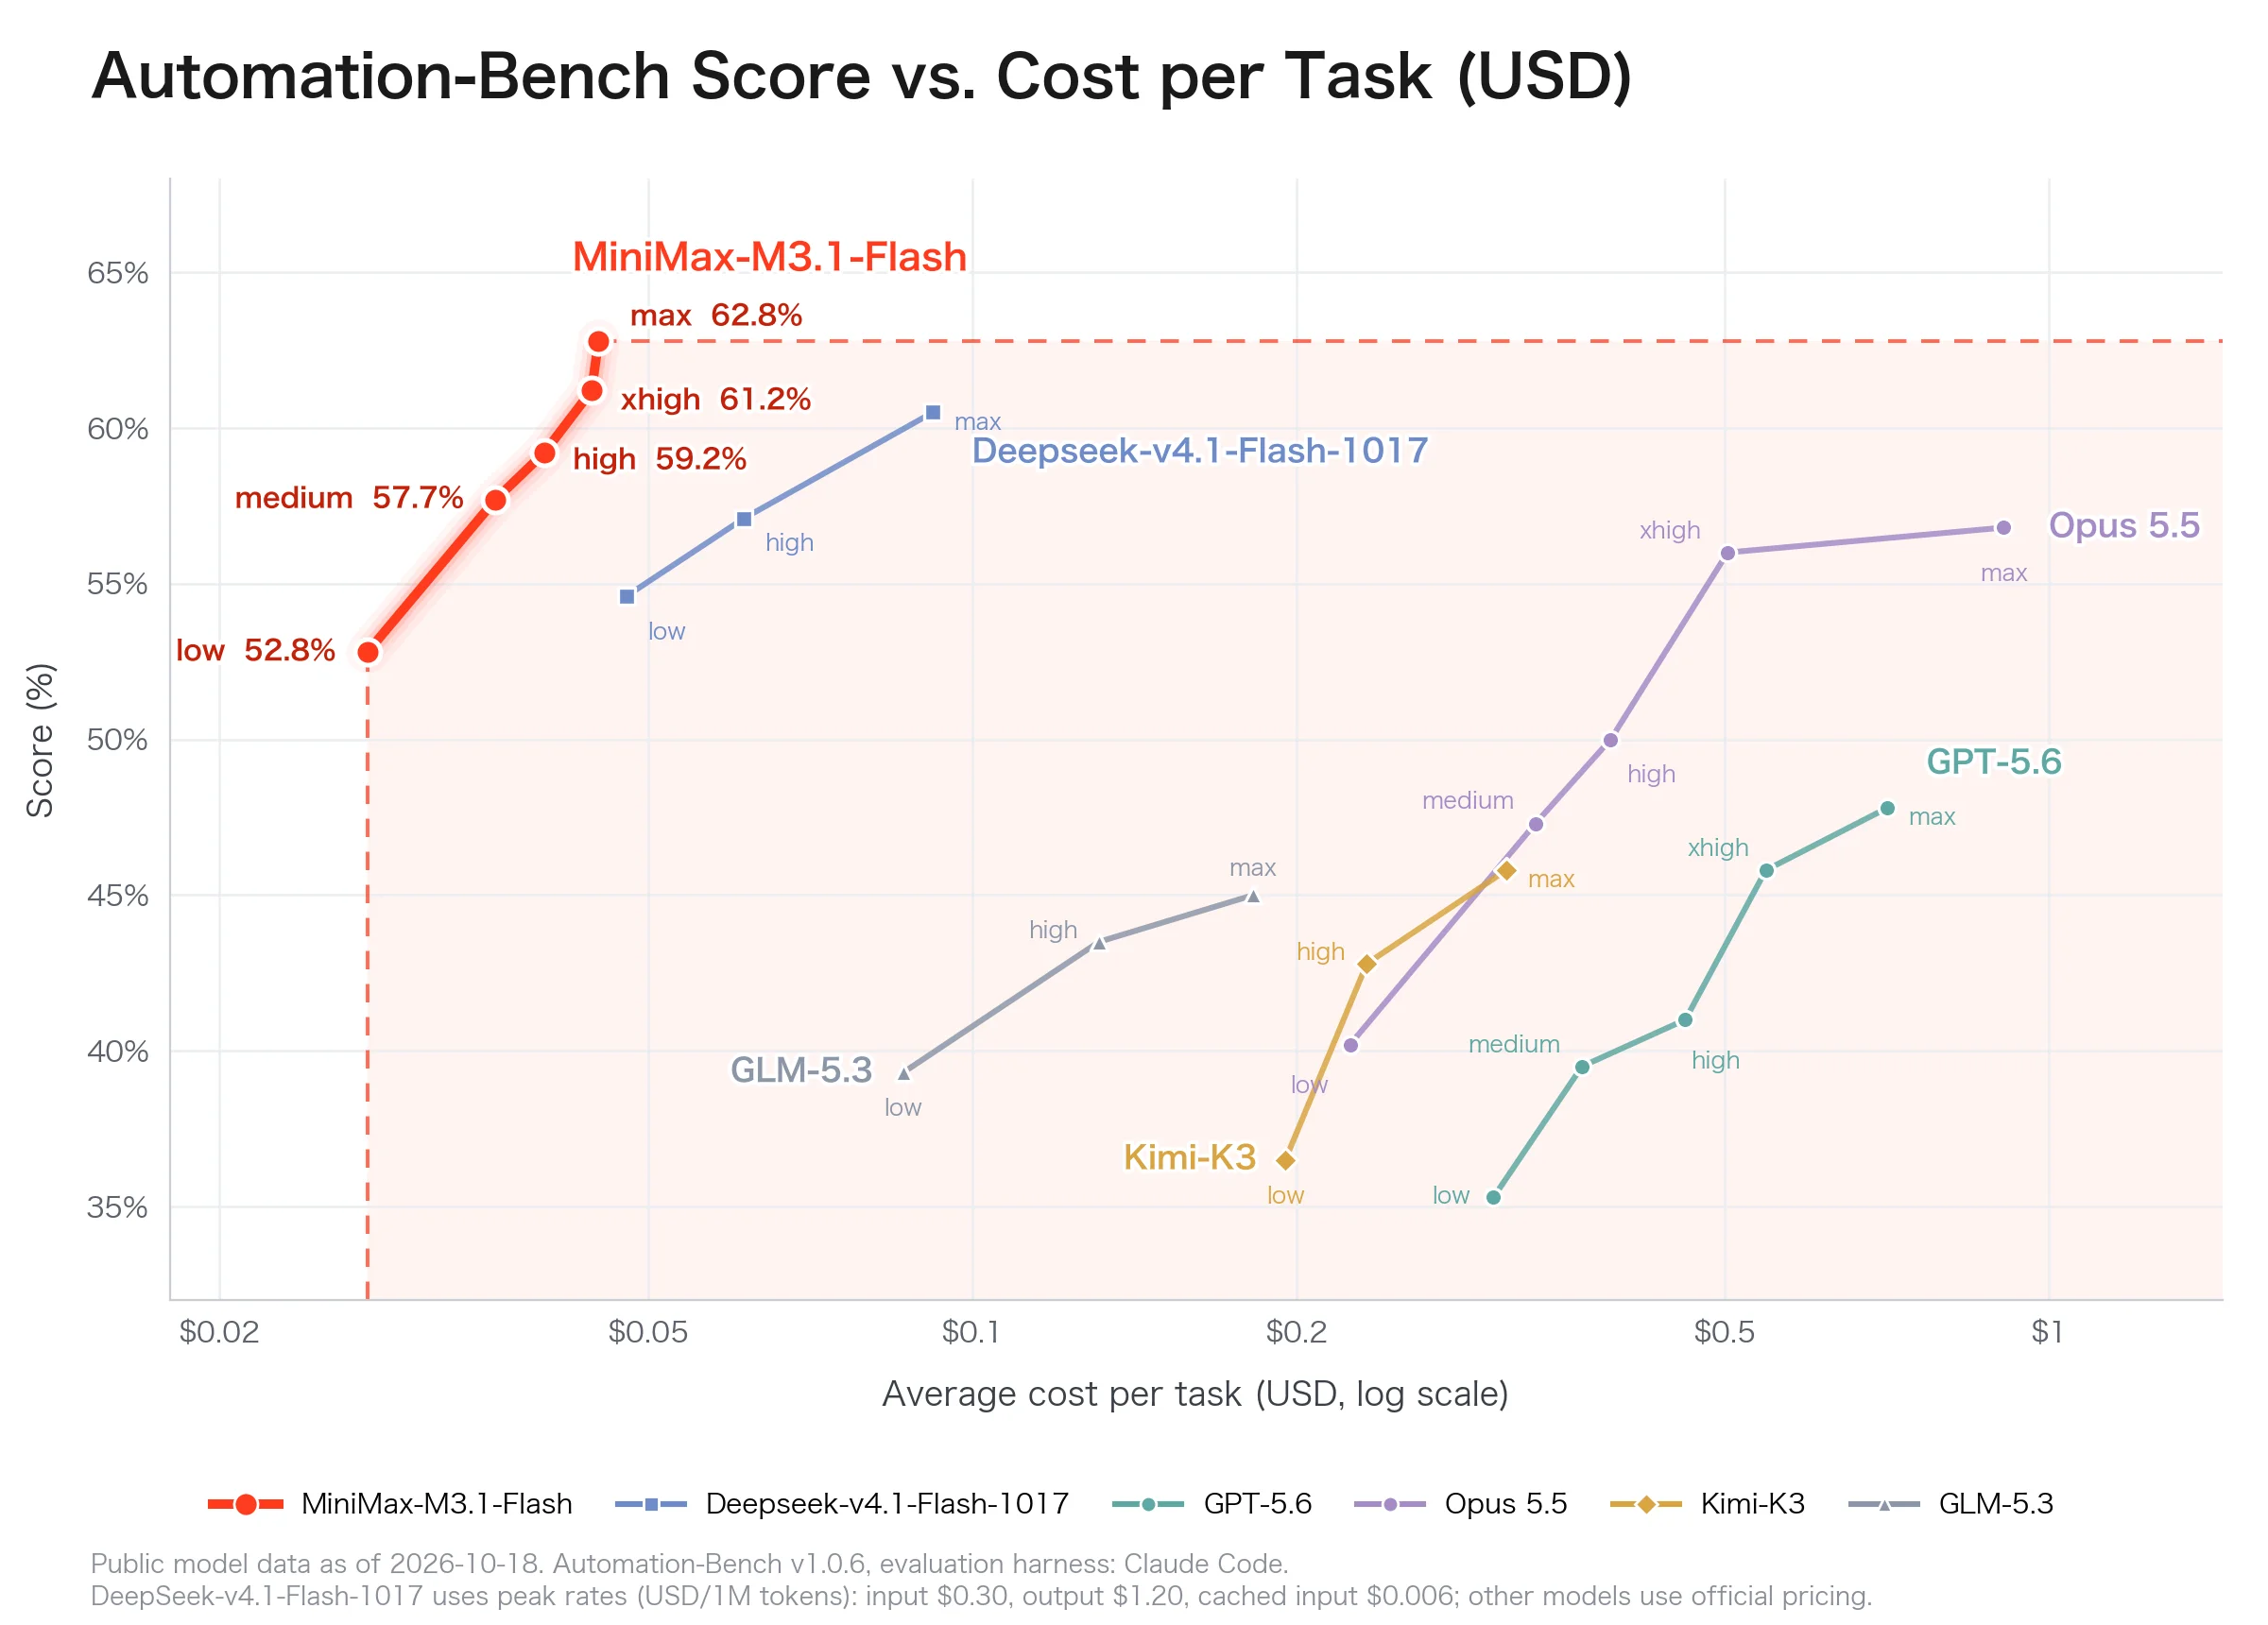
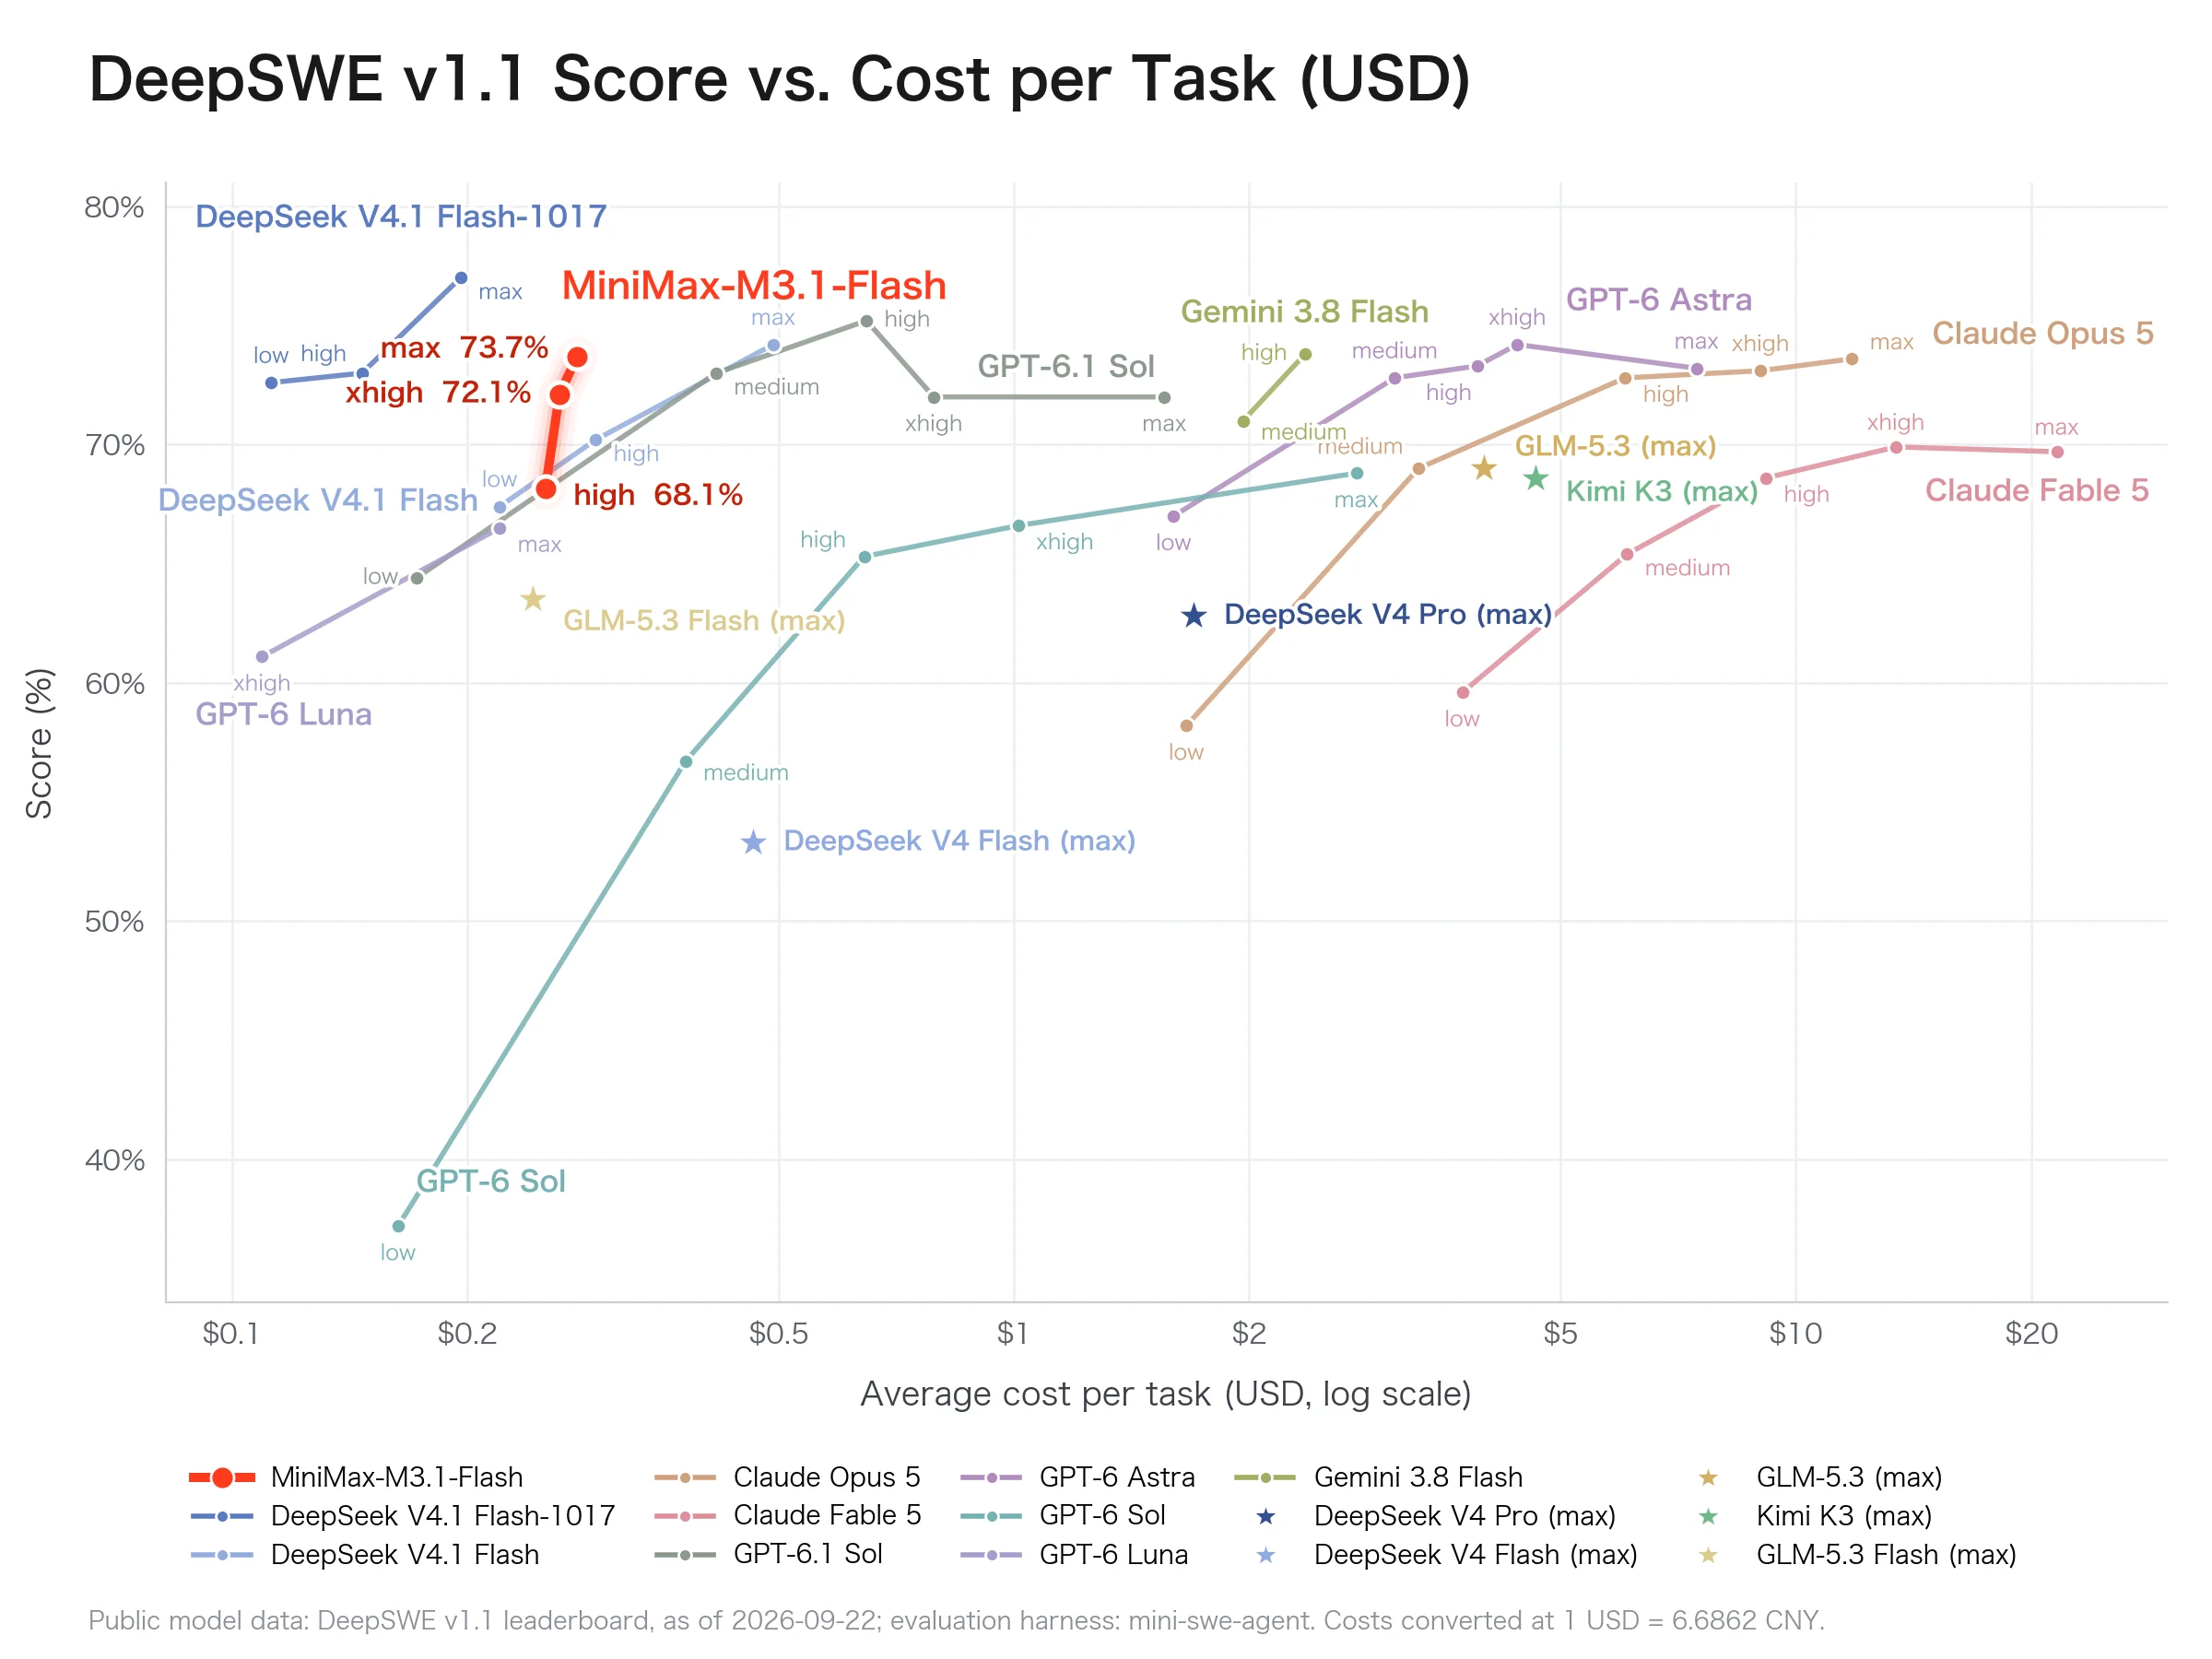
The comparison table and the two cost charts are MiniMax’s. The table prints 62.2 on Automation-Bench v1.0.6 while the Automation-Bench cost chart prints 62.8% at max effort, and the post’s claim of usage cost 70% lower than the predecessor is not the list price: the pricing page sets input at half MiniMax-M3’s standard rate on inputs up to 512k tokens.
Key numbers
- Input $0.15, output $0.60 and cached input $0.015, per million tokens, on the pricing page
- Context window of 1,000,000 tokens
- Thinking depth from low to max, with max as the default
The release notes call it an open-weight model. The research post says the weights will be released later, and does not give a date. MiniMax also says a Pro model will arrive later, again with no date.
Sources
- PrimaryMiniMax M3.1 Flash research postminimax.io · Announcement, 19 October 2026, with pricing and charts
- OfficialModel invocation guideplatform.minimax.io · Context length, image and video input, and effort levels
- OfficialPricing overviewplatform.minimax.io · API prices for MiniMax-M3.1-Flash and MiniMax-M3
- OfficialModel release notesplatform.minimax.io · 19 October 2026 entry calling it an open-weight model
- OfficialOpenAI-compatible chat APIplatform.minimax.io · The model name in the chat completions example
- On X@MiniMax_AI on X: MiniMax M3.1 Flashx.com · MiniMax’s launch post, 19 October 2026
- On X@MiniMaxAgent on X: available in MiniMax Codex.com · MiniMax Agent’s post on the same release
The rest of the day
Read the whole day
02OtherDepartment of Homeland Security
Department of Homeland Security publishes a DeepSeek removal order
A notice filed on 19 October 2026 publishes an order dated 24 July 2026 that tells US civilian agencies to drop DeepSeek products, including tools built with them.
03ProductMicrosoft
Microsoft adds agent containment controls to Project Perception
New controls can narrow what an agent is allowed to do as its risk score changes, including keeping reads while blocking writes.
04ModelInception
Inception launches Mercury 3, a diffusion language model
Mercury 3 has a 1M-token context, up from 260k in Mercury 2.5.
05Open sourceMeta
Meta publishes the technical report for Muse Glimmer 30B
The report is dated 19 October 2026.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X