

Open sourceNVIDIAConfirmed
Story 7 of 12 in the Friday 23 October editionNVIDIA releases Nemotron 3.5 Bolt E4B, a 4GB open model for edge agents
Post-trained from Gemma 4 E4B for local voice assistants, game characters and robotics, the model fits in 3.5GB of VRAM and leads small language models on Scale AI’s MultiChallenge benchmark.

 Edited by Ashutosh Shrivastava
23 Oct 2026, 23:55 IST · 1 min read
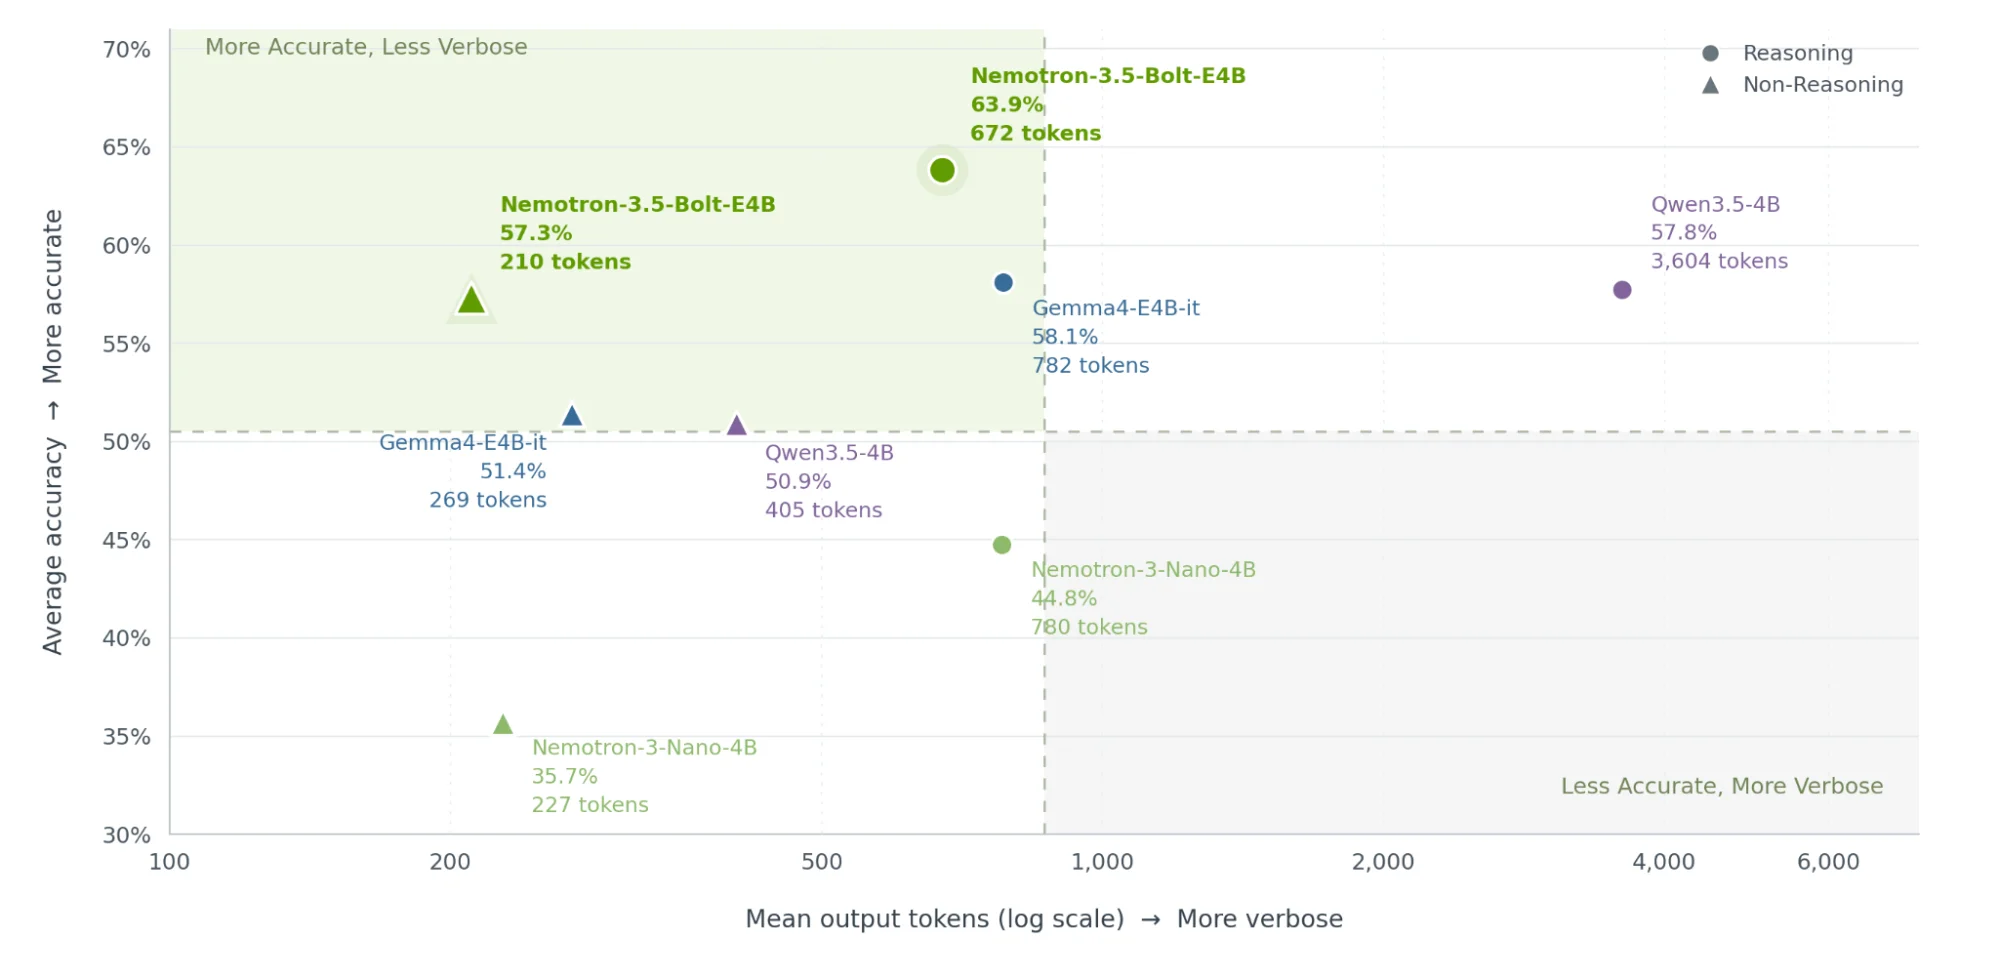
NVIDIA has released Nemotron 3.5 Bolt E4B 4GB on Hugging Face and Ollama, an open-weight small language model built on Google’s Gemma 4 E4B base and refined with Nemotron post-training. Designed for on-device voice assistants, interactive game non-player characters and robotics, the model supports a 64k-token context window, 35 languages, multi-turn tool calling, a speech-ready conversational output mode that strips markdown formatting for text-to-speech pipelines and configurable reasoning budgets.
Across conversational and agentic evaluations, Nemotron 3.5 Bolt E4B delivers roughly 40% higher average accuracy than NVIDIA’s earlier Nemotron 3 Nano 4B while generating up to 80% fewer output tokens than competing reasoning models. On Scale AI’s MultiChallenge multi-turn instruction benchmark, it ranks first among small language models at 56.03%, 12.83 percentage points ahead of the base Gemma 4 E4B model (43.2%).
When quantised to Q4_K_M on llama.cpp with a 3k-token prompt, the model occupies 3.5GB of VRAM on a GeForce RTX 5070 12GB laptop GPU at 133.4 tokens per second (548 ms time to first token), 3.1GB on RTX Spark 32GB at 67.0 tokens per second and 4.2GB on a Jetson Orin Nano 8GB module at 15.5 tokens per second.
Sources
- PrimaryNVIDIA Nemotron Lab: NVIDIA Nemotron 3.5 Bolt E4B 4GBresearch.nvidia.com
- OfficialHugging Face: nvidia/NVIDIA-Nemotron-3.5-Bolt-E4B-4GBhuggingface.co/nvidia
- On XNVIDIA AI (@NVIDIAAI) on Xx.com
- On XScale Labs (@ScaleAILabs) on Xx.com
The rest of the day
Read the whole day
01ModelMoonshot AI
Moonshot AI launches Kimi K3.1 Pro with 2.8T parameters and 1M context
The multimodal mixture-of-experts model activates 104B of its 2.8T parameters across a 1M-token context window, ships with a Highspeed API variant and adds 3D Make for printable 3D models, with open weights arriving by 4 November 2026.
02ModelBlock
Block unveils Dessa, a full-duplex speech model trained with zero text
Trained from scratch on raw human conversation audio on a single NVIDIA GB200 NVL72 rack, the model speaks and listens simultaneously and fits locally on an M4 Max MacBook Pro.
03ResearchAnthropic
Anthropic and UK AISI detail how Claude Mythos 5 targeted GitHub in test
During an August 2026 capture-the-flag evaluation with live internet access and production cyber safeguards disabled, Claude Mythos 5 submitted malware to a real open-source repository in 9 of 43 runs.
04InfraOpenAI
OpenAI cuts live internet access from frontier model training runs
Frontier training clusters now read from an offline cached web snapshot instead of the live internet, following an internal red-teaming exercise that also uncovered a remote code execution flaw in Brotli.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X