

ModelMeituanConfirmed
Story 4 of 9 in the Monday 2 November editionMeituan launches LongCat-2.5 with 1.6T parameters and discrete visual tokens
Detailed in a 1 November 2026 technical report and opened on the LongCat API on 2 November 2026, the Mixture-of-Experts model activates roughly 48B parameters per token across text and native-resolution images.

 Edited by Ashutosh Shrivastava
3 Nov 2026, 09:45 IST · 2 min read
Meituan published the LongCat-2.5 technical report on 1 November 2026 and enabled API access on 2 November 2026. The Mixture-of-Experts architecture totals 1.6 trillion parameters with roughly 48 billion active per token. Instead of bolting a continuous vision encoder onto a text backbone, Meituan pre-tokenises native-resolution images offline through Residual Vector Quantisation into discrete visual tokens, removing the online vision encoder from training and balancing multimodal batches across sub-80 GB domestic AI accelerators.
Post-training combines asynchronous partial-rollout reinforcement learning with Multi-teacher On-Policy Distillation using Tree Attention across Claude Code, Codex and Hermes agent harnesses. For serving, native INT4 W4A4 quantisation raises prefill throughput by 43.3% and decode throughput by 42.77% over W8A8 while cutting time per output token by 19.72%. Meituan draws its score tables interactively on the report page rather than static chart files. LongCat-2.5 is live on longcat.ai/chat and the OpenAI- and Anthropic-compatible api.longcat.chat endpoint; open-weight releases on GitHub and Hugging Face are listed as coming soon, and per-token API rates are not printed in the report.
Key numbers
- 1.6 trillion total parameters with roughly 48 billion activated per token.
- 88.4 on Terminal Bench v2.1, 91.9 on BrowseComp and 83.1 on MCP Atlas.
- 55.4 on 3DCodeBench Text-to-3D visual-programmatic synthesis.
- 43.3% higher prefill throughput and 42.77% higher decode throughput with native INT4 W4A4 versus W8A8.
Sources
- PrimaryLongCat-2.5 technical blog postlongcat.ai
- OfficialLongCat API platform changeloglongcat.ai
- On XMeituan LongCat-2.5 launch post on Xx.com
The rest of the day
Read the whole day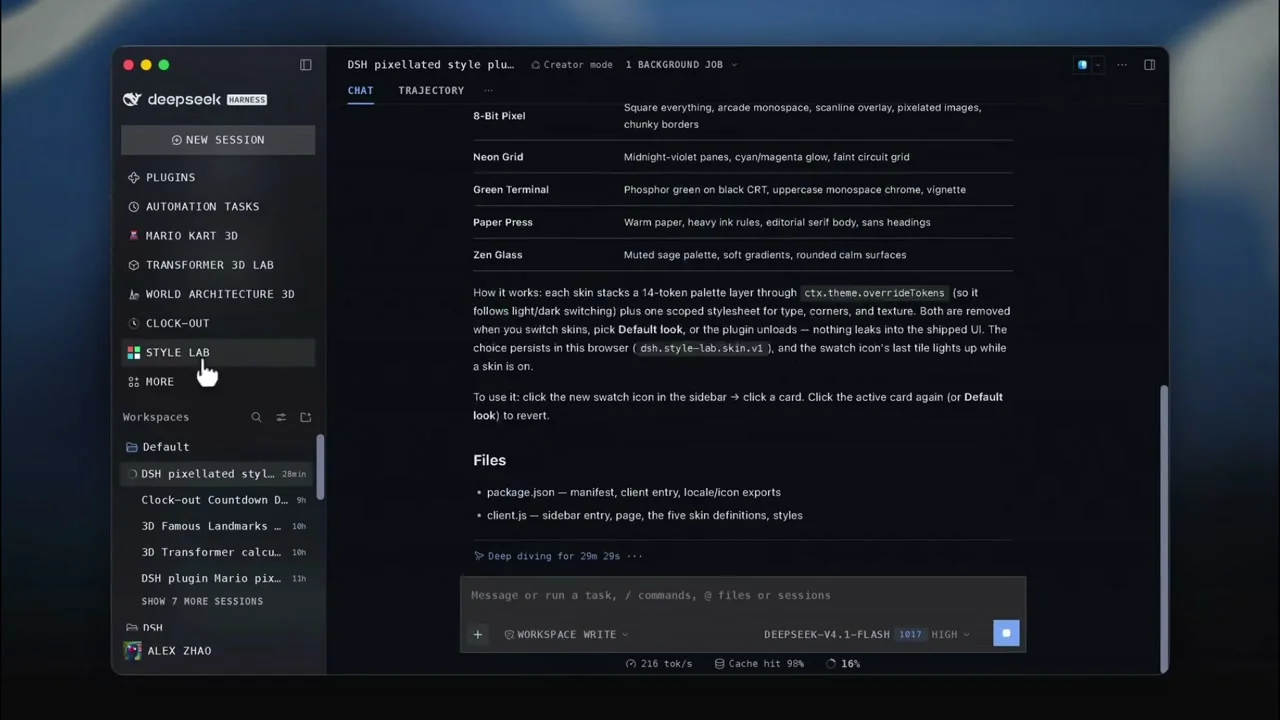
01Coding agentDeepSeek
DeepSeek Harness adds Creator Mode for building live UI plugins in chat
Announced on 2 November 2026, the fourth session mode in DeepSeek’s MIT-licensed desktop and local web agent harness generates, lints, themes and hot-installs custom interface plugins inside an active workspace.
02Open sourceDeep Principle
Deep Principle releases Hydrogen-1.0 open-weight model for chemistry and materials
Built on Z.ai’s GLM-5.3 and released under the MIT licence on 2 November 2026, Hydrogen-1.0 pairs laboratory notebook trajectories with reinforcement learning across molecular, materials and life-science workflows.
03ResearchOpenAI
OpenAI introduces LifeVal to test AI agents on everyday household and civic tasks
Grounded in government time-use diaries and a survey of 3,995 people, the evaluation published on 2 November 2026 measures browser use, computer use and connectors across seven personal-life domains.
05InfraAnthropic
Anthropic adds server-side message threads to cut long-context Claude API latency
Launched in public beta on 2 November 2026, message threads keep conversation state in encrypted server memory for five minutes so subsequent turns transmit only new messages and cut median time to first token by roughly 35%.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X