

ProductGitHubConfirmed
Story 7 of 11 in the Friday 6 November editionGitHub launches Copilot Verified Proficiency to score real-world coding skills
Part of Microsoft Pro Badge, the opt-in credential continuously evaluates how developers apply GitHub Copilot across five core workflows without an exam.

 Edited by Ashutosh Shrivastava
7 Nov 2026, 09:30 IST · 1 min read
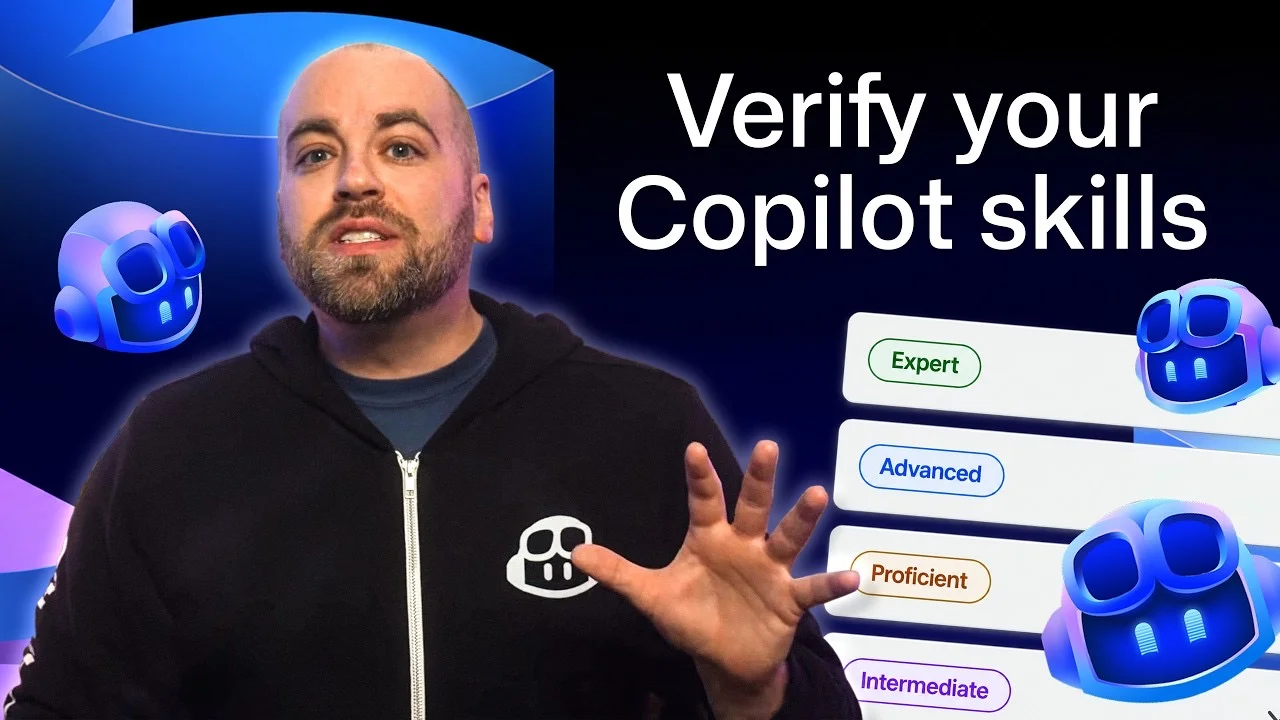
GitHub launched Copilot Verified Proficiency on 6 November 2026, introducing an opt-in credential under the Microsoft Pro Badge programme that measures how developers use GitHub Copilot in their daily work rather than in a proctored test. The system evaluates real workflow telemetry across five Copilot skill areas, weighing breadth across task types, depth on complex engineering work, and consistency over time.
Results are private to the individual developer by default and can be shared on professional profiles once calculated, typically after a few days of regular Copilot usage. At launch, GitHub scores three tiers, Beginner, Intermediate, and Proficient, with Advanced and Expert levels planned. Earning the Proficient tier grants a Pro Badge valid for six months while active usage continues.
Sources
- PrimaryGitHub Copilot Verified Proficiencylearn.github.com · GitHub Learn documentation
- On XGitHub Verified Proficiency announcementx.com · Official X post
The rest of the day
Read the whole day
01ProductMeta
Meta launches Spaces in Muse for custom interactive tools built from chat
Users can describe an idea to build persistent planners, trackers, and games inside the Muse app, pin them to navigation, and keep them updated through connected apps.
02ModelMeta
Meta rolls out specialized Muse and Meta AI models with Active Memory
Trained using Muse Wonder, the upgraded models bring Active Memory and Active Focus to consumer Muse and Meta AI interfaces with 2.4 times lower critical forgetting.
03InfraOpenRouter
OpenRouter launches next-generation Auto Router and Auto Code for coding agents
The new routers pick a model and reasoning effort per request within workspace guardrails, matching Claude Opus 5.5 on coding benchmarks at 74% lower cost.
04ResearchOpenAI
OpenAI and Ligo introduce BioBasicsBench for everyday wet-lab biology
The 100-task benchmark tests whether AI agents can interpret raw gels, flow cytometry plots, plates, and microscopy images, with GPT-6 Astra scoring 66.7%.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X