

ModelNVIDIAConfirmed
Story 3 of 10 in the Thursday 15 October editionNVIDIA releases Nemotron 3.5 Super VL and Bolt open models for agents
Super VL, a 120B model that also reads images and documents, targets always-on enterprise agents, while Bolt fits a 74B model into 24GB of memory for RTX PCs and DGX Spark.

 Edited by Ashutosh Shrivastava
16 Oct 2026, 10:47 IST · 2 min read
NVIDIA released Nemotron 3.5 Super VL and Nemotron 3.5 Bolt 74B-A9B on 15 October 2026. Super VL has 120B parameters, 12B of them active per token, and a 1M-token context window. It reads text, images and video, with a focus on what agents meet at work: web pages, tables, charts and PDFs.
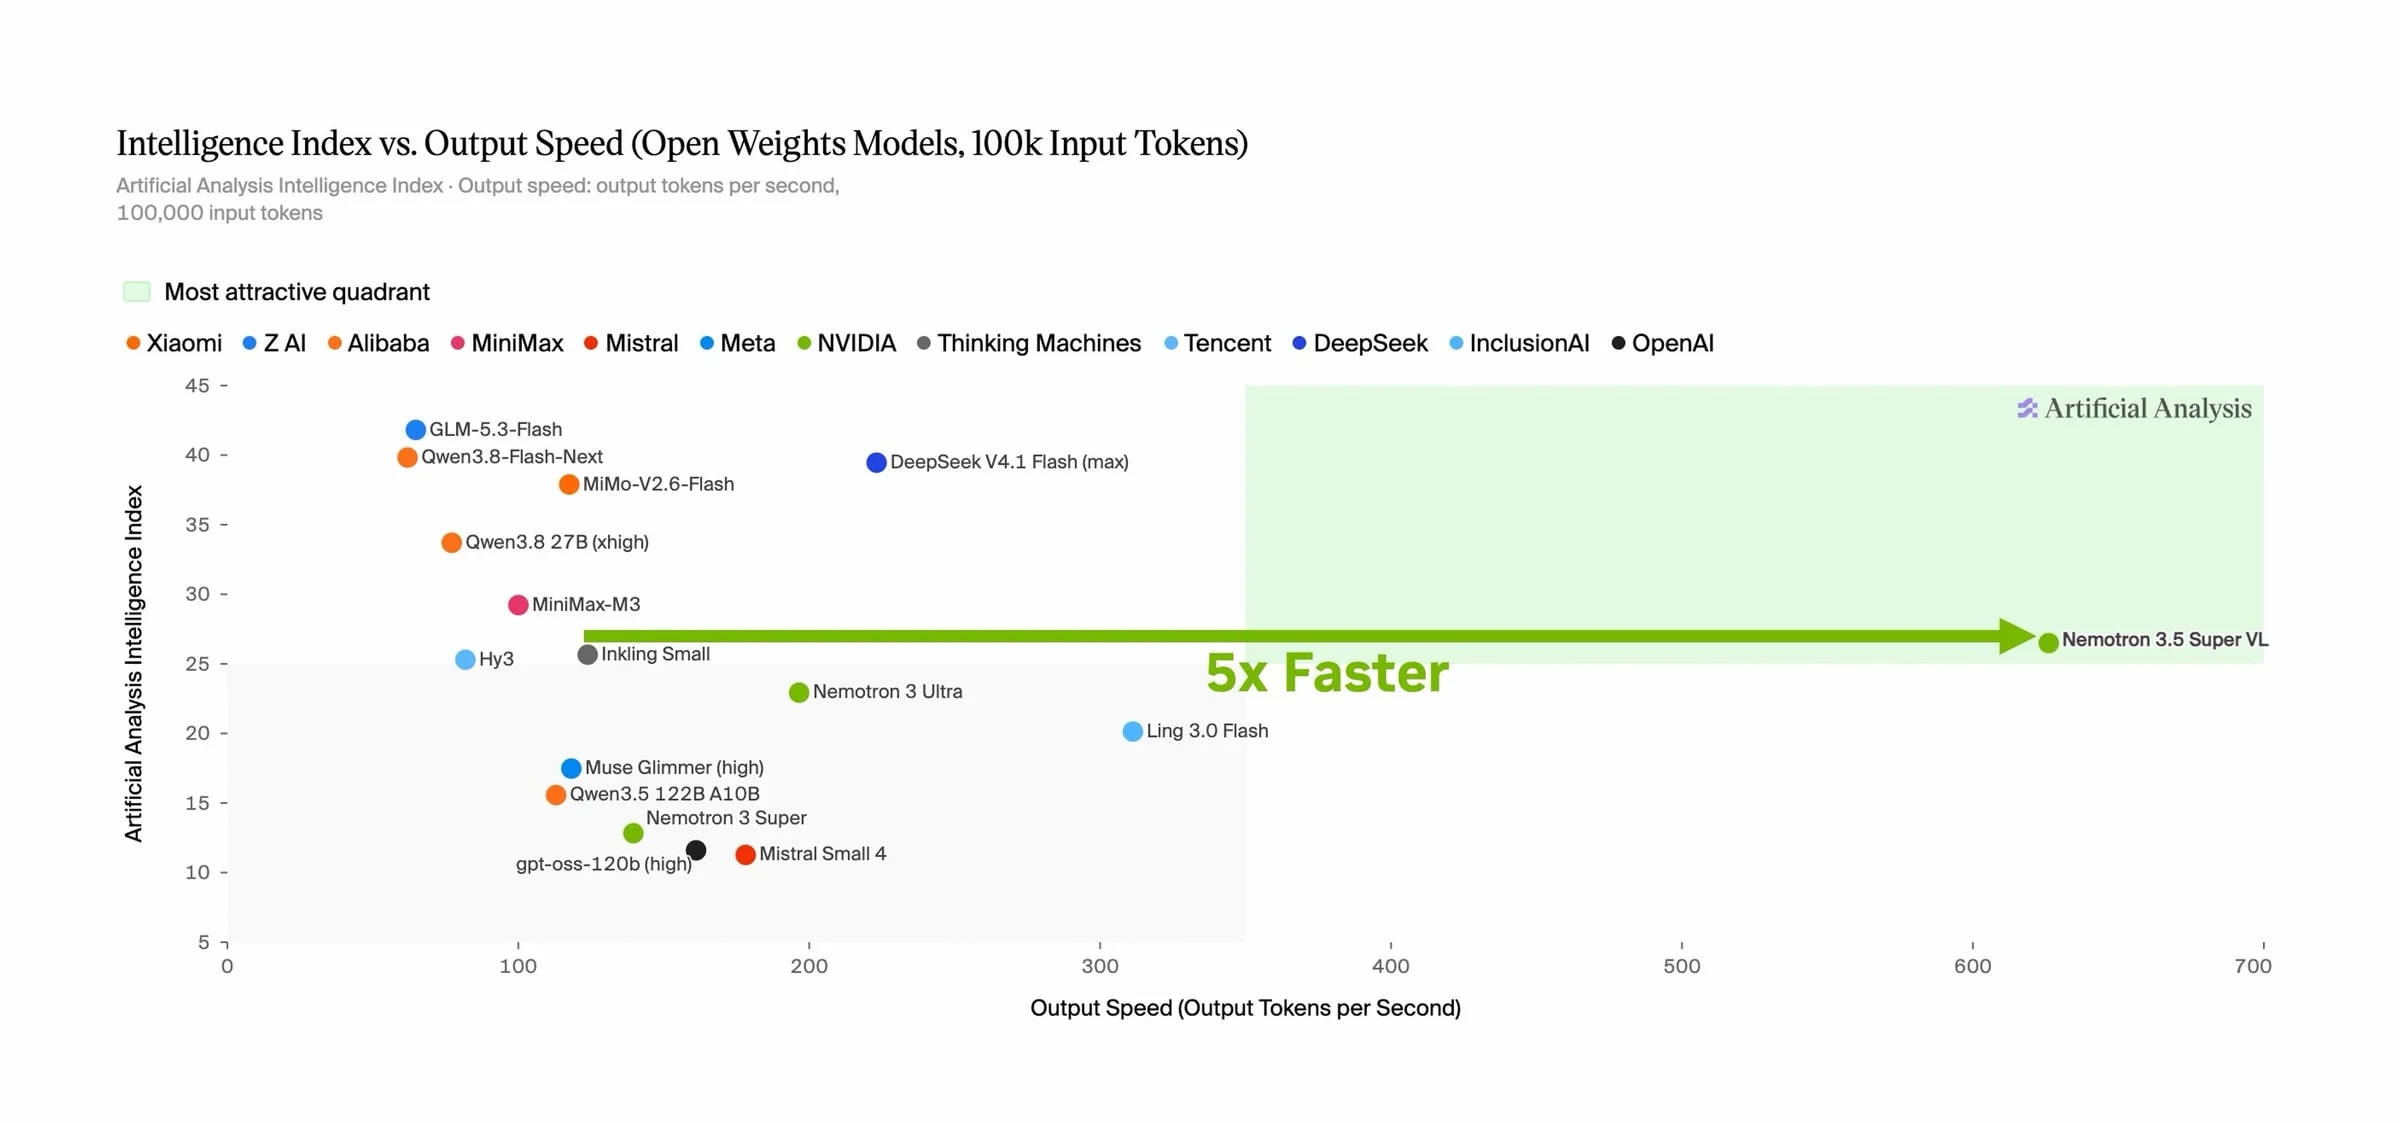
NVIDIA says Super VL is comparable in accuracy with its largest reasoning model at about one-fifth of the parameters, and five times faster than the next-best open model in its class.
Bolt 74B-A9B is compressed from Super VL and stored at 2-bit precision, so it fits in 24GB and can run beside other apps on RTX PCs, DGX Spark and NVIDIA’s RTX Spark laptops, which arrive on 16 October. NVIDIA ranks it the top open model in its class on PinchBench. Bolt E4B, which needs 4GB, follows on 23 October for voice assistants and devices such as Jetson.
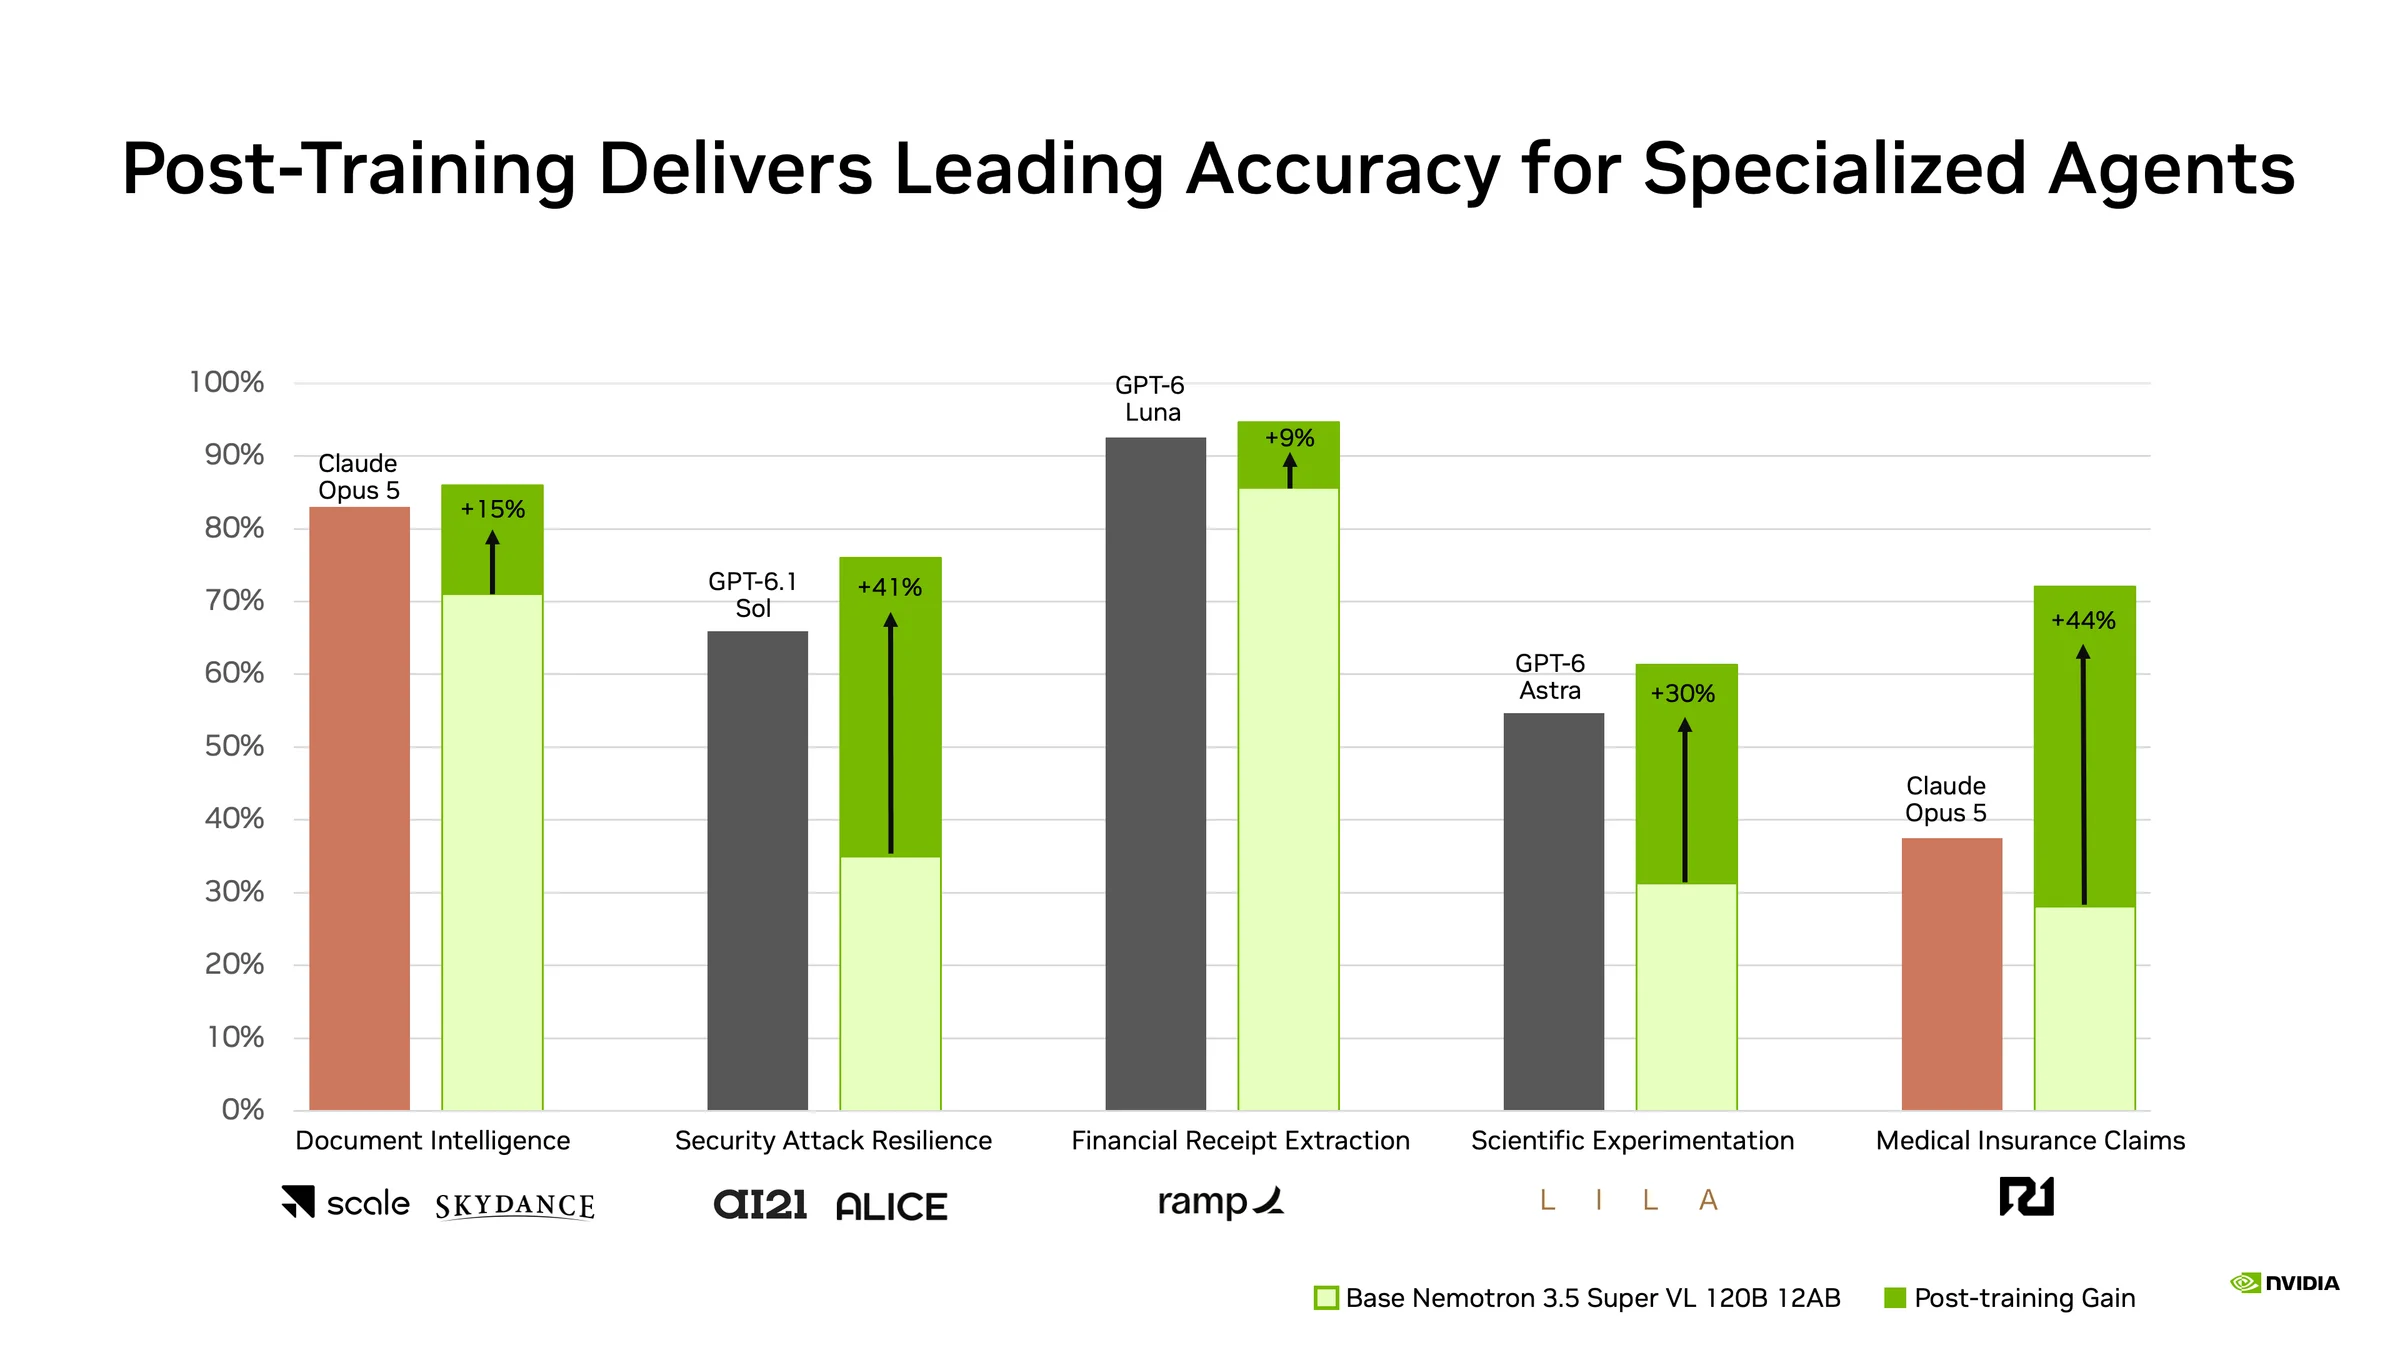
Super VL comes with open weights, open datasets and training recipes, and both released models use the OpenMDW-1.1 licence. Super VL is on Hugging Face, OpenRouter and ModelScope and as an NVIDIA NIM microservice, and companies including Scale AI, Ramp and CrowdStrike are customising it with their own data. NVIDIA’s announcement lists no prices.
Sources
- PrimaryOpen From Data Center to Desktop: NVIDIA Expands Nemotron Family With Highest Efficiency Super VL and Bolt Modelsblogs.nvidia.com · NVIDIA blog, 15 October 2026
- OfficialNVIDIA-Nemotron-3.5-Super-VL-120B-A12B-NVFP4 model cardhuggingface.co/nvidia · Parameters, context window, inputs and licence
- OfficialNVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB model cardhuggingface.co/nvidia · Bolt’s 2-bit build, inputs and licence
- On X@nvidia on X: expanding the Nemotron family with Nemotron 3.5 Super VLx.com · NVIDIA’s launch post
The rest of the day
Read the whole day
01ResearchGoogle
Google shows magic state cultivation working on its Willow quantum chip
In a paper published in Science, Google’s researchers show their 2024 filtering method producing purer magic states, a costly resource that useful quantum computers depend on.
02Open sourceMeta
Meta releases Muse Spark Open, an 816B-parameter open-weight model
Developers can download the weights of Meta’s coding and agent model under a licence with limited commercial terms, and Meta says two Mac Studios can run it.
04Open sourceStepFun
StepFun releases open weights for Step 5 Preview, a 600B agent model
The model, which StepFun says is particularly strong at finance work, can be used commercially for free, with extra terms for device makers and the largest products and model sellers.
05Coding agentCognition
Cognition launches Devin Oncall to investigate production alerts and incidents
The on-call version of Cognition’s Devin agent, now generally available, triages alerts and bug reports and joins incident channels to help engineers find the root cause.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X