

Open sourceDeepSeekConfirmed
Story 1 of 6 in the Saturday 17 October editionDeepSeek releases DeepSeek-V4.1-Flash-1017 with MIT-licensed open weights
DeepSeek says the minor update to DeepSeek-V4.1-Flash does better on reasoning, coding, agent and vision tests while finishing tasks faster with shorter outputs, and it now serves every Flash request in DeepSeek’s API.

 Edited by Ashutosh Shrivastava
18 Oct 2026, 09:39 IST · 2 min read
DeepSeek announced DeepSeek-V4.1-Flash-1017 on X at 14:05 IST on 17 October 2026, as a minor update to DeepSeek-V4.1-Flash, which came out on 10 September. It is live on DeepSeek’s website, app and API, and its weights are on Hugging Face and ModelScope under the MIT licence, which allows commercial use, modification and redistribution.
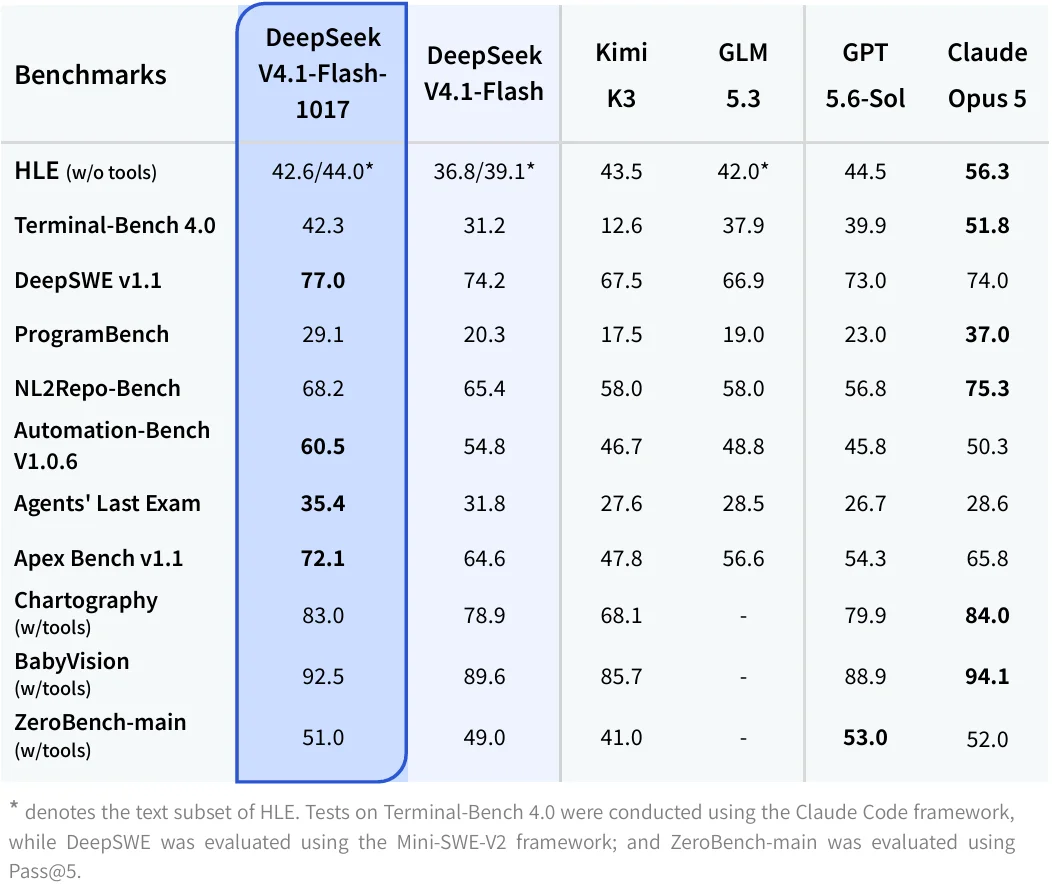
DeepSeek says it trained the update to build complete projects by learning from feedback on its own attempts, and its examples include a 3D model of the Forbidden City and a Portal 2 recreation in the Godot engine. In DeepSeek’s own table, it leads four of eleven tests, including DeepSWE v1.1 for software engineering, while Claude Opus 5 leads six.
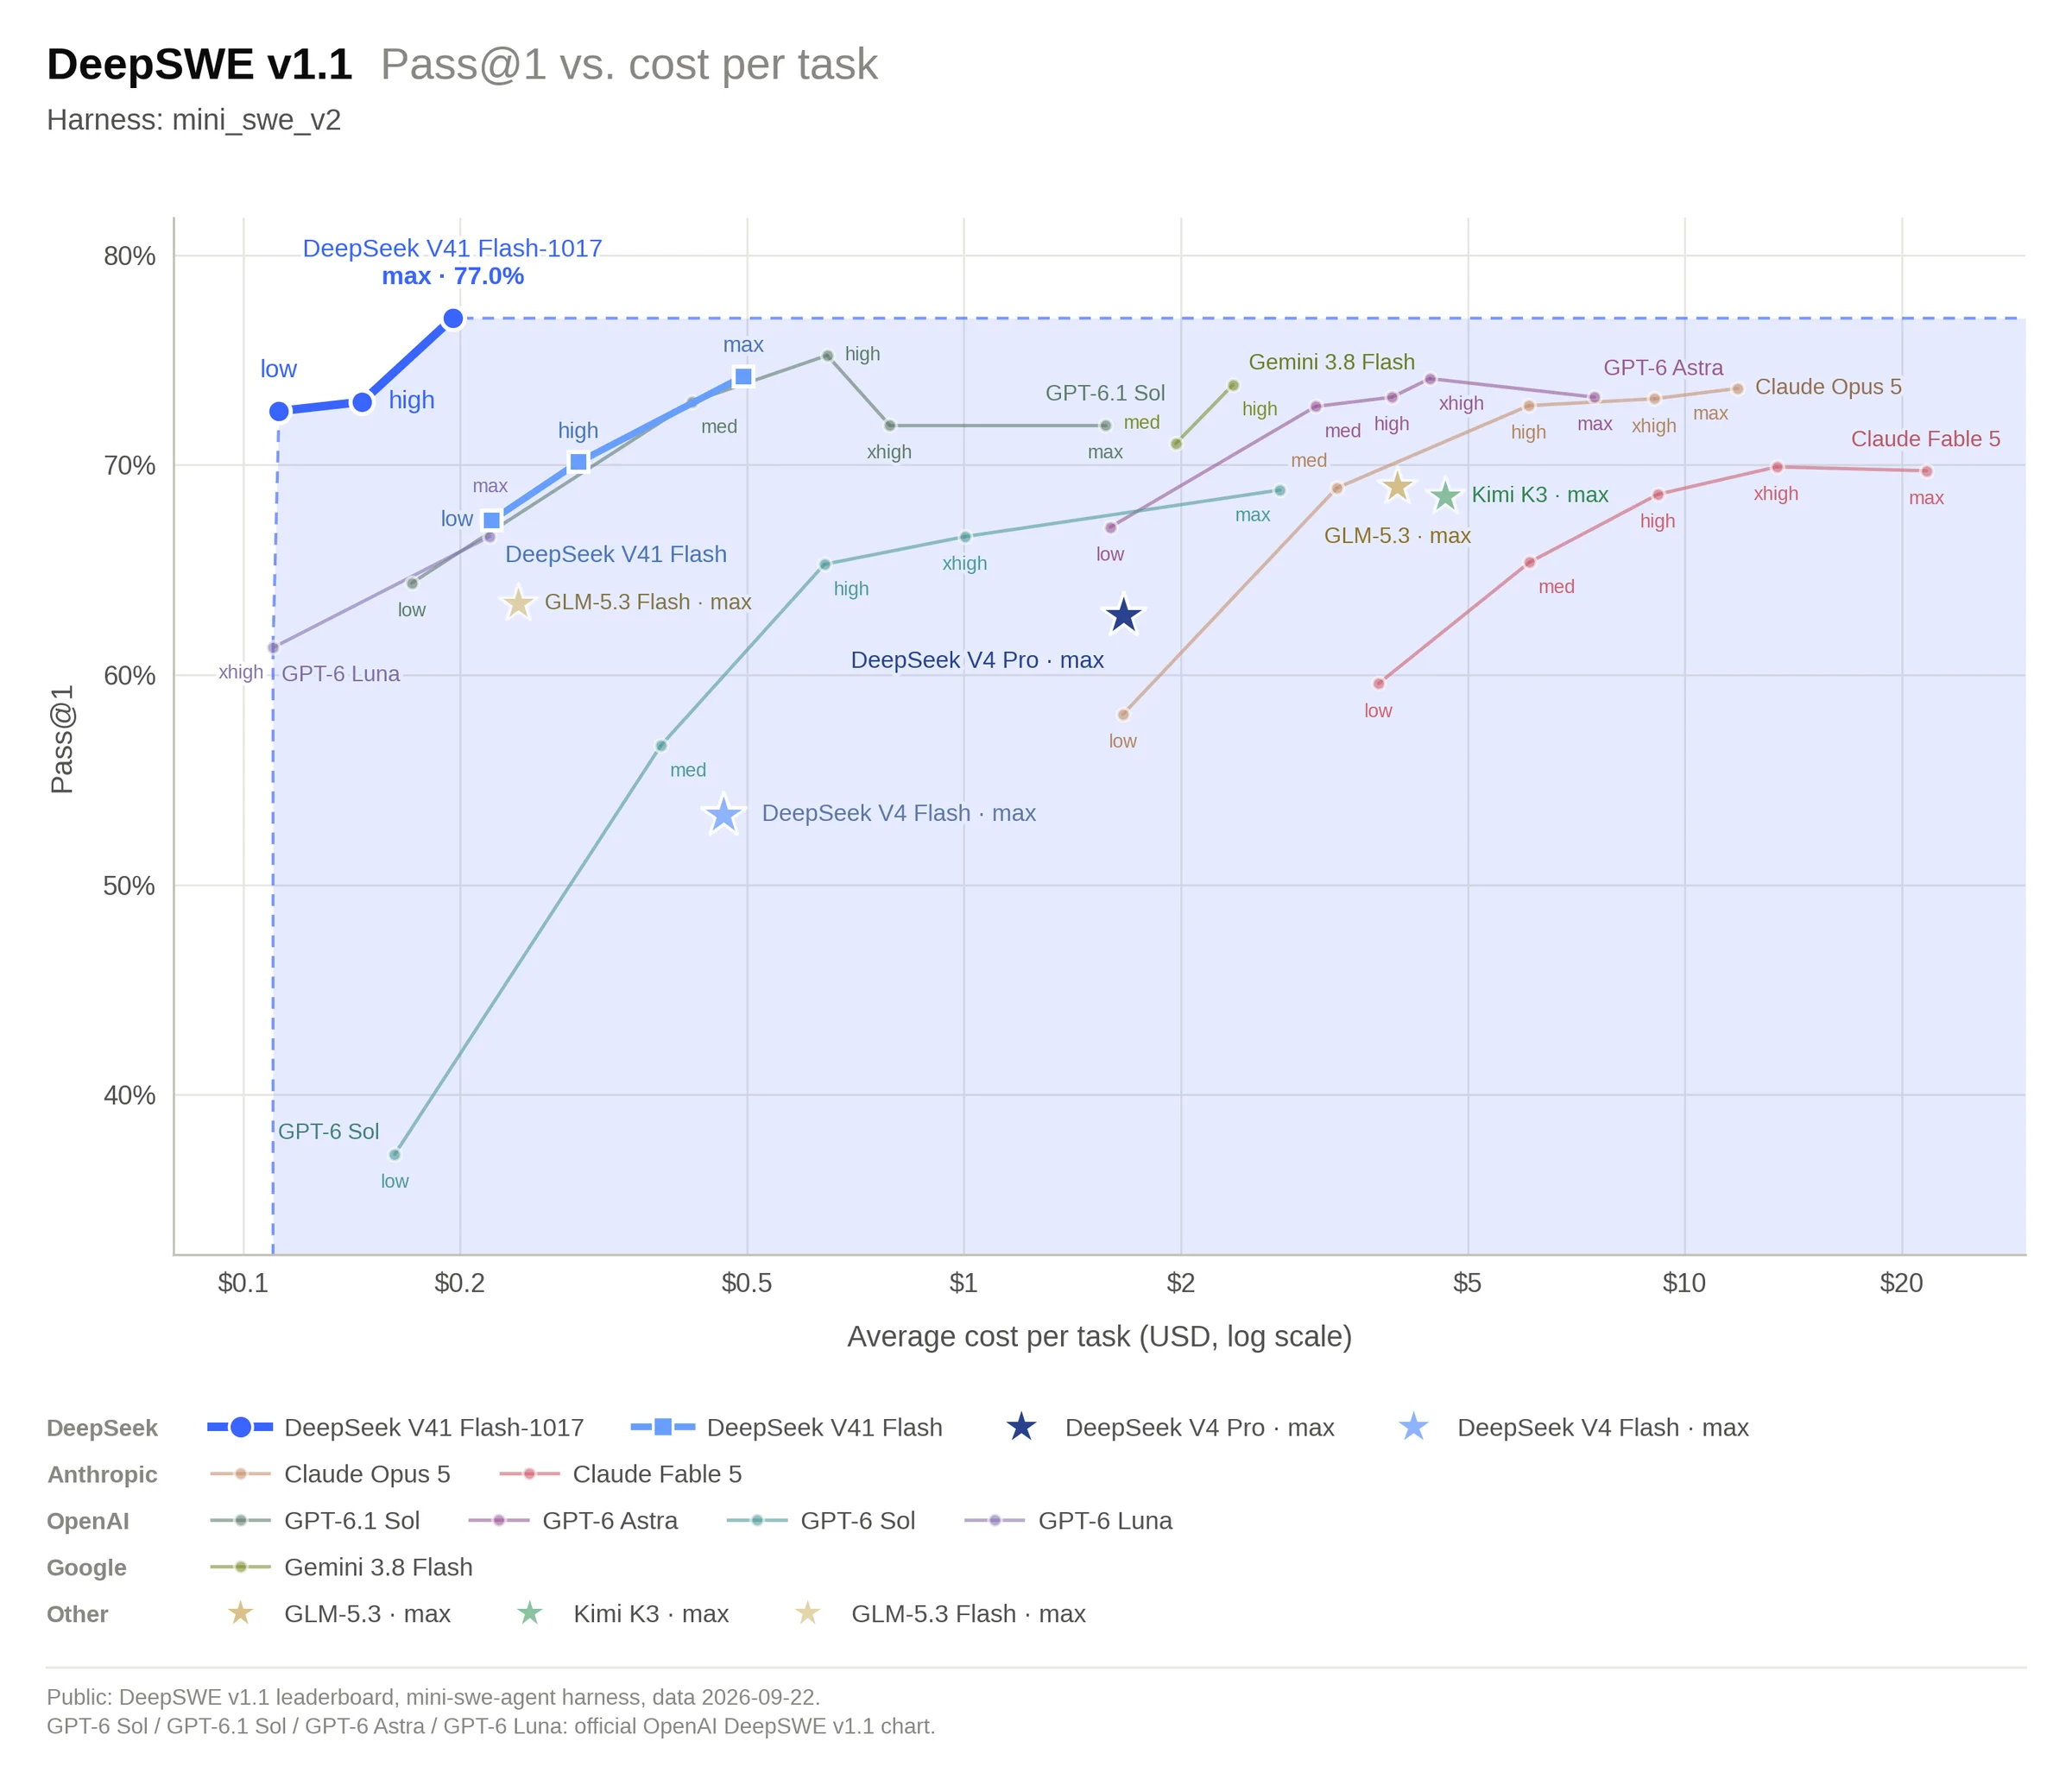
DeepSeek’s cost chart for DeepSWE v1.1 shows it scoring highest at one of the lowest costs per task.
The checkpoint has 763B parameters on Hugging Face, the same as DeepSeek-V4.1-Flash, whose model card describes a mixture-of-experts design, which uses only part of the network for each token: 16B parameters when generating.
In the API
Developers call it as deepseek-flash. The older names deepseek-v4-flash and deepseek-v4-flash-vision-exp still work, but their models are retired and their requests now go to the new model, billed at the Flash price. It offers thinking and non-thinking modes, tool calls and image input. DeepSeek optimised it for DeepSeek Harness, Tencent CodeBuddy and WorkBuddy, and recommends DeepSeek Harness v0.2.1-rc.1 or later.
Key numbers
- Input: $0.15 per million tokens off-peak and $0.30 at peak, or $0.003 and $0.006 for cached input
- Output: $0.60 per million tokens off-peak and $1.20 at peak
- Context: 1M tokens, with up to 384k tokens of output
- Search and Fetch: $0.75 per 1,000 calls each
Peak hours are 06:30 to 09:30 and 11:30 to 15:30 IST on weekdays, outside Chinese public holidays. DeepSeek also opened to everyone its Search API, which finds web pages with its own search engine, and its Fetch API, which returns a page as Markdown. Search and Fetch calls through server-side tools in DeepSeek Harness, Claude Code and Codex stay free for DeepSeek API users until 21:30 IST on 31 October 2026.
Sources
- PrimaryDeepSeek-V4.1-Flash-1017 model cardhuggingface.co/deepseek-ai · DeepSeek’s weights, MIT licence and benchmark table on Hugging Face
- OfficialDeepSeek-V4.1-Flash-1017: Wish-Driven Programming Made Realapi-docs.deepseek.com · DeepSeek announcement, 17 October 2026
- OfficialDeepSeek-V4.1-Flash-1017 on ModelScopemodelscope.cn · The same weights on ModelScope
- OfficialModels & Pricingapi-docs.deepseek.com · API model names, context length and peak and off-peak prices
- OfficialSearch & Fetchapi-docs.deepseek.com · DeepSeek’s guide to the Search and Fetch APIs
- OfficialDeepSeek-V4.1-Flash model cardhuggingface.co/deepseek-ai · The 10 September 2026 model this release updates
- On X@deepseek_ai on X: DeepSeek-V4.1-Flash-1017 is herex.com · DeepSeek’s launch post, 14:05 IST on 17 October 2026
- On X@deepseek_ai on X: Search and Fetch APIs are now open to everyonex.com · Part 3 of the launch thread
- On X@deepseek_ai on X: open-source release on Hugging Face and ModelScopex.com · Part 4 of the launch thread
The rest of the day
Read the whole day
02ProductOpenAI
OpenAI rolls out ChatGPT Slides for presentations teams edit together
Listed in ChatGPT’s release notes on 16 October 2026, Slides builds a deck from a conversation, files or an outline, and lets teammates edit it at the same time.
03ResearchAnthropic
Anthropic’s Claude finds five NIST curve seeds came from timestamps, not hashes
In a 16 October 2026 post, Anthropic says an internal research model showed in under half an hour that the unexplained seeds of five NIST elliptic curves came from a C library random number generator seeded by the clock.
04InfravLLM
vLLM speeds up Kimi K3 to 842 tokens per second on NVIDIA GB300 GPUs
Merged into vLLM on 16 October 2026, the opt-in code, developed by NVIDIA, makes Kimi K3 generate text 1.5 to 2 times faster in several tested setups on GB300 GPUs.
05Coding agentOpenCode
OpenCode says a breach tied to a distillation attack hit 1.4% of Console users
The affected users had linked outside AI providers, and OpenCode says it has emailed all of them and is working with Anthropic, OpenAI and Google on a fix.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X