

InfravLLMConfirmed
Story 4 of 6 in the Saturday 17 October editionvLLM speeds up Kimi K3 to 842 tokens per second on NVIDIA GB300 GPUs
Merged into vLLM on 16 October 2026, the opt-in code, developed by NVIDIA, makes Kimi K3 generate text 1.5 to 2 times faster in several tested setups on GB300 GPUs.

 Edited by Ashutosh Shrivastava
18 Oct 2026, 09:39 IST · 2 min read
The vLLM project described the work on its blog on 16 October 2026, the day it was merged into vLLM as pull request 61867. NVIDIA built it with help from coding agents. In Kimi K3’s decode step, where the model generates output tokens, custom GPU code written in CuTe DSL replaces almost every operation, from attention to communication between GPUs.
It supports Kimi K3 on 8 or 16 GB300 GPUs connected by NVLink, handling 1 to 64 requests at a time, and operators switch it on with the decode_backend setting latency_specialized. All changes sit in vLLM’s Kimi K3 code, and the pull request reports AIME25, GPQA-Diamond and MRCR v2 scores matching stock vLLM within about one standard error.
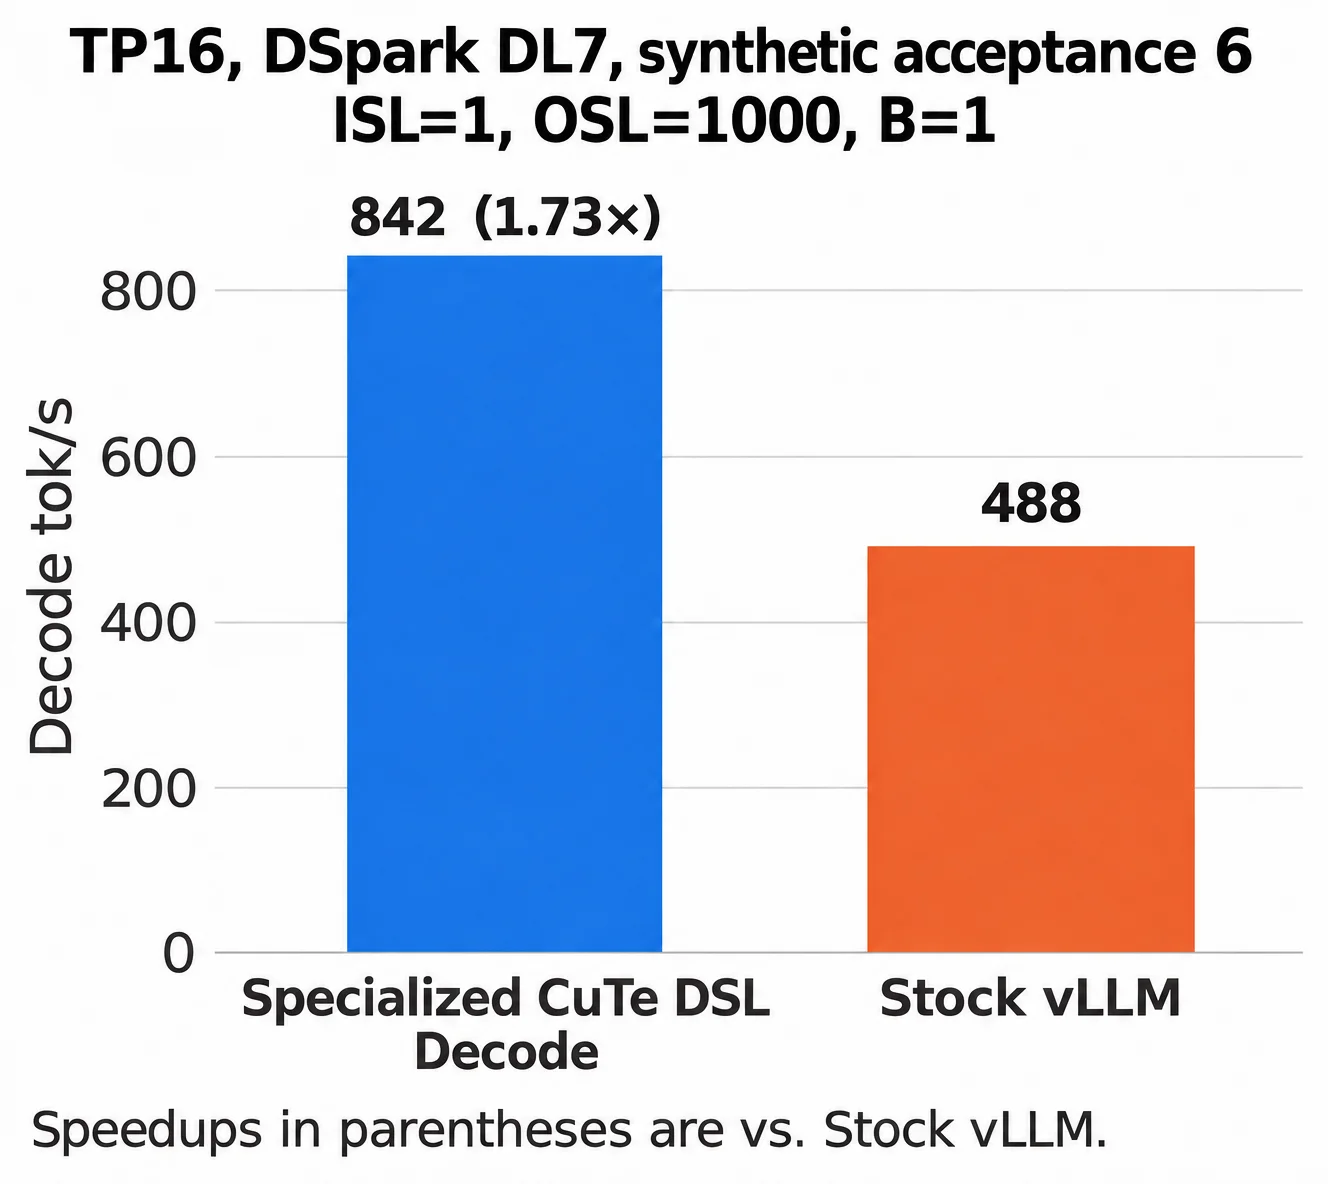
With DSpark speculative decoding, in which a draft proposes several tokens for the model to check at once, Kimi K3 reaches 842 tokens per second for a single request on 16 GPUs in vLLM’s controlled test.
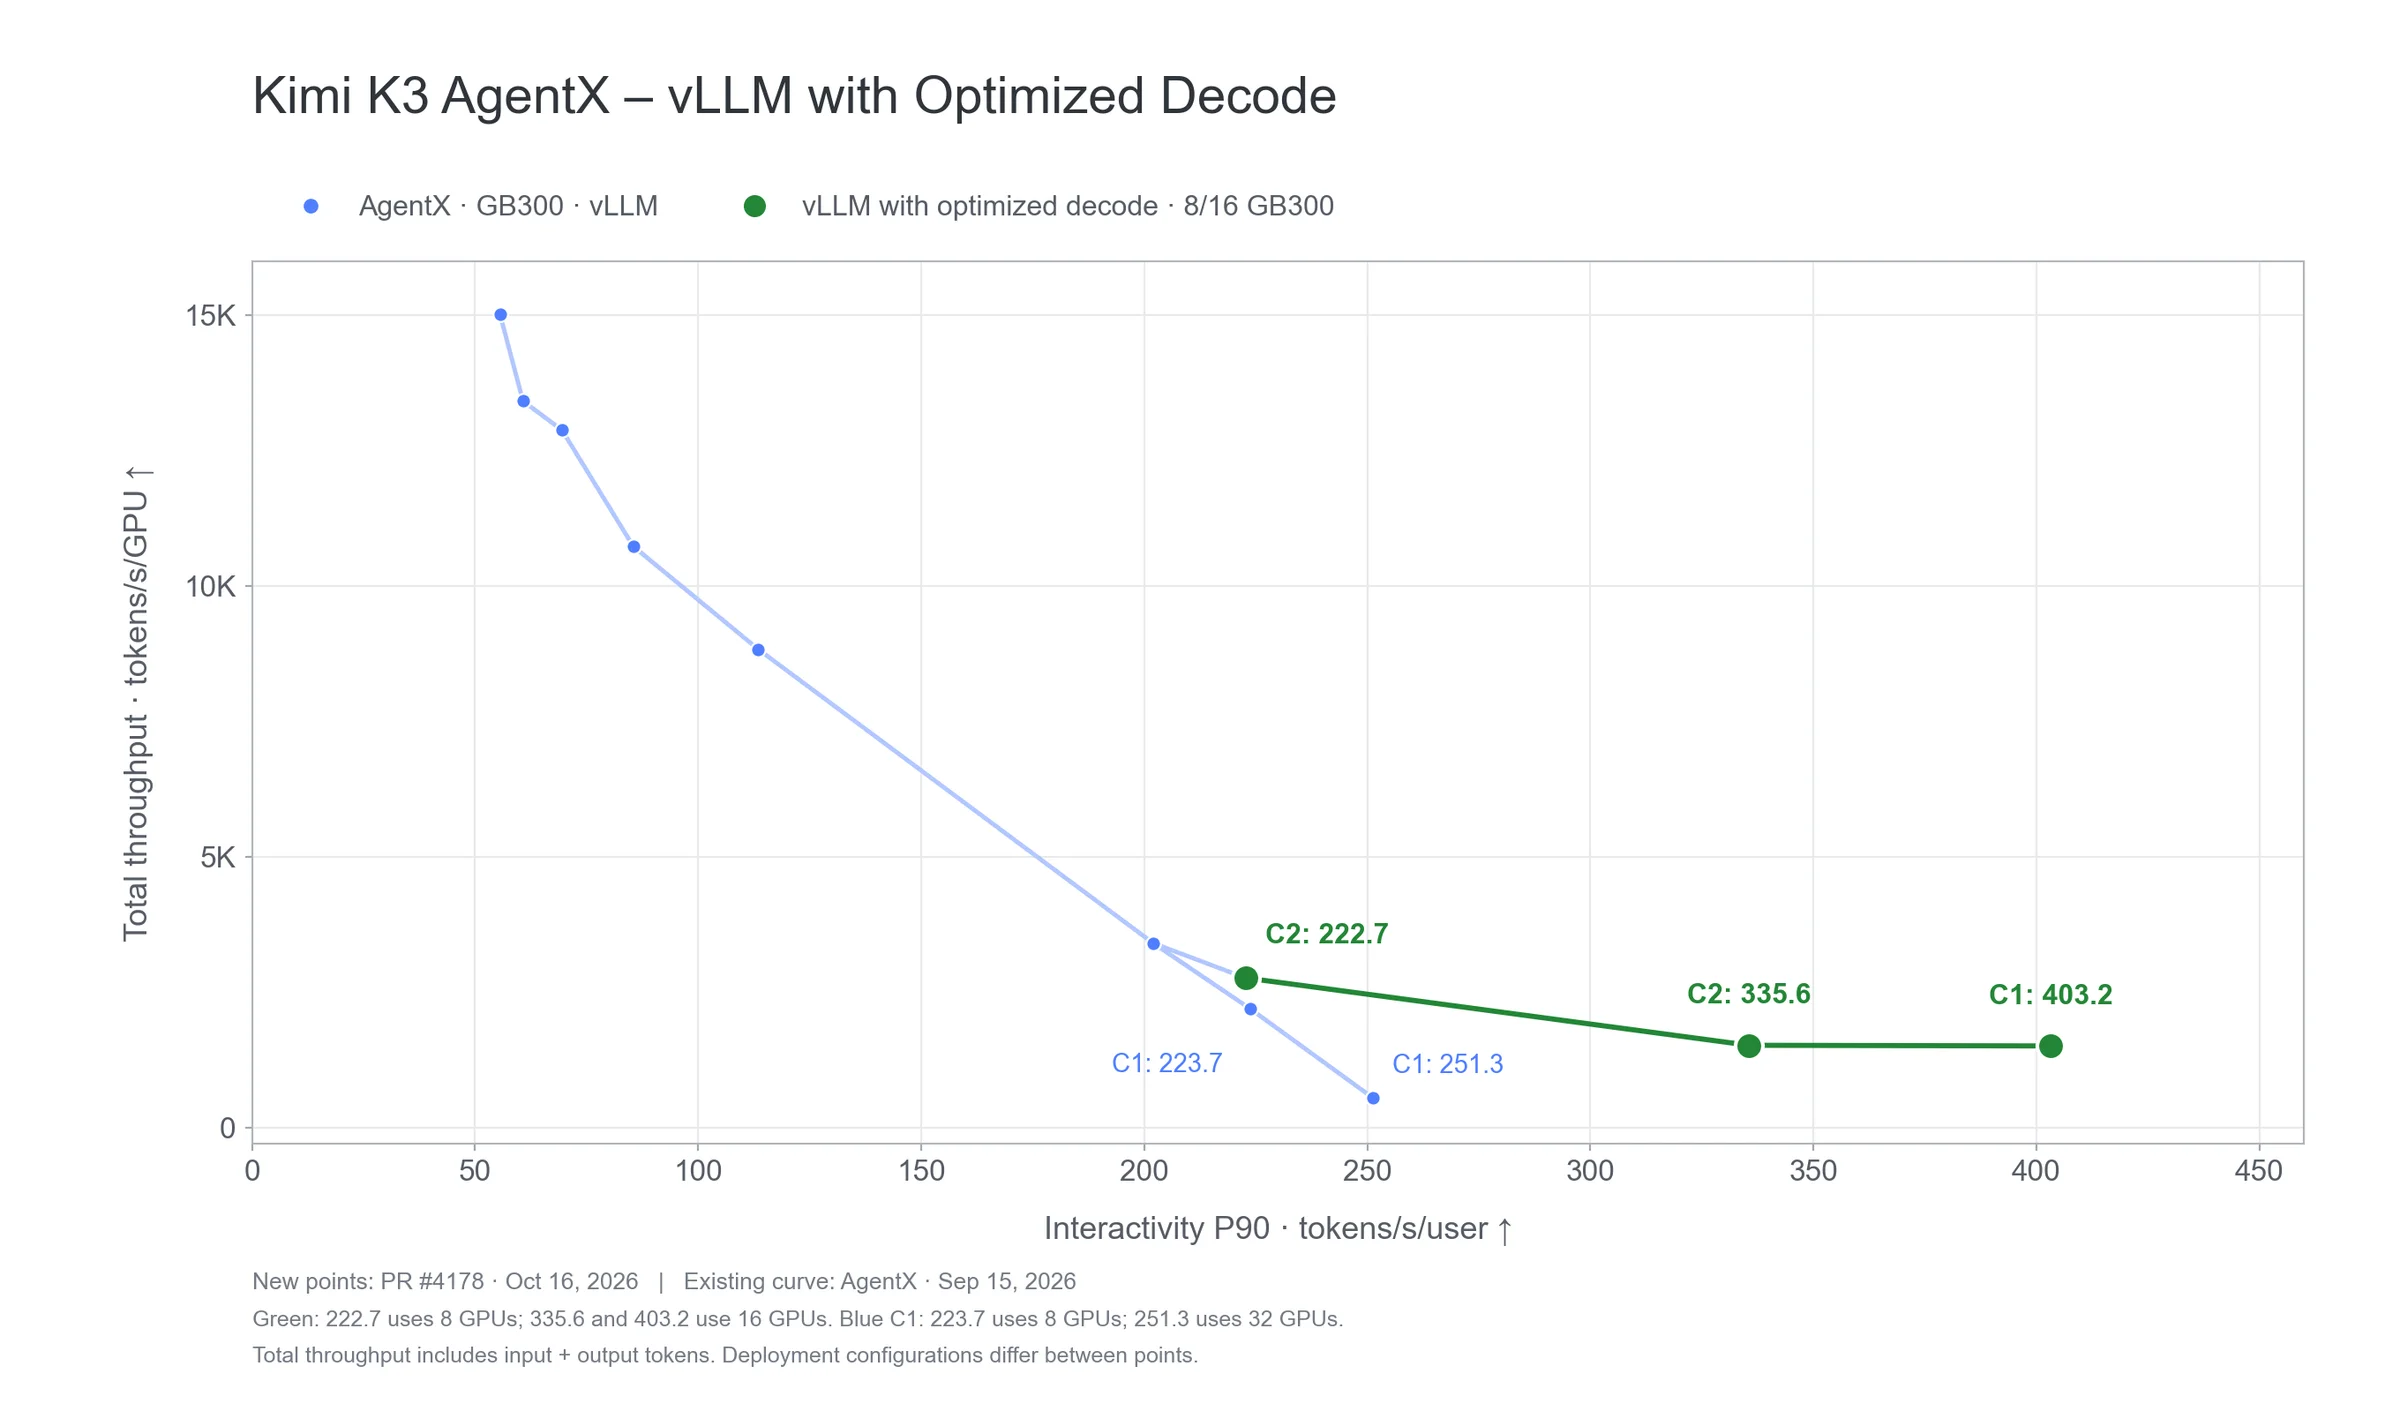
On AgentX, a SemiAnalysis benchmark that replays real coding-agent sessions, per-user speed at the 90th percentile rose 1.8 times at one concurrent request, though vLLM compares a 16-GPU run with an earlier 8-GPU result.
Validation so far covers GB300 only. A similar path for DeepSeek-V4.1-Flash is open for review as pull request 61868.
Sources
- PrimaryHyper Optimizing Kimi K3 in vLLM: Moving Fast and Responsiblyvllm.ai · vLLM blog by Benjamin Chislett of NVIDIA, 16 October 2026
- Official[Perf] Kimi K3 Specialized Decode: CuTeDSL Optimized GB300 (1.5-2x)github.com/vllm-project · The pull request, merged at 08:20 IST on 16 October 2026
- Official[Perf][DSv4.1] DeepSeek-V4.1-Flash specialized decode on GB300github.com/vllm-project · The similar path for DeepSeek-V4.1-Flash, still open
- On X@vllm_project on X: Kimi K3 decode on NVIDIA GB300 NVL72 reaches 842 tokens/s at batch 1x.com · vLLM’s launch post, 07:25 IST on 18 October 2026
- On X@SemiAnalysis_ on X: a new upstream vLLM optimisation for Kimi K3x.com · Its 423 tokens/s per user and 1.68 times differ from vLLM’s figures
The rest of the day
Read the whole day
01Open sourceDeepSeek
DeepSeek releases DeepSeek-V4.1-Flash-1017 with MIT-licensed open weights
DeepSeek says the minor update to DeepSeek-V4.1-Flash does better on reasoning, coding, agent and vision tests while finishing tasks faster with shorter outputs, and it now serves every Flash request in DeepSeek’s API.
02ProductOpenAI
OpenAI rolls out ChatGPT Slides for presentations teams edit together
Listed in ChatGPT’s release notes on 16 October 2026, Slides builds a deck from a conversation, files or an outline, and lets teammates edit it at the same time.
03ResearchAnthropic
Anthropic’s Claude finds five NIST curve seeds came from timestamps, not hashes
In a 16 October 2026 post, Anthropic says an internal research model showed in under half an hour that the unexplained seeds of five NIST elliptic curves came from a C library random number generator seeded by the clock.
05Coding agentOpenCode
OpenCode says a breach tied to a distillation attack hit 1.4% of Console users
The affected users had linked outside AI providers, and OpenCode says it has emailed all of them and is working with Anthropic, OpenAI and Google on a fix.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X