

Open sourceDeepSeekConfirmed
Story 1 of 9 in the Tuesday 20 October editionDeepSeek open-sources DeepInfer, the stack behind V4.1-Flash
DeepInfer is the inference framework behind DeepSeek’s production service, released under Apache 2.0, with a separate library for turning API requests into tokens.

 Edited by Ashutosh Shrivastava
21 Oct 2026, 10:22 IST · 2 min read
DeepSeek published DeepInfer on 20 October 2026 under the Apache License 2.0. The repository describes it as the inference framework that powers DeepSeek’s large-scale production services. The supported model is DeepSeek-V4.1-Flash, and DeepSeek’s post says that is the model it is serving at scale. The release is an offline inference stack: optimised kernels, several ways of splitting work across chips, and options for deterministic sampling and structured output.
The supported hardware is NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs. DeepSeek says a full service still needs pieces this release does not include: a KV cache system, which is the memory of an ongoing conversation, disaggregation of prefill and decode, and load balancing across replicas. It says most of the engine work for that split is already in the code. The default checkpoint is deepseek-ai/DeepSeek-V4.1-Flash-1017.
Alongside it, DeepSeek published deepseek-recipe under the MIT licence. That library turns chat and responses requests into the prompt and token IDs a DeepSeek V4 or V4.1 model expects, and turns the model’s output back into an API response. DeepSeek’s post calls it the production token encoding and decoding used to match the official API. The caller still has to run the model, execute tools and serve HTTP.
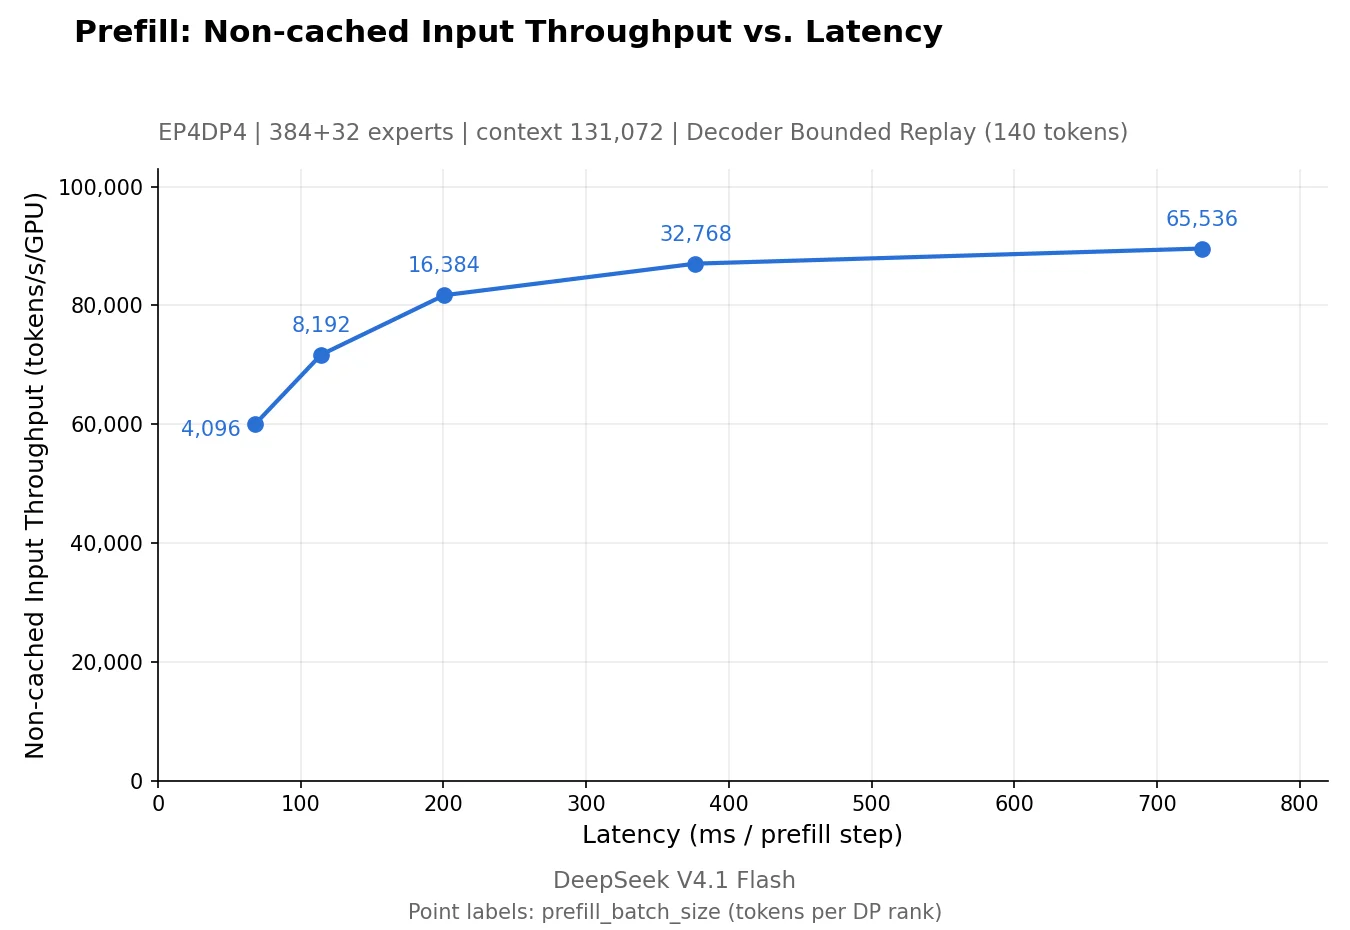
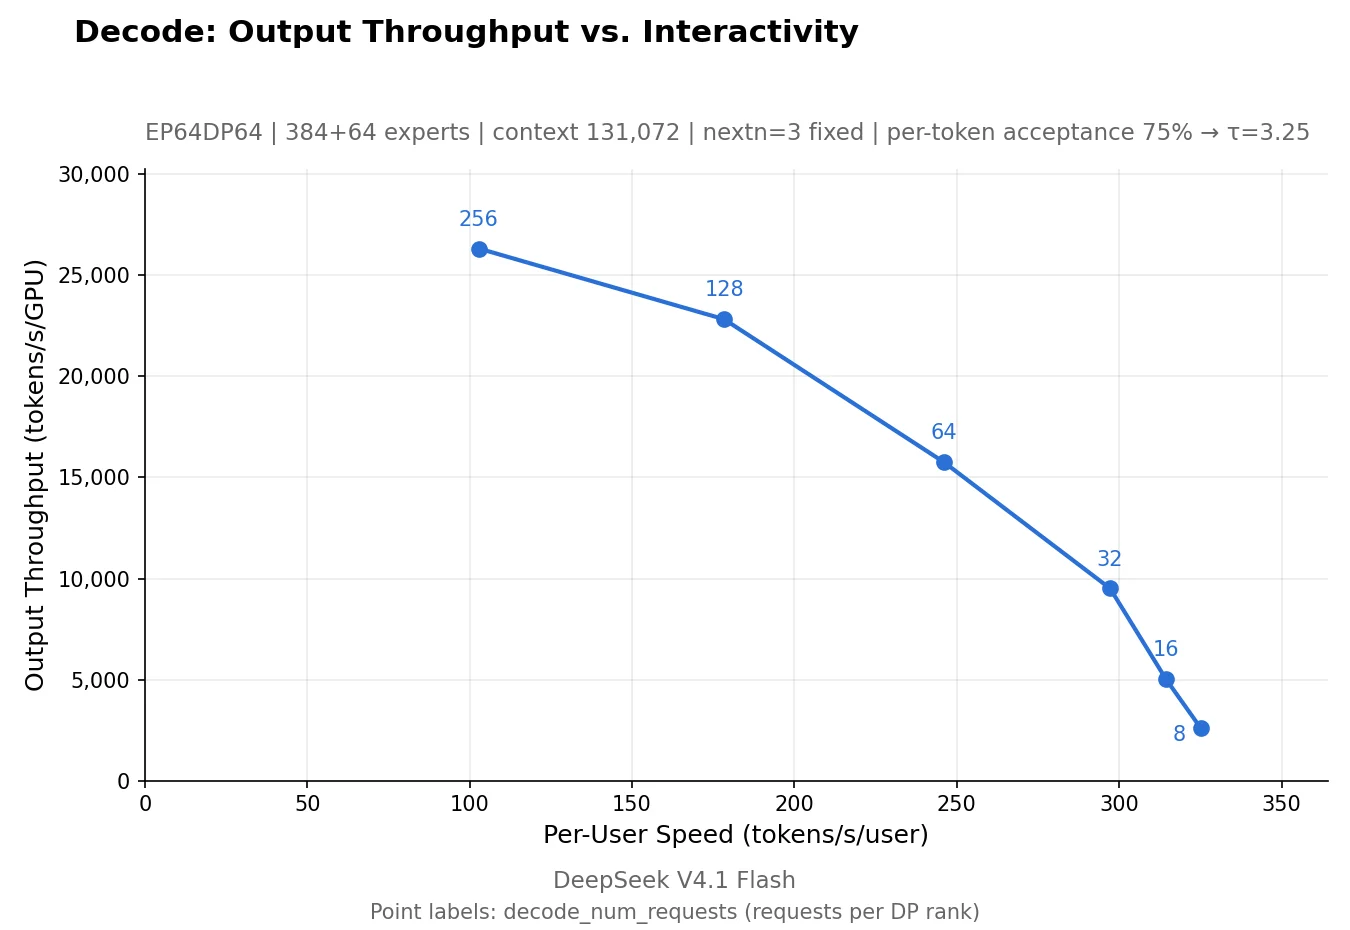
DeepSeek’s charts plot how prefill throughput trades off against latency, and how decode throughput trades off against per-user speed, for DeepSeek-V4.1-Flash.
Sources
- PrimaryDeepInfer repositorygithub.com/deepseek-ai · README, Apache 2.0, hardware and the two charts
- Officialdeepseek-recipe repositorygithub.com/deepseek-ai · Request conversion and token encoding, MIT licence
- On X@deepseek_ai on X: Introducing DeepInferx.com · Says DeepInfer is serving DeepSeek-V4.1-Flash at scale
- On X@deepseek_ai on X: deepseek-recipex.com · Calls deepseek-recipe the production token encoding and decoding
The rest of the day
Read the whole day
02ModelMistral AI
Mistral AI’s Voxtral 3 runs listening, tools and speech as one pipeline
Voxtral 3 is a family of speech-to-text and text-to-speech models plus a voice agent SDK, on Mistral’s API or arranged for a company’s own machines.
03ModelElevenLabs
ElevenLabs adds Eleven Realtime v1 Mini and Max for voice agents
Mini is the default speech-to-speech model and Max handles harder instructions.
04ProductPerplexity
Perplexity Computer can now run fully local on Apple silicon Macs
The model, the harness and the task can all run on the Mac.
05ProductGoogle
Google previews Gemini for government services for U.S. agencies
The Gemini agent is in preview for U.S.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X