

ModelMistral AIConfirmed
Story 2 of 9 in the Tuesday 20 October editionMistral AI’s Voxtral 3 runs listening, tools and speech as one pipeline
Voxtral 3 is a family of speech-to-text and text-to-speech models plus a voice agent SDK, on Mistral’s API or arranged for a company’s own machines.

 Edited by Ashutosh Shrivastava
21 Oct 2026, 10:22 IST · 2 min read
Mistral AI released Voxtral 3 on 20 October 2026: speech-to-text models, text-to-speech models and a voice agent SDK. The transcription models are Voxtral Mini Transcribe 3, Voxtral Mini Transcribe Realtime 3 and Voxtral Small Transcribe 3. The audio docs name the speech models Voxtral TTS 3 and Voxtral TTS Realtime 3. The API is on European, US and global endpoints.
The SDK, built on LiveKit, keeps listening, reasoning and speaking in one stream. Mistral says Voxtral Mini Transcribe Realtime 3 transcribes at sub-500ms and detects the end of a turn. A general model such as Mistral Small then chooses the next step and can call tools. Mistral says the stages do not wait on one another, and a turn finishes in under one second.
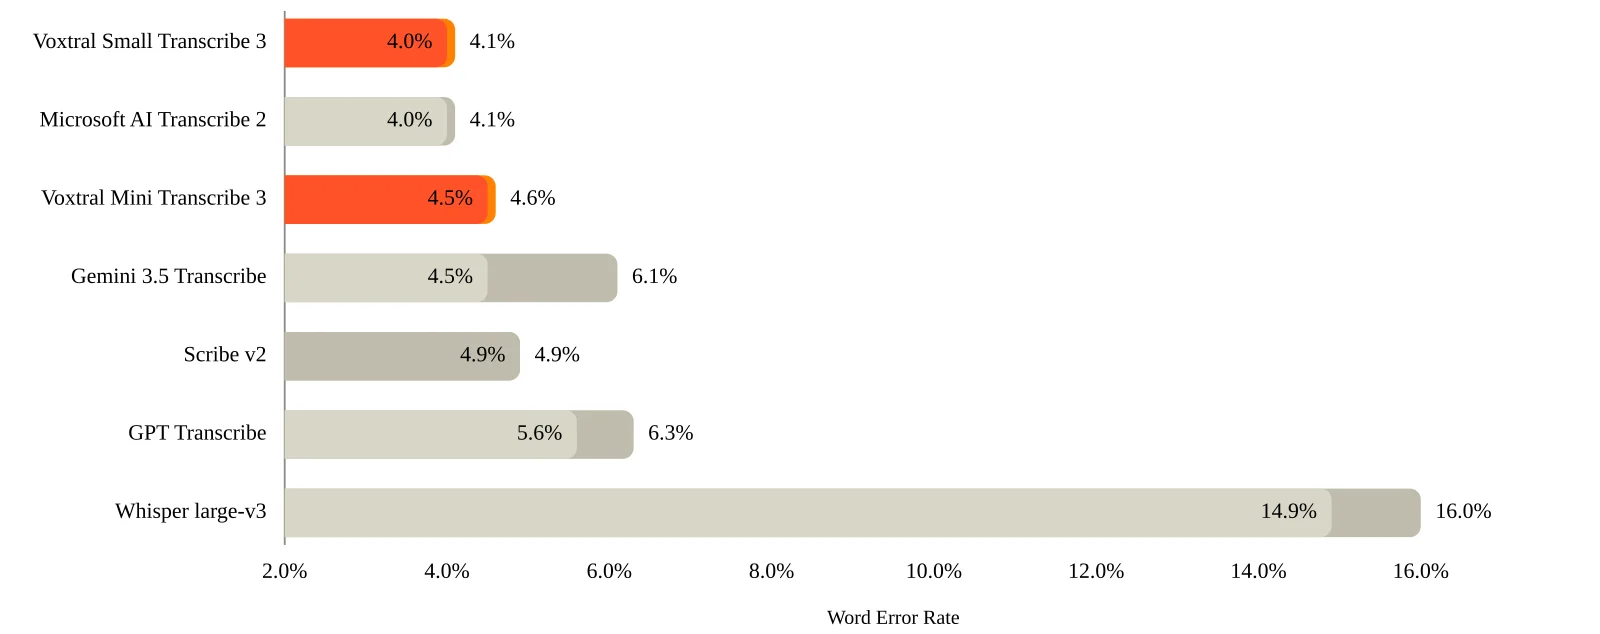
On Mistral’s FLEURS comparison for 45 languages, Voxtral Small Transcribe 3 is level with Microsoft AI Transcribe 2 and ahead of Gemini 3.5 Transcribe, Scribe v2 and Whisper large-v3.
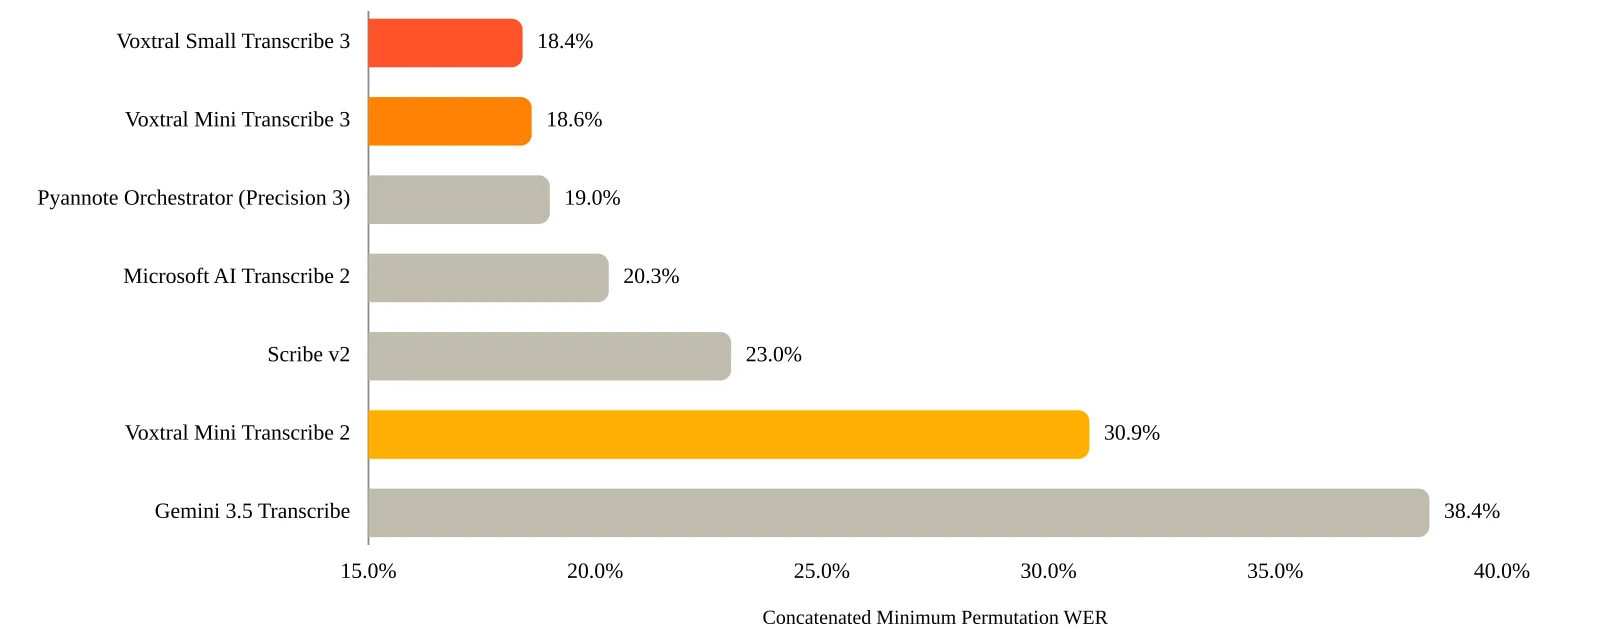
The other chart is diarization, the task of telling speakers apart.
The news post calls the speech model Voxtral Speech 3 and prices it at $13 per million characters. The price table names Mistral Small 4 for the cheaper voice-agent rate, while the pipeline text says a model such as Mistral Small. Realtime transcription is given as more than 35 languages in one place and 40 or more on a product card on the same page.
Key numbers
- Voxtral Mini Transcribe 3: 4B parameters, $0.0035 per minute in batch
- Voxtral Small Transcribe 3: $0.0040 per minute
- Voxtral Mini Transcribe Realtime 3: $0.008 per minute
- Voice agent API: $0.04 per minute with Mistral Small 4, or $0.08 with another reasoning model
Mistral has not published the weights. Its pricing page says speech models are billed per minute and does not list these rates.
Sources
- PrimaryVoxtral 3 announcementmistral.ai · Models, prices, charts and the voice agent pipeline
- OfficialAudio overviewdocs.mistral.ai · The five model names used in the docs
- OfficialPricingmistral.ai · Speech models are billed per minute
- On X@MistralAI on X: Introducing Voxtral 3x.com · Mistral’s launch post, 20 October 2026
The rest of the day
Read the whole day
01Open sourceDeepSeek
DeepSeek open-sources DeepInfer, the stack behind V4.1-Flash
DeepInfer is the inference framework behind DeepSeek’s production service, released under Apache 2.0, with a separate library for turning API requests into tokens.
03ModelElevenLabs
ElevenLabs adds Eleven Realtime v1 Mini and Max for voice agents
Mini is the default speech-to-speech model and Max handles harder instructions.
04ProductPerplexity
Perplexity Computer can now run fully local on Apple silicon Macs
The model, the harness and the task can all run on the Mac.
05ProductGoogle
Google previews Gemini for government services for U.S. agencies
The Gemini agent is in preview for U.S.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X