

ProductPerplexityConfirmed
Story 4 of 9 in the Tuesday 20 October editionPerplexity Computer can now run fully local on Apple silicon Macs
The model, the harness and the task can all run on the Mac. Pro, Max and Enterprise subscribers get it in the Perplexity Mac app, with 36 GB of memory recommended.

 Edited by Ashutosh Shrivastava
21 Oct 2026, 10:22 IST · 2 min read
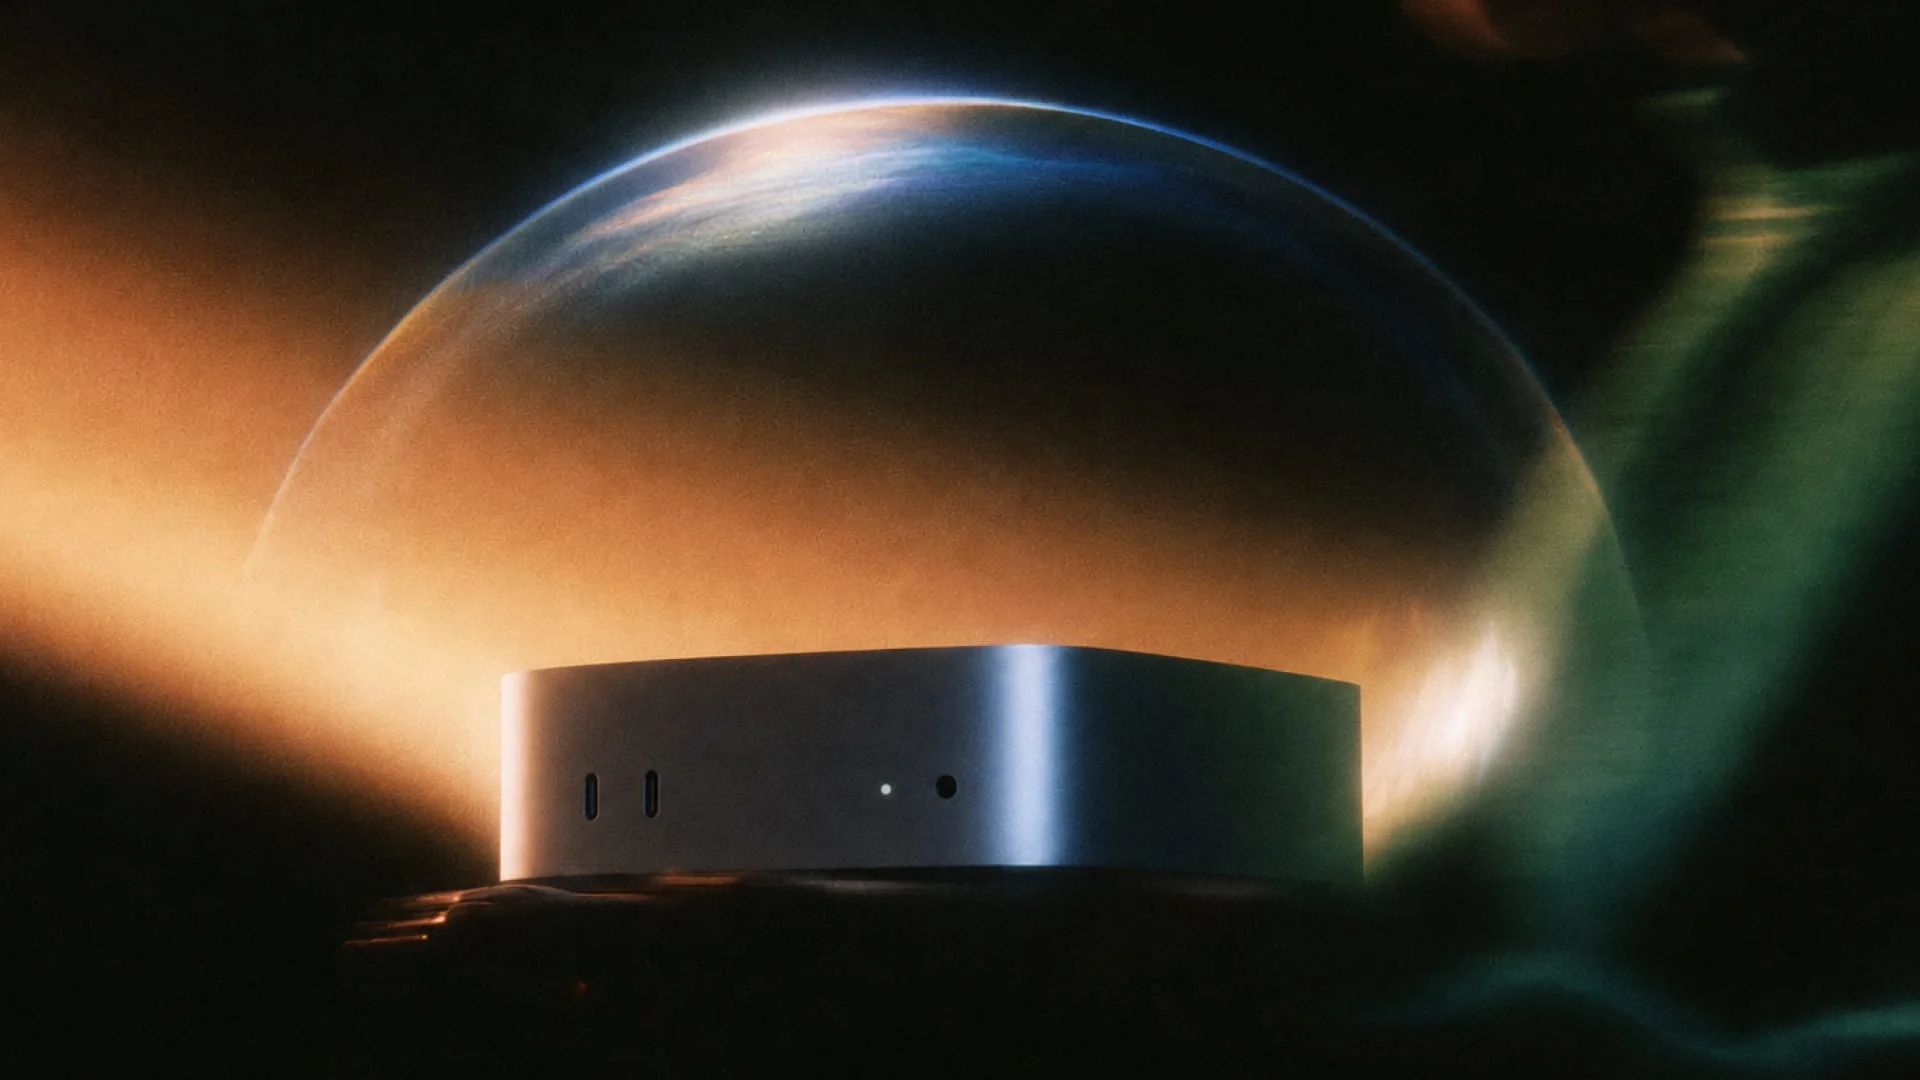
Perplexity released a fully local mode of Perplexity Computer on 20 October 2026 for Apple silicon Macs. The model, the harness and the task execution stay on the machine. With permission, Computer works across local files and apps including Notes, Messages, Mail and Numbers. The post’s examples also use Excel, Keynote and Outlook.
The Mac app has two modes. Hybrid Compute starts in the cloud and uses a local model for private files. Fully local starts on the Mac, so planning, reasoning and file processing stay there. The local models are Qwen 3.6 and PPLX Pro, which Perplexity describes as a post-trained version of Qwen. A user can still authorise the cloud for current information, browser use or connected apps, and the local orchestrator can call one of 15+ frontier models for harder reasoning.
Code and tool runs sit in isolated sandboxes, with controlled access to files and apps. Perplexity says the same controls apply to the cloud version. The mode is for Pro, Max and Enterprise subscribers. Perplexity points to Macs such as the Mac mini with M6 and M5 Pro, and recommends 36 GB of memory or more. It does not publish a full list of supported machines. Aravind Srinivas’s post says a local run uses no cloud inference and can work without Wi-Fi.
Sources
- PrimaryPerplexity Computer now runs fully local on Macperplexity.ai · Announcement, 20 October 2026
- On X@perplexity_ai on X: Computer runs fully local on Macx.com · Perplexity’s launch post, 20 October 2026
- On X@AravSrinivas on X: local Computer without cloud inferencex.com · Says a local run needs no cloud inference and can work without Wi-Fi
The rest of the day
Read the whole day
01Open sourceDeepSeek
DeepSeek open-sources DeepInfer, the stack behind V4.1-Flash
DeepInfer is the inference framework behind DeepSeek’s production service, released under Apache 2.0, with a separate library for turning API requests into tokens.
02ModelMistral AI
Mistral AI’s Voxtral 3 runs listening, tools and speech as one pipeline
Voxtral 3 is a family of speech-to-text and text-to-speech models plus a voice agent SDK, on Mistral’s API or arranged for a company’s own machines.
03ModelElevenLabs
ElevenLabs adds Eleven Realtime v1 Mini and Max for voice agents
Mini is the default speech-to-speech model and Max handles harder instructions.
05ProductGoogle
Google previews Gemini for government services for U.S. agencies
The Gemini agent is in preview for U.S.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X