

InfraFireworks AIConfirmed
Story 6 of 12 in the Tuesday 3 November editionFireworks AI unveils Blackwell ultra-fast inference, Nexus Desktop and Sovereign at Forge
Announced at its first Forge conference on 3 November 2026, the lineup spans 1,500 token-per-second previews, $8 desktop model routing, trace-driven evals and customer-hosted GPU control planes.

 Edited by Ashutosh Shrivastava
4 Nov 2026, 09:30 IST · 2 min read
Fireworks AI used its inaugural Forge conference on 3 November 2026 to launch inference, desktop routing, post-training and enterprise governance products aimed at running customised open-weight models in production.
In public preview on NVIDIA Blackwell GPUs, Fireworks Ultra-fast reaches up to 1,500 tokens per second on DeepSeek V4.1 Flash, trimming a 30-turn agent loop from 1 minute to 8 seconds. For non-urgent jobs, Background Mode halves standard token rates ($0.30 input and $1.20 output per million tokens standard for DeepSeek V4.1 Flash on the pricing page), paired with Multi-day Prompt Caching, generally available Elastic Burst rate limits and serverless LoRA serving via Specialized Model Inference starting with GLM 5.3 Flash.
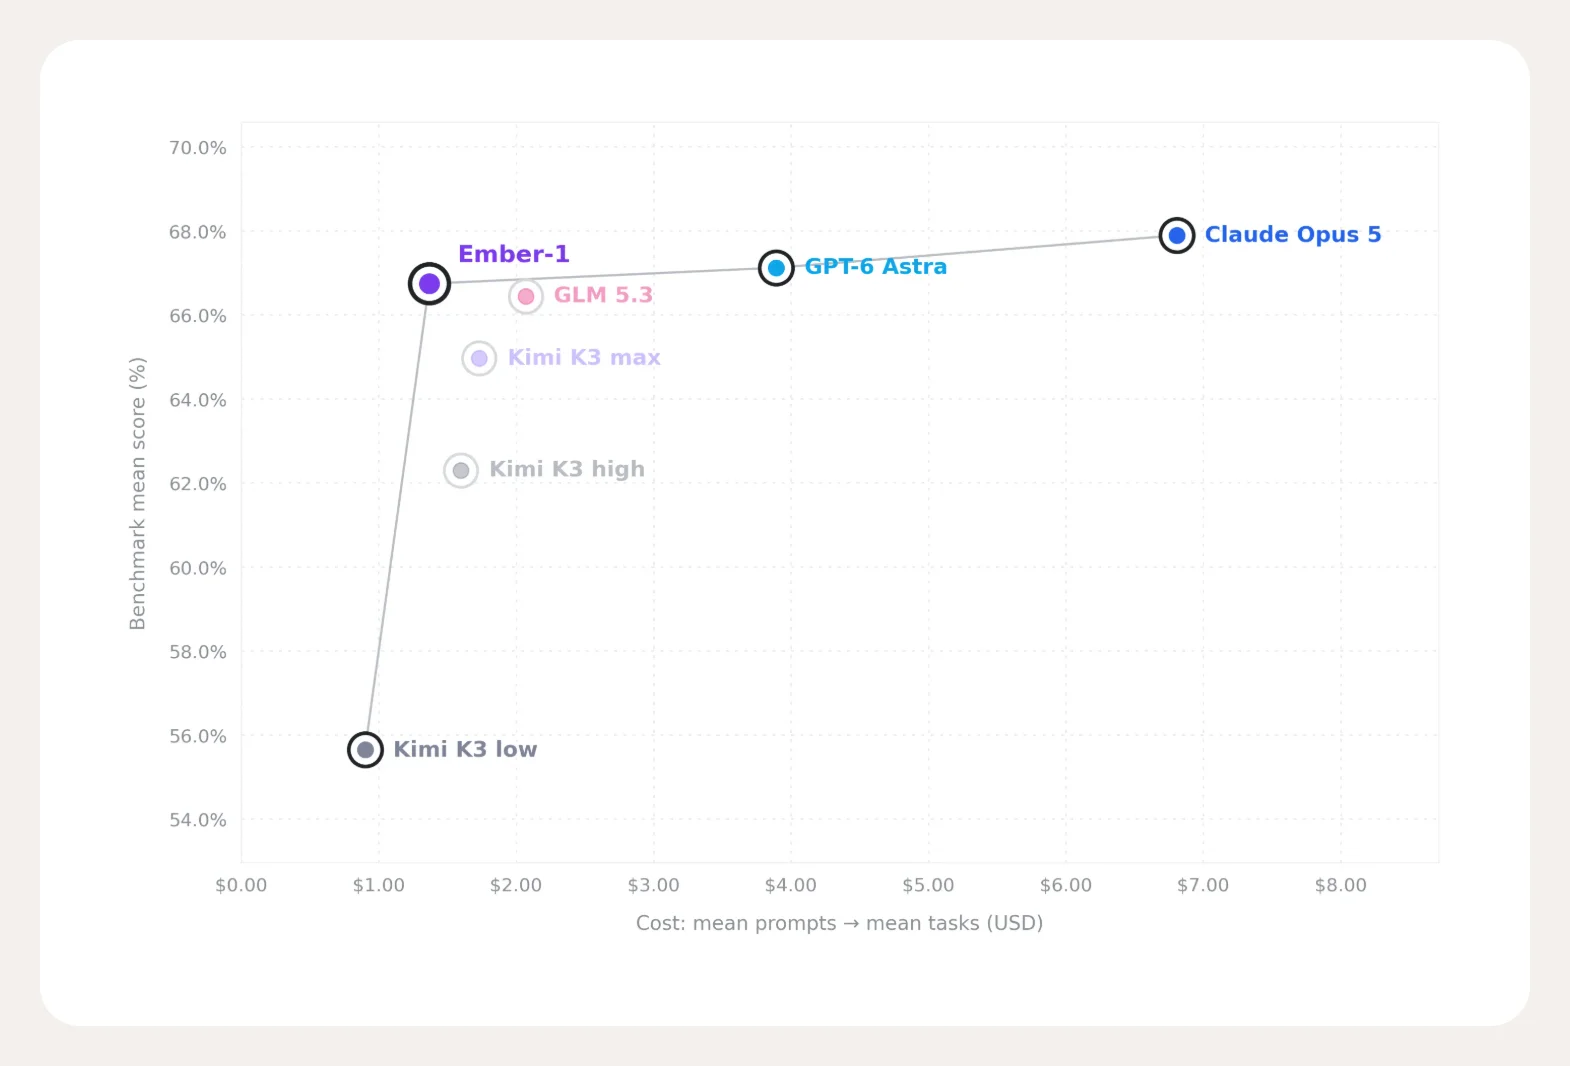
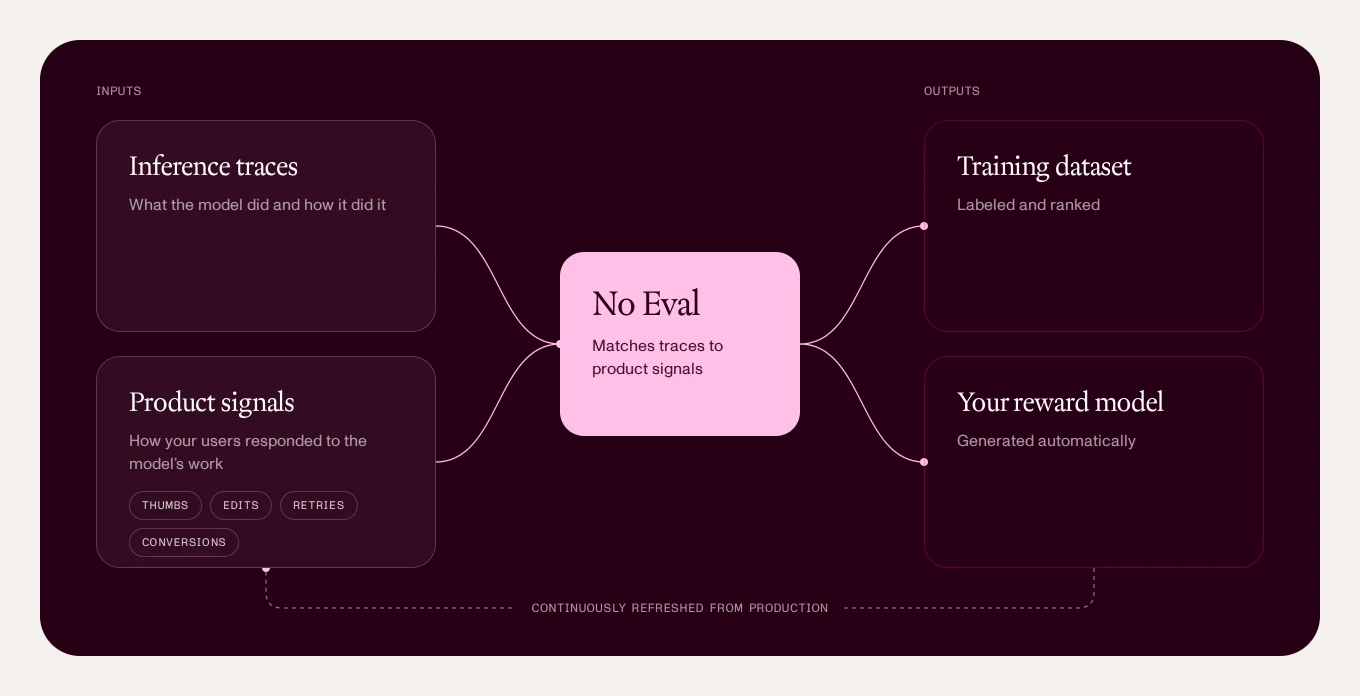
For everyday tool routing, Nexus Desktop joins the Nexus CLI inside the Codex app, Claude Desktop and OpenCode, combining open and closed models with spend tracking at $8 per month for Pro and $10 per seat per month for Teams (Team on the pricing page). On the training side, private-preview No Eval converts live inference traces and user feedback signals such as edits and retries into task evaluations and reward models, alongside free supervised, DPO and reinforcement-learning runs on Muse Glimmer 30B through 30 November 2026. For regulated organisations, private-preview Fireworks Sovereign deploys Fireworks’ control plane directly onto customer-owned cloud or data-centre GPUs, building on more than 25,000 customer-environment GPUs already under management.
Sources
- PrimaryFireworks unveils new products at Forge to help companies build specialized intelligencefireworks.ai
- OfficialFireworks AI pricingfireworks.ai
- OfficialFireworks Nexus product pagefireworks.ai
The rest of the day
Read the whole day
01ProductOpenAI
OpenAI details physical hardware engineering with GPT-6 Astra and BenchCAD 2.0
Two OpenAI engineers designed a working handheld Codex voice prototype with GPT-6 Astra in under a week, while an internal model reached 0.875 on BenchCAD 2.0.
02ProductGoogle
Google Labs expands its Dreambeans personalised storytelling app to India
Adults aged 18 and over in India can generate daily visual story cards on Android, iOS and the web across 14 languages using selected Google app context.
03Open sourceSarvam AI
Sarvam AI open-sources Sarvam Prism for 44 ms single-pass enterprise decisions
Built on Sarvam 105B under the Apache 2.0 licence, the calibrated decision model scores candidate options in one forward pass on a single NVIDIA B200 GPU.
04ModelOpenRouter
OpenRouter launches free 1M-context multimodal stealth model Crouton Alpha
Released on 3 November 2026 under stealth/crouton-alpha, the undisclosed provider’s reasoning model accepts text, image, audio, video and file inputs with zero prompt logging.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X