

ResearchMicrosoft AIConfirmed
Story 8 of 10 in the Thursday 15 October editionMicrosoft AI finishes pre-training MAI-Base-2, a 2.8T-parameter model
The unreleased base model beats every open-weight model Microsoft AI tested on its own held-out evaluations and is now being post-trained.

 Edited by Ashutosh Shrivastava
16 Oct 2026, 10:47 IST · 1 min read
Microsoft AI has finished pre-training MAI-Base-2, a mixture-of-experts model with 2.8T parameters, 80B of them active per token. Its predecessor, MAI-Base-1, has 1T parameters with 35B active and underlies MAI-Thinking-1, which the lab announced in June 2026. A base model is the raw result of pre-training, before the post-training that shapes it into a usable assistant.
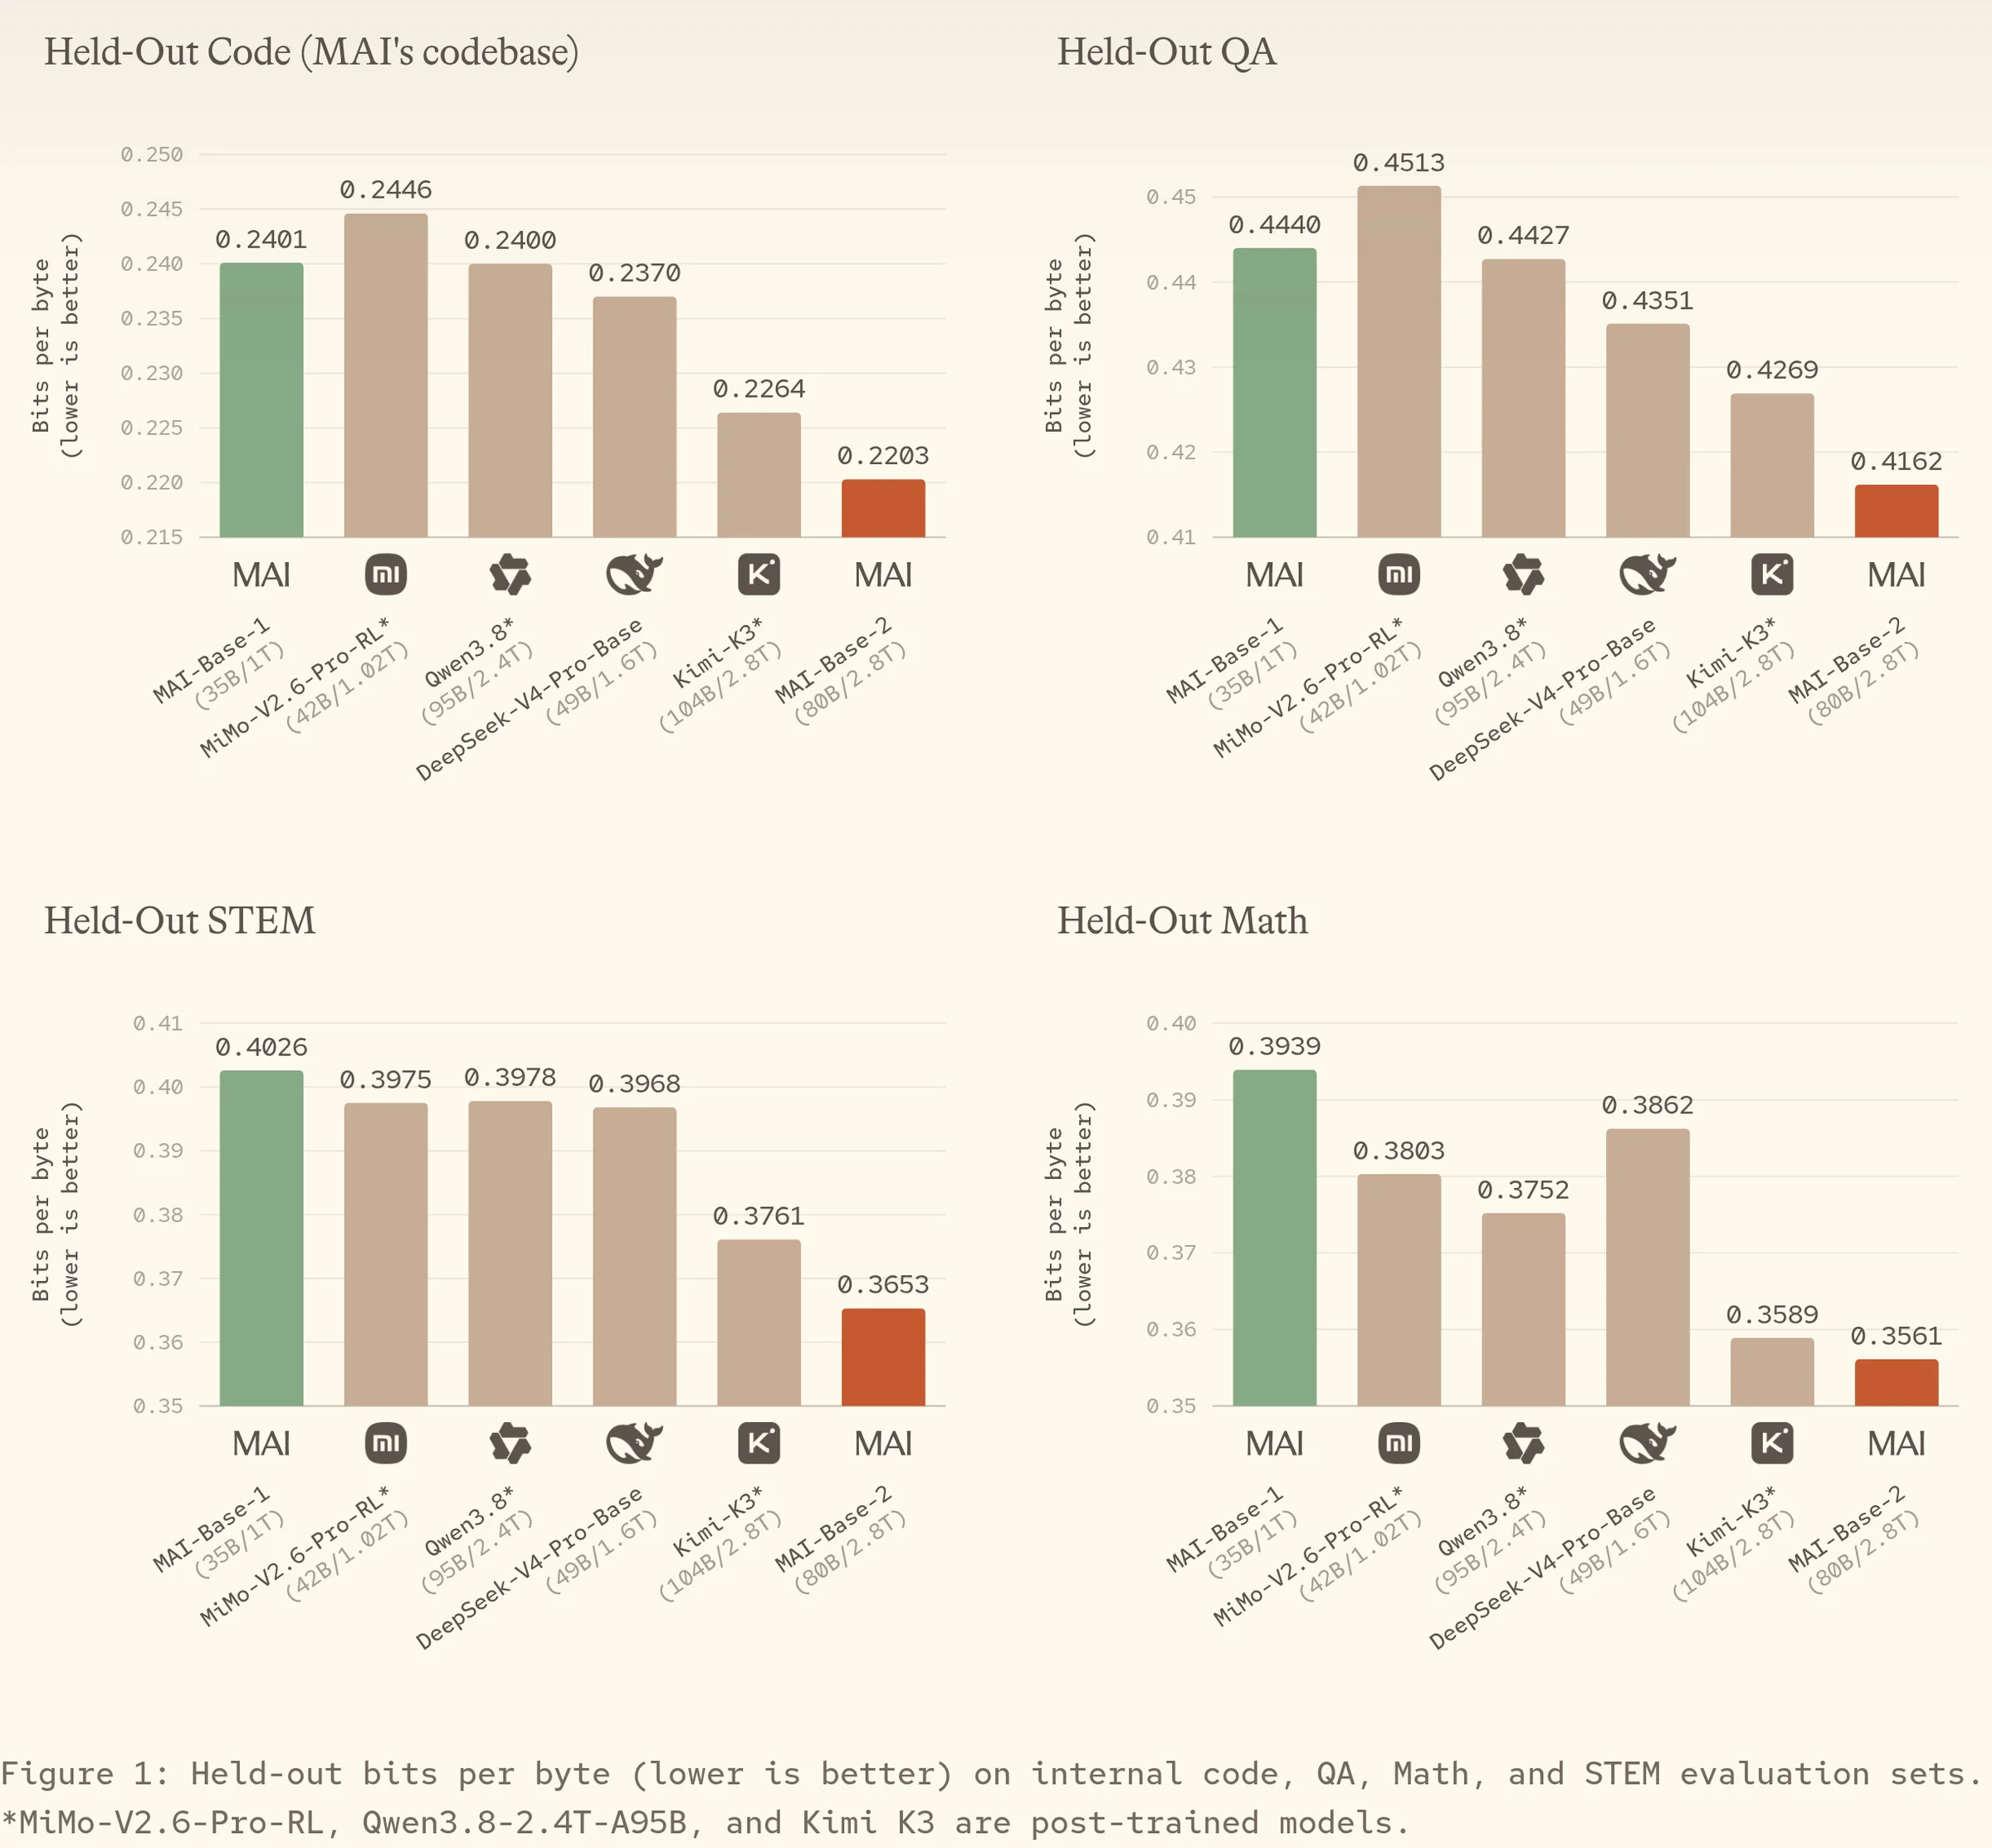
The lab tested it on held-out code, question answering, STEM and maths sets kept out of its training data, scoring bits per byte, where lower is better. MAI-Base-2 beat DeepSeek-V4-Pro-Base, the strongest open base model, and three post-trained open models, a comparison the lab says post-training may affect.
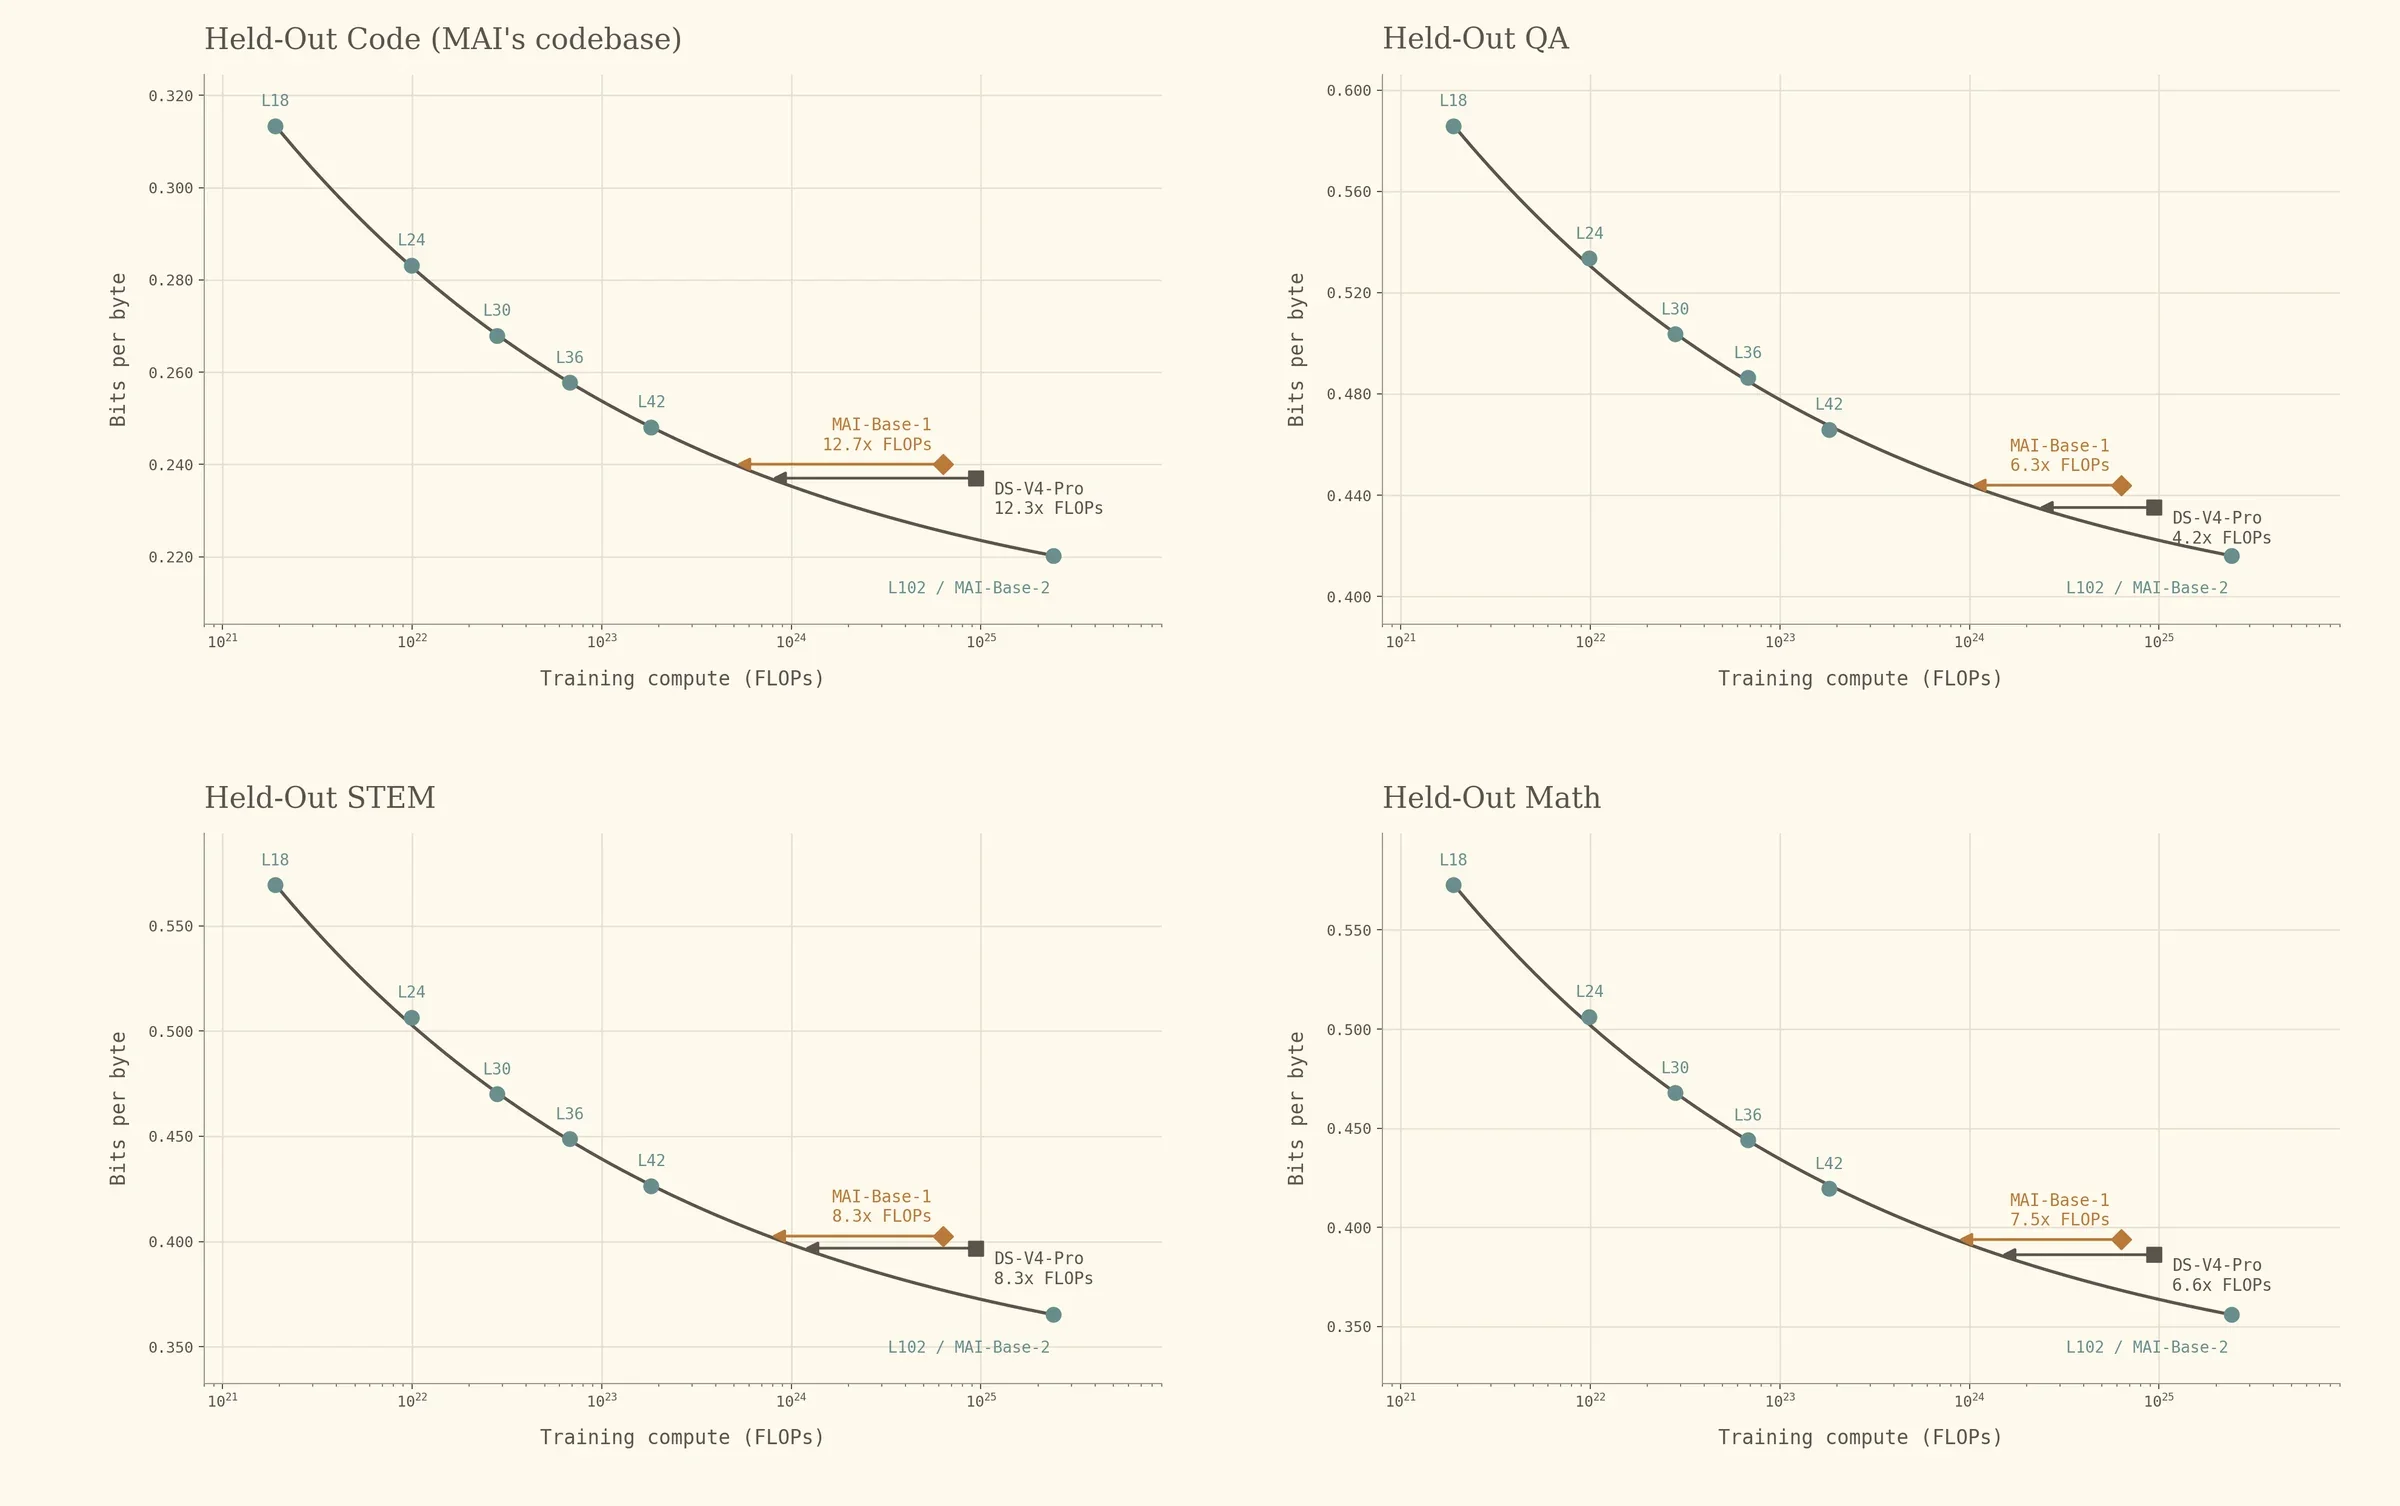
It also estimates that DeepSeek-V4-Pro-Base used 4.2 to 12.3 times the training compute that its own recipe would need for the same scores.
Training ran on 16k GB200 GPUs for 38 days in August and September 2026, on a 50T-token mixture with a March 2026 knowledge cutoff. The lab says it used no distillation from other models, and unlike its predecessor, MAI-Base-2 learned from images from the start.
Microsoft AI plans to use the model first in Microsoft’s own products and to license the weights to trusted partners through Foundry. It hasn’t given a release date or price.
Sources
- PrimaryFrontier Pre-training at Microsoft AImicrosoft.ai · Microsoft AI Lab Notes, 15 October 2026
- On X@mustafasuleyman on X: state-of-the-art pre-trained base models in the 3T-parameter weight classx.com
The rest of the day
Read the whole day
01ResearchGoogle
Google shows magic state cultivation working on its Willow quantum chip
In a paper published in Science, Google’s researchers show their 2024 filtering method producing purer magic states, a costly resource that useful quantum computers depend on.
02Open sourceMeta
Meta releases Muse Spark Open, an 816B-parameter open-weight model
Developers can download the weights of Meta’s coding and agent model under a licence with limited commercial terms, and Meta says two Mac Studios can run it.
03ModelNVIDIA
NVIDIA releases Nemotron 3.5 Super VL and Bolt open models for agents
Super VL, a 120B model that also reads images and documents, targets always-on enterprise agents, while Bolt fits a 74B model into 24GB of memory for RTX PCs and DGX Spark.
04Open sourceStepFun
StepFun releases open weights for Step 5 Preview, a 600B agent model
The model, which StepFun says is particularly strong at finance work, can be used commercially for free, with extra terms for device makers and the largest products and model sellers.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X