

InfraGoogleConfirmed
Story 7 of 9 in the Tuesday 20 October editionGoogle open-sources TorchTPU, a native PyTorch stack for TPUs
TorchTPU, co-developed with Meta’s PyTorch team, runs PyTorch on Google TPUs and is the base for new vLLM and SGLang inference engines.

 Edited by Ashutosh Shrivastava
21 Oct 2026, 10:22 IST · 2 min read
Google Cloud open-sourced TorchTPU on 20 October 2026. It is a native PyTorch stack for TPUs, co-developed with Meta’s PyTorch team, so existing PyTorch code can run on a TPU with the usual APIs. A developer can debug in eager mode, then compile with torch.compile. Tensors stay ordinary PyTorch tensors on a TPU device, and collective operations go through torch.distributed.
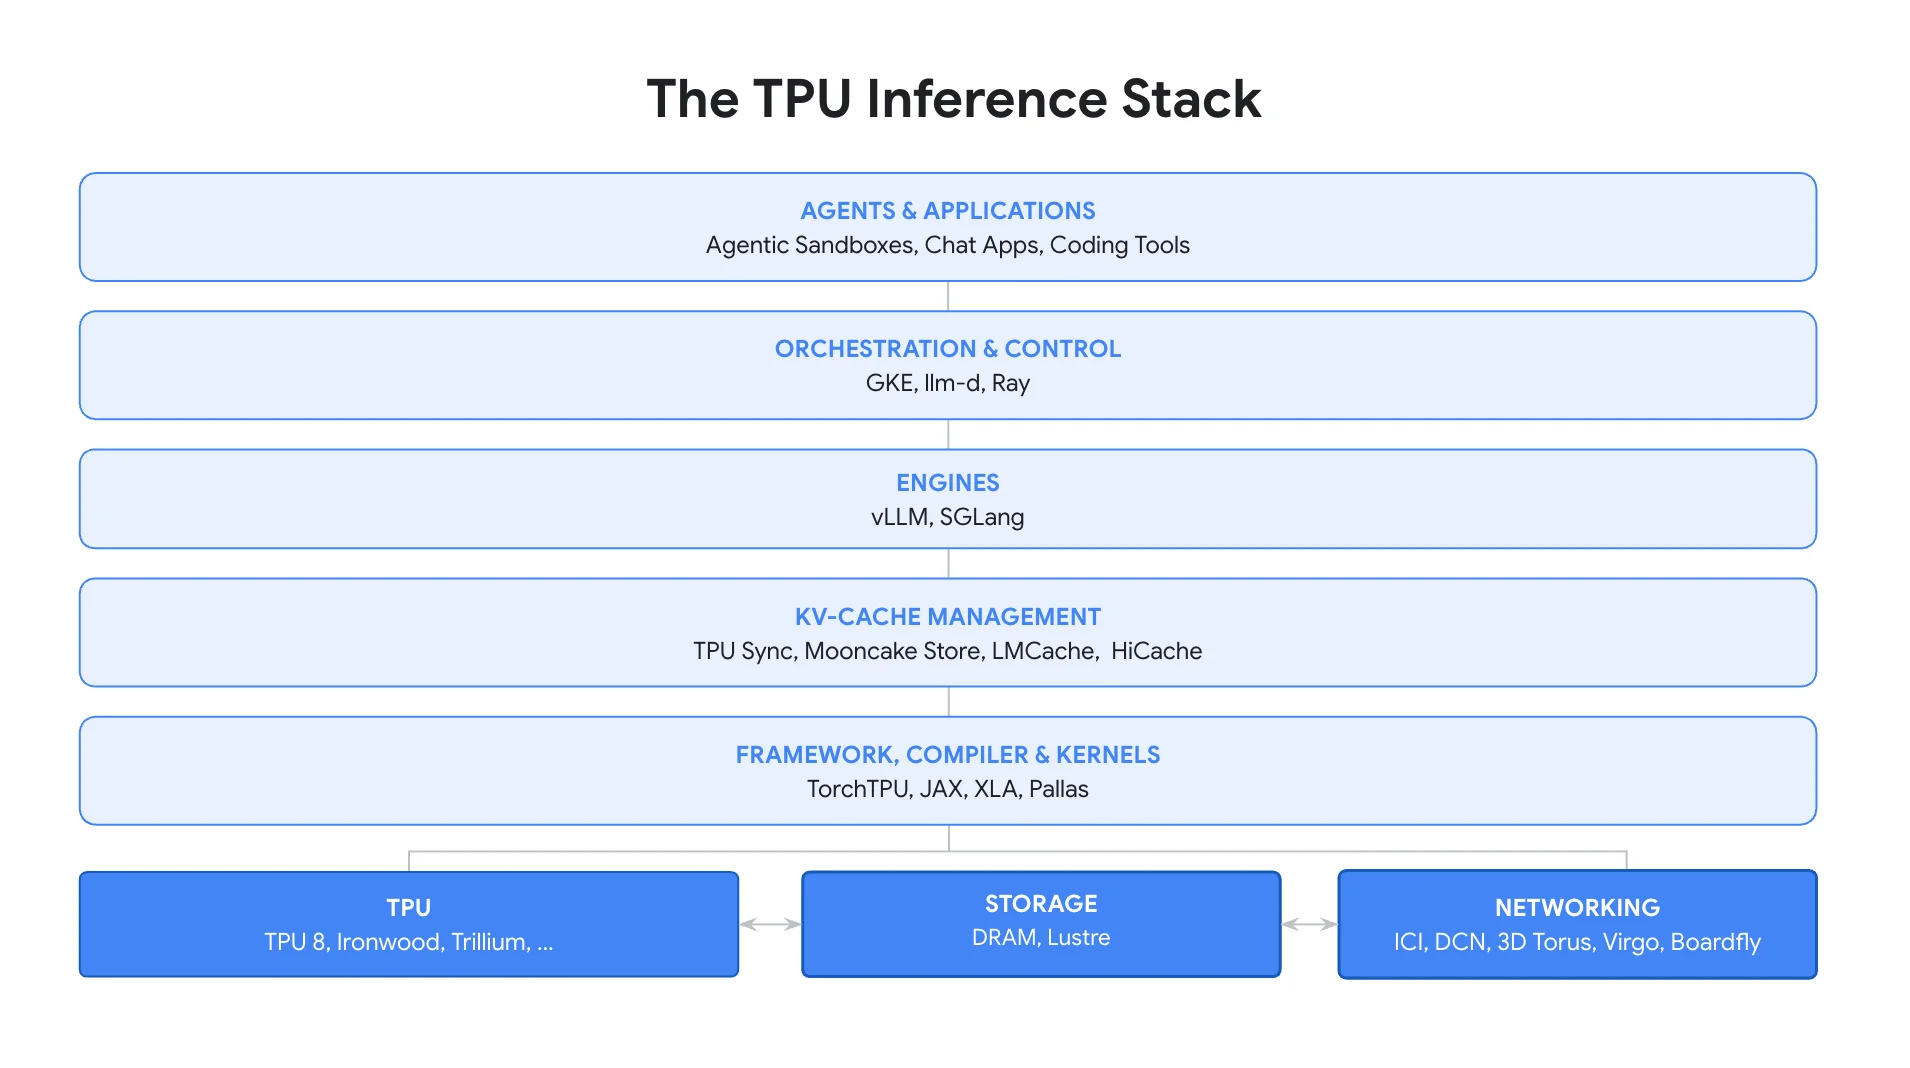
Google’s developers blog announced native PyTorch backends for vLLM, with Inferact, and for SGLang, with RadixArk. Both keep the upstream scheduler and API server and add TPU kernels underneath. TPU Sync moves the KV cache, the memory of an ongoing conversation, between chips without an extra copy on the host.
Zongwei Zhou, PyTorch-TPU lead at Meta, says SGLang-TorchTPU is running in production at Meta. In Hugging Face Transformers v5, Google says a model is sent to a TPU with device_map set to tpu.
The Cloud blog says TorchTitan training runs were validated on up to 8000 Ironwood TPUs and, later in the same post, on up to 8,192. The developers blog cites a public InferenceX benchmark for the speed and cost claims, rather than printing that chart.
Key numbers
- 2.01 cents per million tokens for Qwen 3.5 on Ironwood, in Google’s InferenceX result
- 52% Model Flops Utilization on Qwen 3 8B in the TorchTitan test
- More than 700 tokens per second for one user on the Kimi K3 decode kernel
The SGLang-TorchTPU plugin is Apache 2.0. Google has not stated a licence for every other repository.
Sources
- PrimaryTorchTPU is now open sourcecloud.google.com · Cloud blog, 20 October 2026
- OfficialNew vLLM and SGLang inference engines on TPUdevelopers.googleblog.com · Native PyTorch backends, the Meta production quote and the stack diagram
- OfficialSGLang-TorchTPU repositorygithub.com/sgl-project · Apache 2.0 plugin, a joint effort of Google, Meta and RadixArk
- On X@PyTorch on X: TorchTPUx.com · PyTorch’s post on the launch, 20 October 2026
The rest of the day
Read the whole day
01Open sourceDeepSeek
DeepSeek open-sources DeepInfer, the stack behind V4.1-Flash
DeepInfer is the inference framework behind DeepSeek’s production service, released under Apache 2.0, with a separate library for turning API requests into tokens.
02ModelMistral AI
Mistral AI’s Voxtral 3 runs listening, tools and speech as one pipeline
Voxtral 3 is a family of speech-to-text and text-to-speech models plus a voice agent SDK, on Mistral’s API or arranged for a company’s own machines.
03ModelElevenLabs
ElevenLabs adds Eleven Realtime v1 Mini and Max for voice agents
Mini is the default speech-to-speech model and Max handles harder instructions.
04ProductPerplexity
Perplexity Computer can now run fully local on Apple silicon Macs
The model, the harness and the task can all run on the Mac.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X