

ResearchAnthropicConfirmed
Story 8 of 12 in the Tuesday 3 November editionAnthropic open-sources FlashProve for cryptographic proofs of LLM inference
Published on 2 November 2026 under the Apache 2.0 licence, the zkSNARK prototype proves 400B-parameter Llama 4 Maverick outputs at 110 tokens per second on one H100 GPU.

 Edited by Ashutosh Shrivastava
4 Nov 2026, 09:30 IST · 2 min read
Anthropic and academic collaborators from EPFL, MIT, StarkWare and Succinct published FlashProve on 2 November 2026 (shared on X late on 3 November UTC), releasing an Apache 2.0 software prototype for provable LLM inference alongside a technical report and machine-checked Lean security theorems. Without trusted hardware enclaves, FlashProve uses zero-knowledge succinct arguments (zkSNARKs) built from interactive oracle proofs, code proximity tests and lookup arguments so a provider can prove a response came from specific committed weights without revealing those weights or which experts fired.
FlashProve splits verification into two stages and scales prover compute only with active mixture-of-experts parameters rather than total model size, streaming layer segments from ~290 GB of host RAM onto a single 80 GB H100 GPU. In a one-time 39-minute offline phase, the server publishes a ~6.5 MB cryptographic commitment valid across roughly 16 million requests. In the post-hoc online phase on 4-bit Llama 4 Maverick (400B total parameters, 17B active per token), one H100 GPU plus 24 CPU cores proves batches of 24 requests (1,024-token windows) in 223 seconds, or 110 tokens per second.
Each proof measures 18.78 MB and verifies on a client CPU with no GPU in 17 seconds across 24 threads (21 s single-threaded) using the C++ verifier, alongside a formally verified Lean verifier. Per GPU, proving still takes roughly 72 to 94 times longer than unverified FP8 vLLM inference, making FlashProve suited to statistical auditing, safety evaluations and tamper detection rather than inline real-time serving.
Sources
- PrimaryProgress on provable inference for large language modelsanthropic.com
- Officialanthropics/FlashProve repository on GitHubgithub.com/anthropics
- On XAnthropic FlashProve research announcement on Xx.com
The rest of the day
Read the whole day
01ProductOpenAI
OpenAI details physical hardware engineering with GPT-6 Astra and BenchCAD 2.0
Two OpenAI engineers designed a working handheld Codex voice prototype with GPT-6 Astra in under a week, while an internal model reached 0.875 on BenchCAD 2.0.
02ProductGoogle
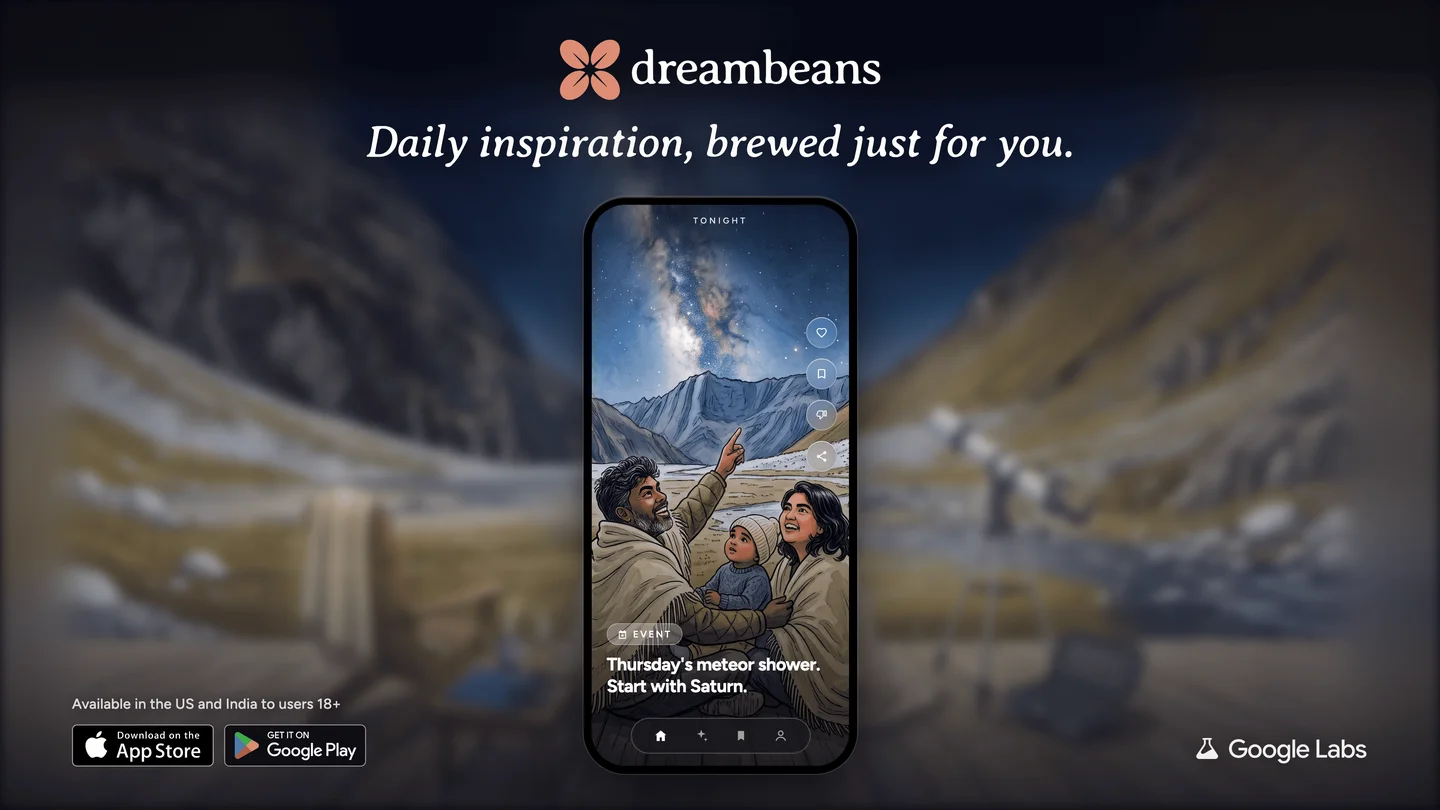
Google Labs expands its Dreambeans personalised storytelling app to India
Adults aged 18 and over in India can generate daily visual story cards on Android, iOS and the web across 14 languages using selected Google app context.
03Open sourceSarvam AI
Sarvam AI open-sources Sarvam Prism for 44 ms single-pass enterprise decisions
Built on Sarvam 105B under the Apache 2.0 licence, the calibrated decision model scores candidate options in one forward pass on a single NVIDIA B200 GPU.
04ModelOpenRouter
OpenRouter launches free 1M-context multimodal stealth model Crouton Alpha
Released on 3 November 2026 under stealth/crouton-alpha, the undisclosed provider’s reasoning model accepts text, image, audio, video and file inputs with zero prompt logging.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X