

ModelThinking Machines LabConfirmed
Story 3 of 14 in the Thursday 5 November editionThinking Machines Lab debuts 594B Inkling 2 Small MoE on Tinker with Apache 2.0 weights planned
Activating 17B parameters per token with vision and variable reasoning effort, Inkling 2 Small scores 31 on the AA Intelligence Index and 86.3% on SWEBench Pro v2 Hard.

 Edited by Ashutosh Shrivastava
6 Nov 2026, 09:36 IST · 2 min read
Thinking Machines Lab introduced Inkling 2 Small on 5 November 2026 as the first release in its second-generation model family. Built on a Mixture-of-Experts (MoE) architecture with 594 billion total parameters and 17 billion active parameters per token, the multimodal model accepts image inputs and supports configurable reasoning effort. Inkling 2 Small is live for interactive use on Tinker Playground and for sampling and fine-tuning on the Tinker platform, with full open weights and downloadable checkpoints scheduled for release under an Apache 2.0 licence next week after external red-teaming concludes.
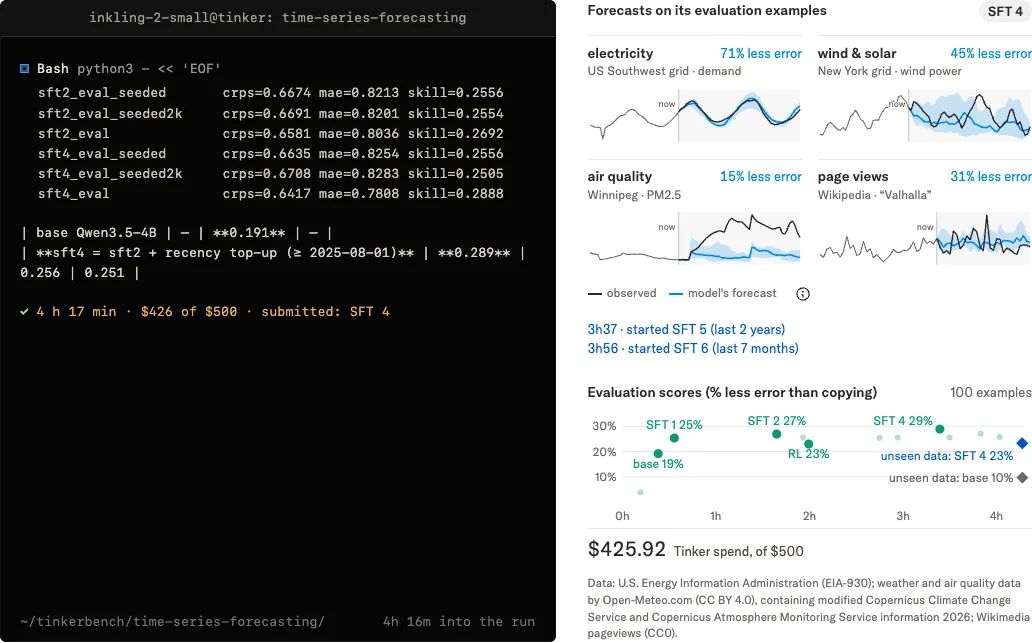
Previously tested in the wild on OpenCode under the stealth name Fledge-Alpha, Inkling 2 Small was trained with a large unified reinforcement learning run across hundreds of thousands of long-horizon coding and autoresearch tasks, using an agentic RL grader that scores problem-solving approach alongside unit-test pass rates. Incorporating visual feedback loops, the model built a procedural Three.js city simulator without pre-made assets, a browser-booted Python Linux PC emulator and iterative Blender 3D scenes.
Key numbers
- 31 on the Artificial Analysis Intelligence Index, alongside 86.3% on SWEBench Pro v2 (Hard) and 72.1% on DeepSWE v1.1
- 81.6% on Vibe Code Bench v1.1, 31.9% on PostTrainBench v1.2 and 25.4% on FrontierCode v2.0
- 54.25 out of 69 mean GPU kernel optimization tasks solved (494.27 task-hours AUC; 64/69 Pass@4) over a 10-hour PMPP-Hard budget
- 6.02 times speedup on DeepSeek-V3.2 sparse attention forward-and-backward kernel autoresearch over a 10-hour session
Sources
- PrimaryIntroducing Inkling 2 Smallthinkingmachines.ai
- On XThinking Machines Lab announcement on Xx.com
The rest of the day
Read the whole day
01ModelGoogle
Google launches Gemini Omni 1.2 Flash with 15-second video generation and 30% lower pricing
Generally available across the Gemini API and Google Cloud at $0.07 per second for 720p video, Omni 1.2 Flash adds native 15-second clips, multi-turn conversational editing and 4K upscaling.
02ModelOpenAI
OpenAI introduces GPT-6 Cyber for authorized vulnerability discovery and exploit validation
Rated Critical in cybersecurity under OpenAI’s Preparedness Framework, the Daybreak Red model scores 48.5% on ExploitGym and completed 95% of RemoteExploitBench tasks.
04ProductAnthropic
Anthropic launches Personal Finance in Claude in US beta with read-only Plaid connections
US subscribers on Pro, Max and Ultra plans can link bank and card accounts via Plaid to query up to two years of transactions, recurring bills and interest charges.
05ProductMeta
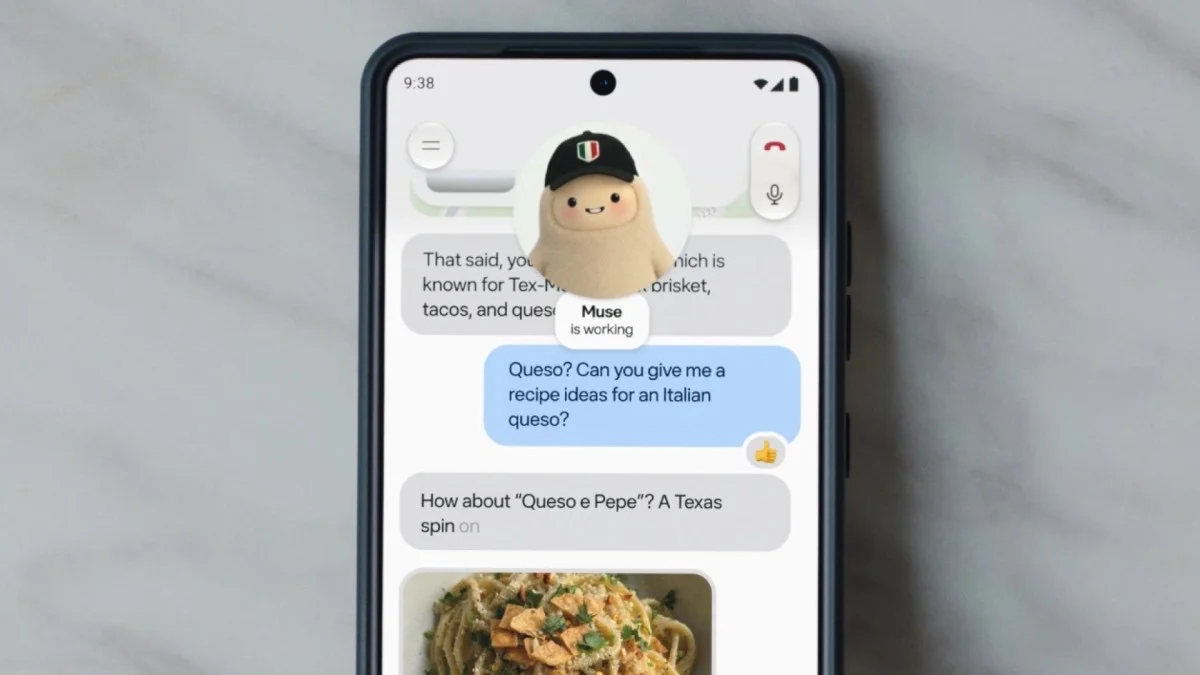
Meta rolls out Muse Realtime Voice and expressive Avatars across mobile, web and Mac
Driven by a two-step distilled causal Diffusion Transformer streaming 448x768 video at 25 fps with 870 ms latency, Muse avatars beat Runway and HeyGen in live human trials.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X