

Open sourceTencentConfirmed
Story 7 of 18 in the Wednesday 18 November editionTencent releases open-weight 220B Hy4-flash models with 1M context
Instruct, FP8 and pretrained base checkpoints with DFly2 speculative decoding weights under the Tencent Hy License across Hugging Face, ModelScope and GitCode on 18 November 2026.

 Edited by Ashutosh Shrivastava
19 Nov 2026, 09:05 IST · 2 min read
Two days after launching its hosted Hy4 flash API, Tencent Hunyuan released open weights on 18 November 2026 for tencent/Hy4-flash, tencent/Hy4-flash-FP8 and the pretrained tencent/Hy4-flash-base checkpoint across Hugging Face, ModelScope and GitCode under the Tencent Hy License. Listed on the Hugging Face Hub at 220 billion total parameters including 64 billion Engram lookup parameters (224 billion in Tencent’s earlier research note) with 12 billion active parameters per token, the natively multimodal Mixture-of-Experts model accepts text and image inputs across a 1-million-token context window.
LatentMoE KV-cache compression, vLLM and SGLang serving, and DFly2 decoding
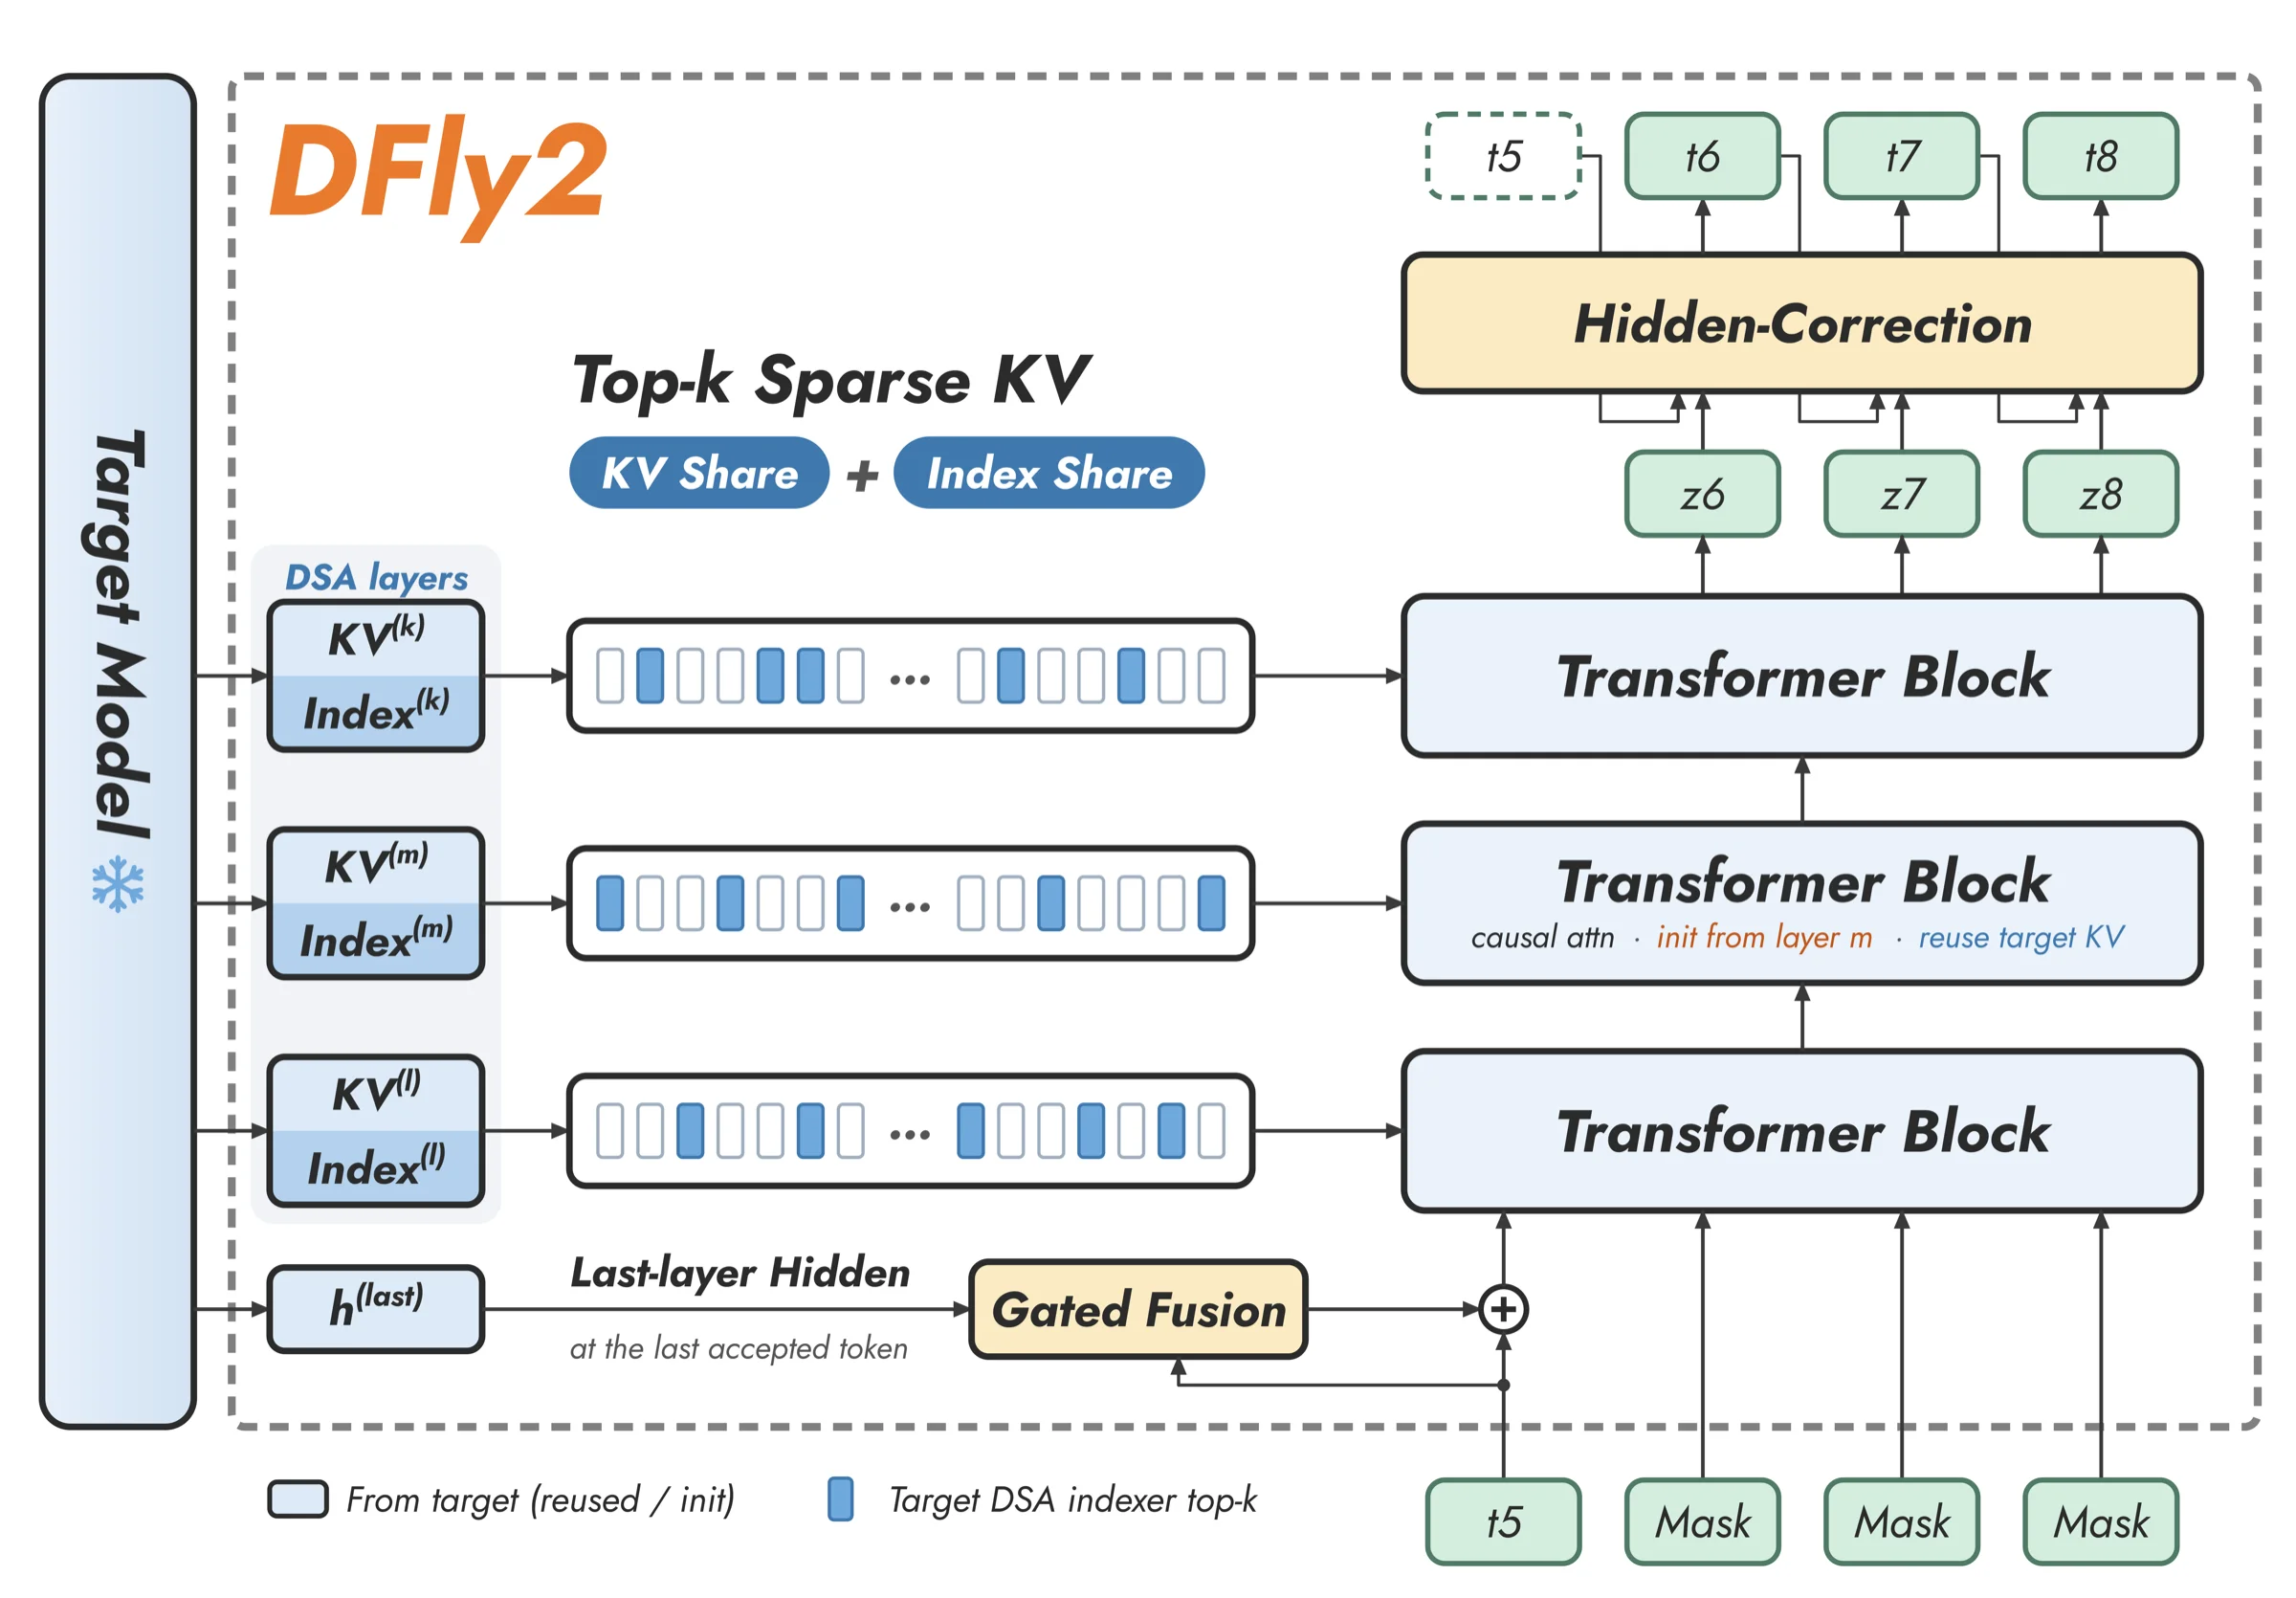
Hy4-flash pairs hybrid attention, LatentMoE and Engram tables to compress KV-cache memory to one-sixth of flagship Hy4 while halving average output token length through self-distillation and reinforcement learning. Alongside the full-precision and FP8 checkpoints, Tencent released DFly2 speculative decoding weights that reuse target top-k sparse KV states and hidden-layer corrections across draft blocks.
Developers can run the weights locally or on private clusters through Hugging Face Transformers (image-text-to-text), vLLM, SGLang, Docker Model Runner (hf.co/tencent/Hy4-flash) and community GGUF quantisations for llama.cpp, Ollama and LM Studio.
Technical details
- Released Hugging Face repos
- tencent/Hy4-flash, tencent/Hy4-flash-FP8 and tencent/Hy4-flash-base (plus DFly2 speculative decoding)
- Parameters and context
- 220B listed on Hub (including 64B Engram), 12B active per token, 1M text-and-image context window
- Licence and distribution
- Tencent Hy License across Hugging Face, ModelScope and GitCode
- Supported serving engines
- Transformers, vLLM, SGLang, Docker Model Runner and GGUF (llama.cpp, Ollama and LM Studio)
Release details & context
Seven-benchmark public evaluation suite and DFly2 sparse KV reuse
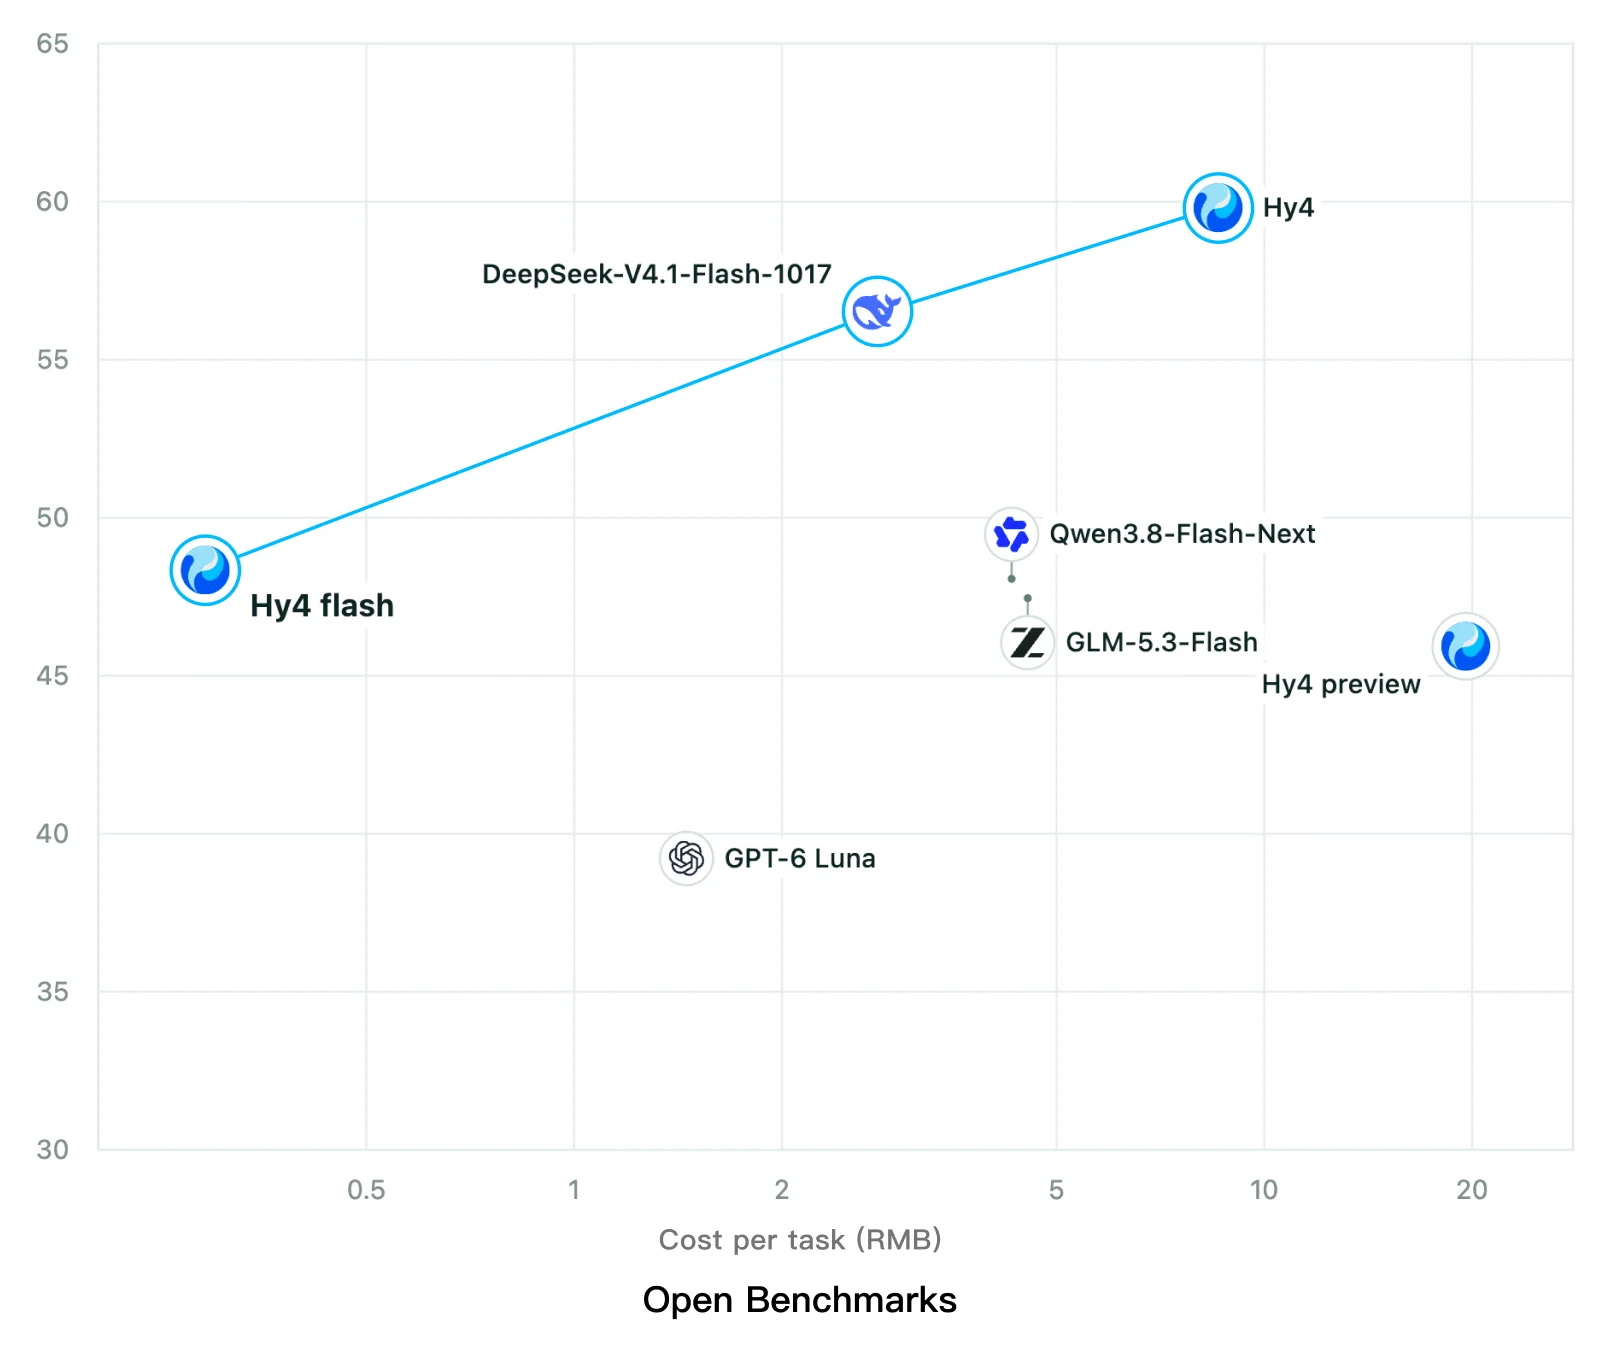
On the Hugging Face model card, Tencent’s Open Benchmarks frontier aggregates seven external agentic and reasoning evaluations: DeepSWE, ProgramBench, Terminal-Bench 4.0, APEX-Agents, AutomationBench, Humanity’s Last Exam (HLE) and OSWorld 2.1, plotted alongside internal eight-track WorkIndex and 259-task blind WorkBuddy evaluations.
To sustain high single-stream decoding throughput on self-hosted clusters, the DFly2 architecture shares top-k sparse KV tensors and DSA indexer states directly from frozen target layers into three lightweight draft Transformer blocks, applying gated fusion with the last accepted hidden state and a top Hidden-Correction layer.
Common questions
Which checkpoints are included in Tencent’s Hy4-flash open-weight release?
Tencent published the post-trained tencent/Hy4-flash instruct model, the quantised tencent/Hy4-flash-FP8 checkpoint and the pretrained tencent/Hy4-flash-base model alongside DFly2 speculative decoding support.
Sources
- Primarytencent/Hy4-flash on Hugging Facehuggingface.co/tencent
- Officialtencent/Hy4-flash-FP8 on Hugging Facehuggingface.co/tencent
- Officialtencent/Hy4-flash-base on Hugging Facehuggingface.co/tencent
Tencent release timeline (3 launches tracked)
- Tencent launches multimodal Hy4 model with native computer use and 3D engine training
Tencent released Hy4 on Tencent Cloud TokenHub at roughly $0.90 per 1M input tokens, adding multimodal perception, computer use and 3D engine workflows.
- Tencent launches 224B Hy4 flash multimodal MoE at $0.070 input
Tencent launches its 224B-total, 12B-active Hy4 flash multimodal model at $0.070 input and $0.281 output, at one-twentieth of Hy4’s task cost.