

ModelTencentConfirmed
Story 4 of 15 in the Monday 16 November editionTencent launches 224B Hy4 flash multimodal MoE at $0.070 input
Live across Tencent Cloud TokenHub, WorkBuddy, Yuanbao and OpenRouter with a 1M context window, offering 50% promotional API discounts until 30 November 2026.

 Edited by Ashutosh Shrivastava
17 Nov 2026, 09:20 IST · 3 min read
Tencent Hunyuan released Hy4 flash on 16 November 2026 across Tencent Cloud TokenHub, OpenRouter (tencent/hy4-flash), WorkBuddy, Yuanbao, WeCom, QQ, ima and Marvis, following its flagship multimodal Hy4 launch. The natively multimodal Mixture-of-Experts checkpoint pairs 224 billion total parameters (including 64 billion Engram parameters) with 12 billion active parameters per token across a 1-million-token context window.
LatentMoE KV-cache compression, 150 tok/s serving and API pricing
Pre-training combines hybrid attention, LatentMoE and Engram lookups to shrink KV-cache memory to one-sixth of Hy4 and one-twenty-fourth of Hy3, while self-distillation from Hy4 and reinforcement learning trim average end-to-end output tokens by 50%. At inference, megakernels, 4-bit quantisation and DFly push decoding throughput above 150 tokens per second.
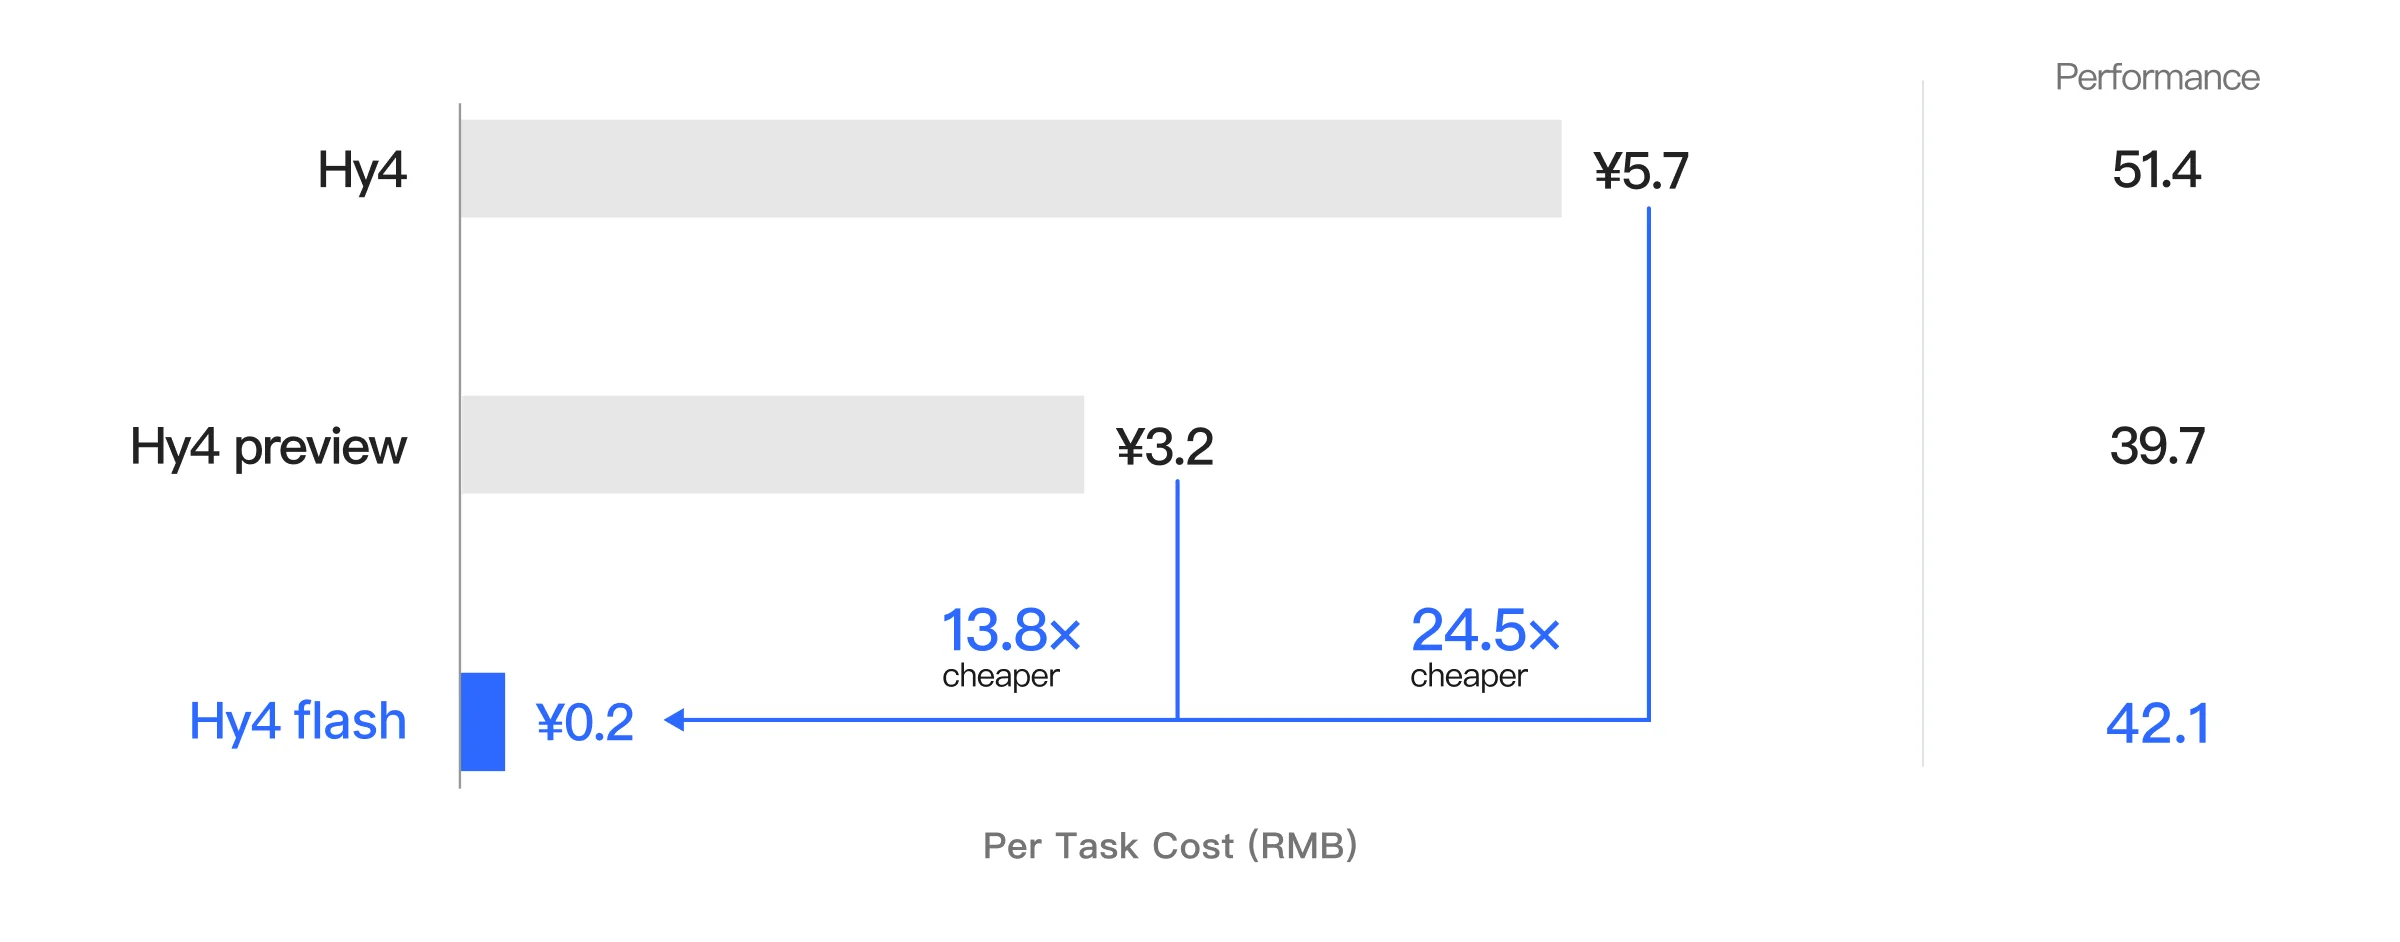
Standard API rates per million tokens are $0.070 uncached input, $0.281 output and $0.003 cached input, down from $0.834 input, $2.501 output and $0.042 cached on Hy4; through 30 November 2026, Tencent Cloud TokenHub and OpenRouter bill 50% off ($0.035 input, $0.1405 output and $0.0015 cache read), and WorkBuddy usage is free. On Tencent’s eight-set WorkIndex benchmark, Hy4 flash edges past Hy4 preview at one-twentieth the per-task cost of Hy4 and one-eighth that of DeepSeek-V4.1-Flash-1017 (Max peak pricing). Tencent stated that it plans to release Hy4 flash as an open-weight model at a later date.
Technical details
- Model parameters and context
- 224B total (including 64B Engram parameters), 12B active per token, 1M multimodal context window
- Standard API pricing (per 1M)
- $0.070 input, $0.281 output and $0.003 cached input (vs $0.834 / $2.501 / $0.042 on Hy4)
- Promo pricing to 30 Nov 2026
- 50% off on TokenHub and OpenRouter ($0.035 in / $0.1405 out / $0.0015 cache); free in WorkBuddy
- Architecture and serving stack
- Hybrid attention + LatentMoE + Engram (1/6 Hy4 KV cache); megakernels + 4-bit quantisation + DFly (>150 tok/s)
Release details & context
WorkBuddy turnaround gains, Yuanbao GSB uplift and public benchmark scope
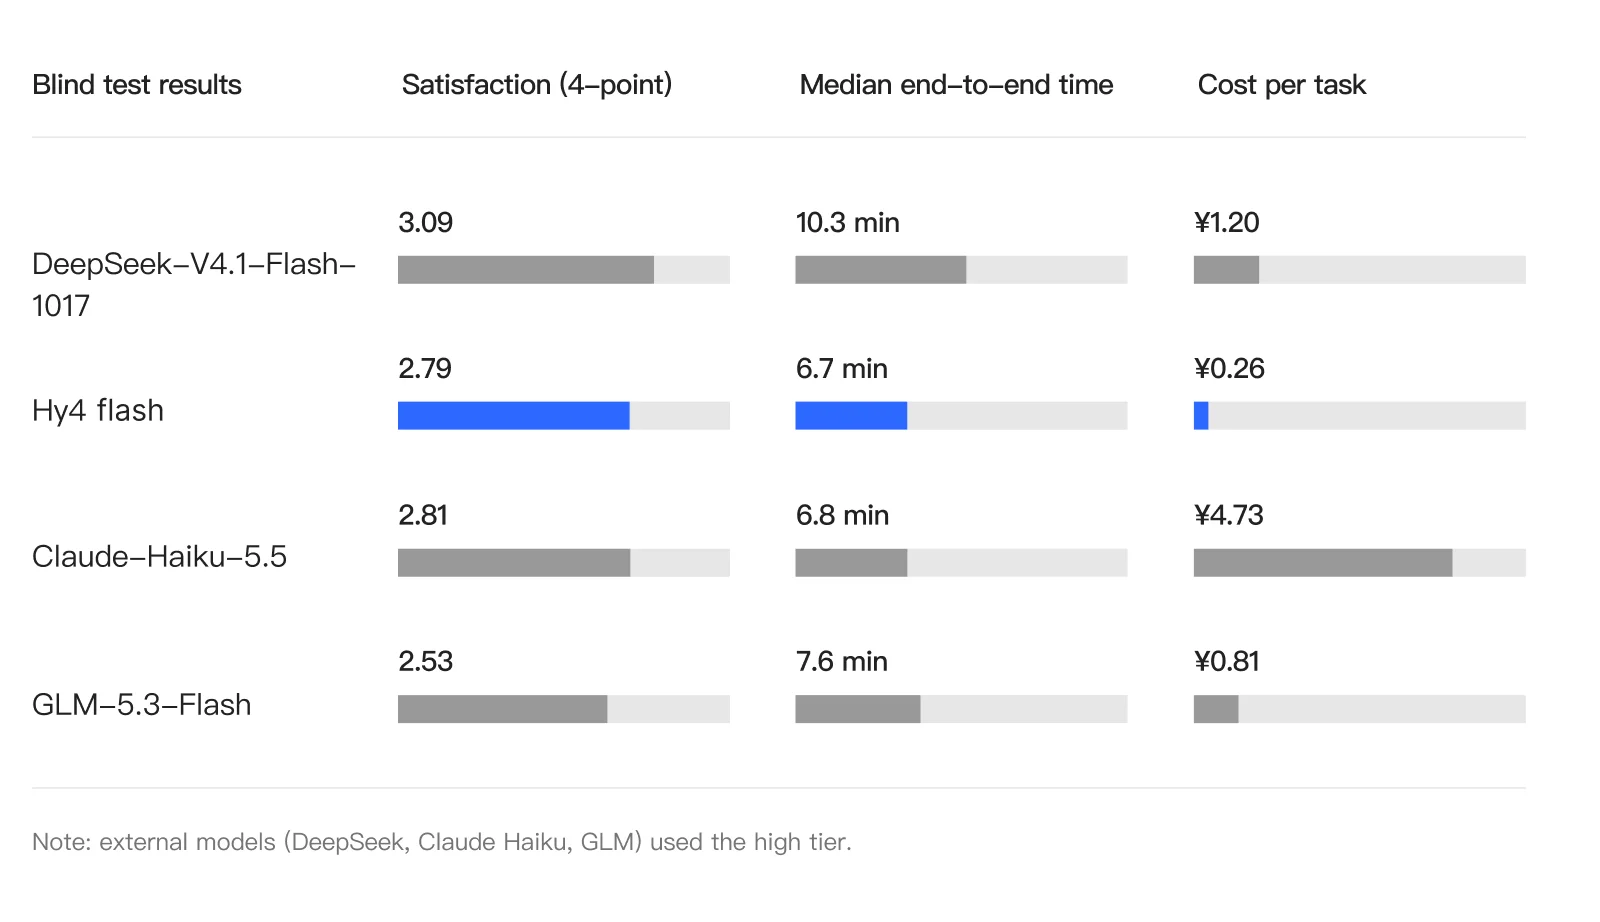
Inside Tencent’s internal deployments, WorkBuddy reported that Hy4 flash shortened average office task completion time by 70% at roughly one-fifteenth the cost of Hy4 while recommending full Hy4 only for complex long-horizon software engineering, and Yuanbao recorded a 13.6% agent score gain over Hy3, a 7.56% human side-by-side (GSB) win-rate lift and a 2.52% general chat lead over GLM-5.3-Flash.
Tencent’s external evaluation suite benchmarked Hy4 flash across seven public agent tests (DeepSWE, ProgramBench, Terminal-Bench 4.0, APEX-Agents, AutomationBench, HLE and OSWorld 2.1) alongside eight internal WorkIndex tracks covering slide creation, Markdown co-writing, spreadsheet repair and video comprehension; on OpenRouter, Tencent Cloud currently serves 100% of tencent/hy4-flash traffic directly without multi-provider splitting.
Common questions
Has Tencent published open weights for Hy4 flash alongside the API launch?
Not yet; Tencent stated in its 16 November 2026 research post that it plans to release open weights for Hy4 flash in a future update.
Which workloads does Tencent still recommend routing to flagship Hy4 instead of Hy4 flash?
Tencent recommends Hy4 flash for everyday search, document, slide, frontend demo and computer-use tasks while reserving full Hy4 for long-horizon software engineering.
Sources
- PrimaryTencent Hunyuan: Introducing Hy4 flash: Ultimate cost-efficiency for everyday productivityhy.tencent.ai
- OfficialTencent Hy4 flash API Pricing & Benchmarks on OpenRouteropenrouter.ai
- On XTencent Hunyuan (@TencentHunyuan) launch post on Xx.com
Tencent release timeline (2 launches tracked)
- Tencent launches multimodal Hy4 model with native computer use and 3D engine training
Tencent released Hy4 on Tencent Cloud TokenHub at roughly $0.90 per 1M input tokens, adding multimodal perception, computer use and 3D engine workflows.