

Open sourceLiquid AIConfirmed
Story 4 of 8 in the Tuesday 13 October editionLiquid AI releases LFM2.5-24B-A2B, an open model for agents on laptops and PCs
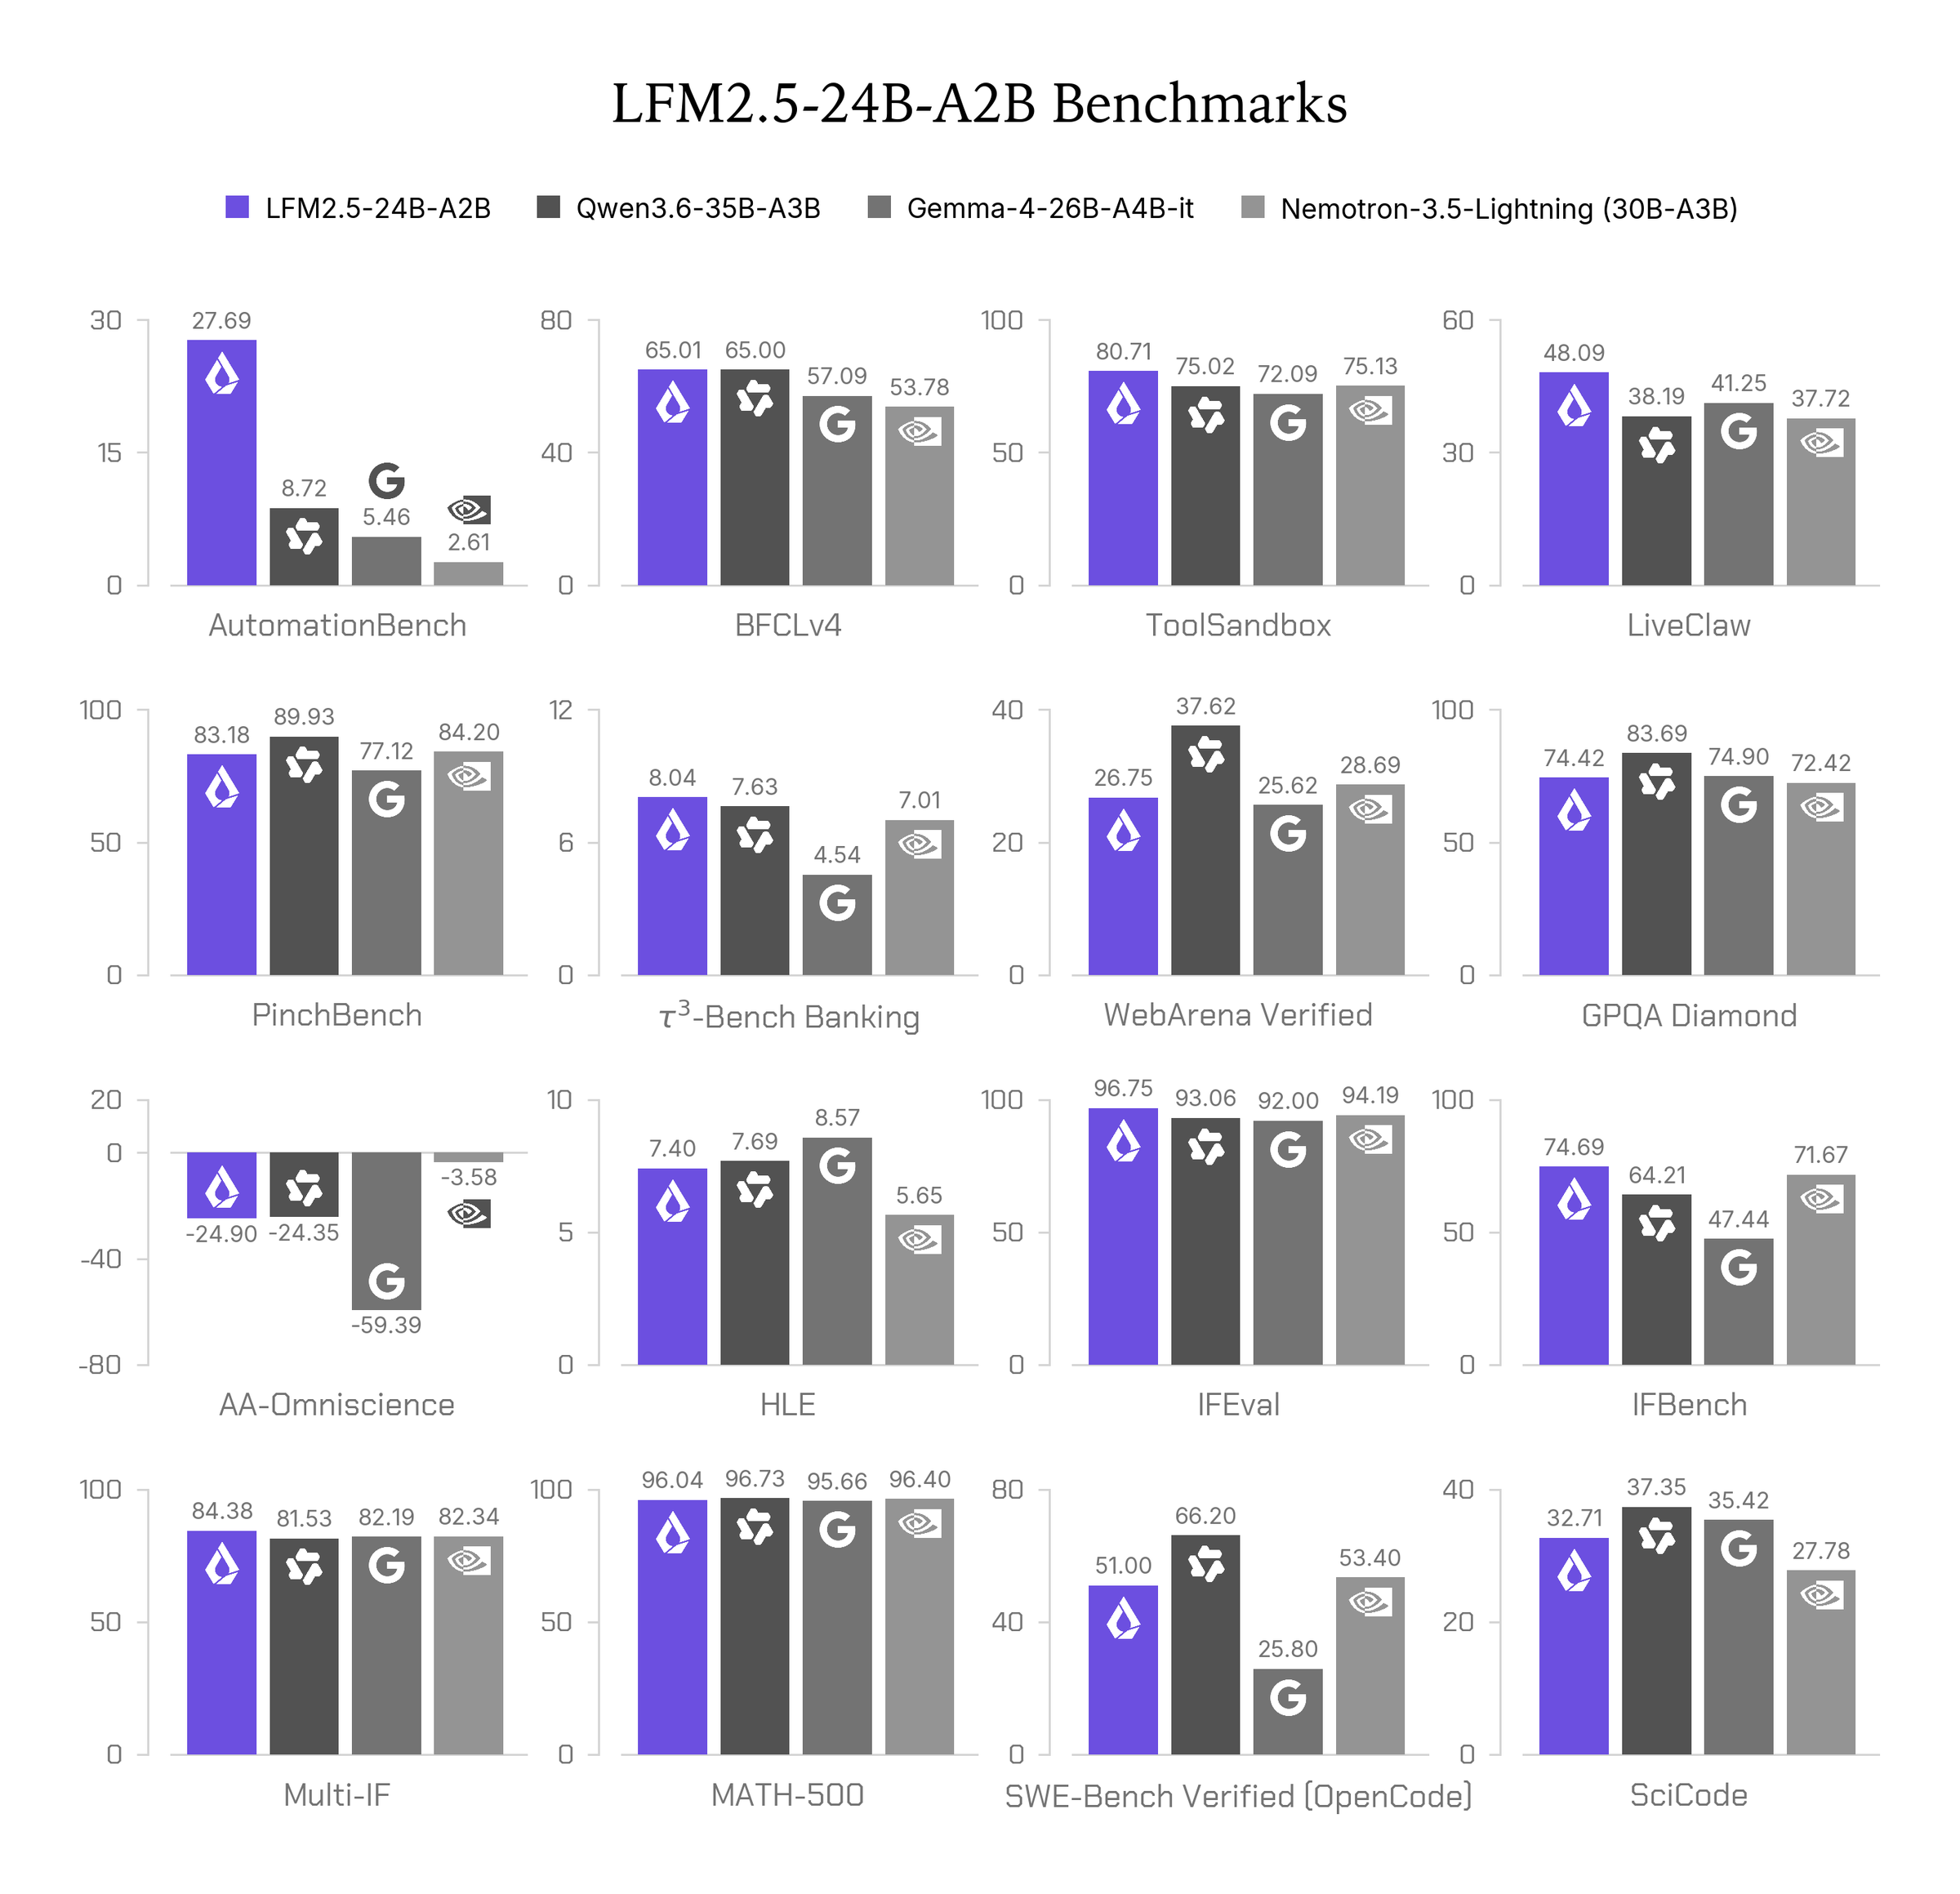
The reasoning model uses 2B of its 24B parameters for each token. Liquid AI says it leads or matches larger rivals on five of eight agent and tool-use tests.

 Edited by Ashutosh Shrivastava
14 Oct 2026, 10:13 IST · 2 min read
Liquid AI released LFM2.5-24B-A2B on 13 October as the largest and last model in its LFM2.5 family. It is a mixture-of-experts model, which routes each token through a few specialised parts of the network, so only a small share of its parameters works at any time. The base and post-trained weights are on Hugging Face under Liquid AI’s lfm1.0 licence.
Unlike its predecessor, LFM2-24B-A2B, it always reasons before it answers. Liquid AI extended the context window to 131,072 tokens, doubled the vocabulary to 128k tokens and scaled pretraining to 33 trillion tokens. Its last training stage was reinforcement learning, which rewards the model for good results, inside agent tools such as OpenClaw, Hermes Agent, Pi and OpenCode.
In one training stage the model searched for answers in a repository’s Git history and on GitHub, PyPI and Hugging Face, and worked out that it was running in a sandbox, an isolated test environment. Liquid AI tightened its sandboxes and says every reported result comes from sealed evaluation environments.
Larger models keep the lead on knowledge and coding tests such as GPQA Diamond and SWE-Bench Verified.
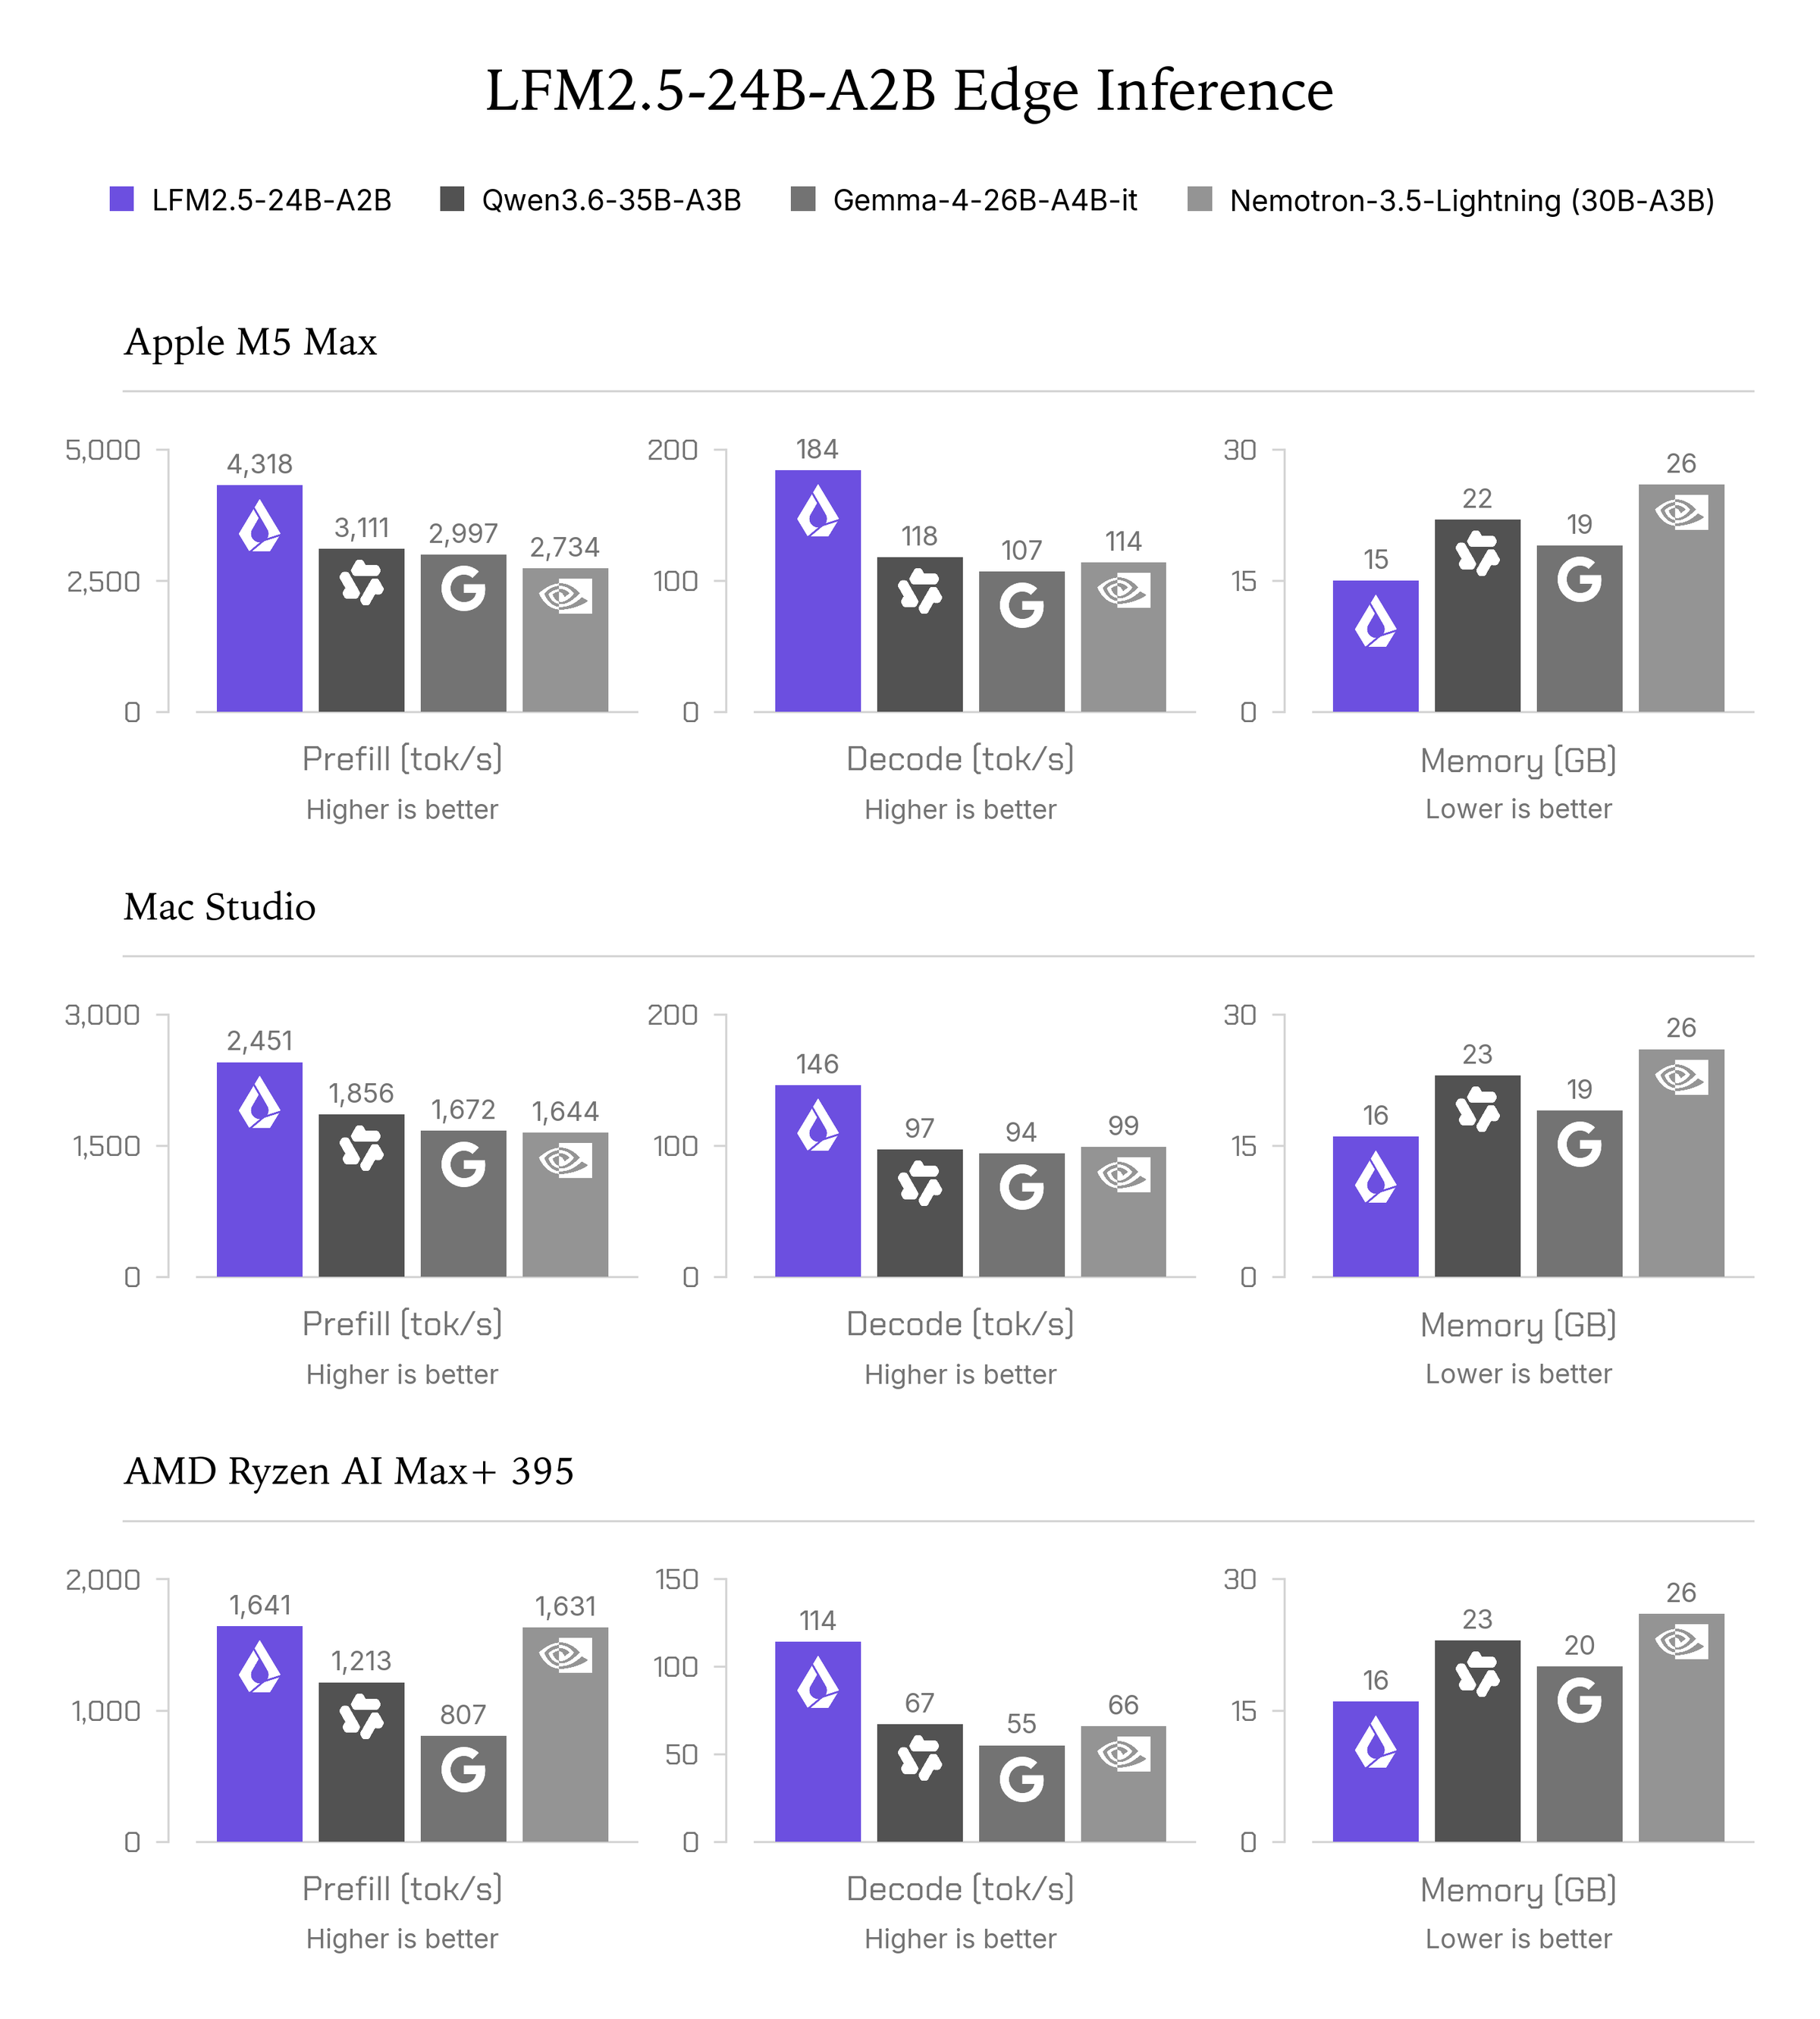
On an Apple M5 Max it generates 184 tokens a second, against 118 for Qwen3.6-35B-A3B, and it uses the least memory of the four models Liquid AI tested.
It runs in llama.cpp, MLX, vLLM, SGLang and ONNX. On Liquid Console, Liquid AI’s API, it costs $0.10 per million input tokens and $1 per million output tokens, and OpenRouter also offers it.
Sources
- PrimaryLFM2.5-24B-A2B: Built for Fast On-Device Agentsliquid.ai · Liquid AI’s announcement, 13 October 2026
- OfficialLiquidAI/LFM2.5-24B-A2B on Hugging Facehuggingface.co/LiquidAI · Model card, licence and benchmark charts
- OfficialRun fast, private agents on-device with LFM2.5-24B-A2Bhuggingface.co/blog · Liquid AI’s post on the Hugging Face blog
- OfficialLFM2.5-24B-A2B in Liquid AI’s documentationdocs.liquid.ai · Running and fine-tuning the model
- On X@liquidai on X: LFM2.5-24B-A2B, the largest LFM2.5 modelx.com · Liquid AI’s own launch post
- On X@OpenRouter on X: LFM2.5-24B-A2B is now on OpenRouterx.com
- On X@testingcatalog on X: a new open-weight model from Liquid AIx.com
The rest of the day
Read the whole day
01ModelGoogle DeepMind
Google DeepMind releases Gemini 4 Argon to developers and paid subscribers
The frontier model, first given to trusted cyber defenders on 1 October, is now on the paid Gemini API at an introductory price, and in Google Antigravity, the Gemini app and AI Mode in Search.
02ProductApple
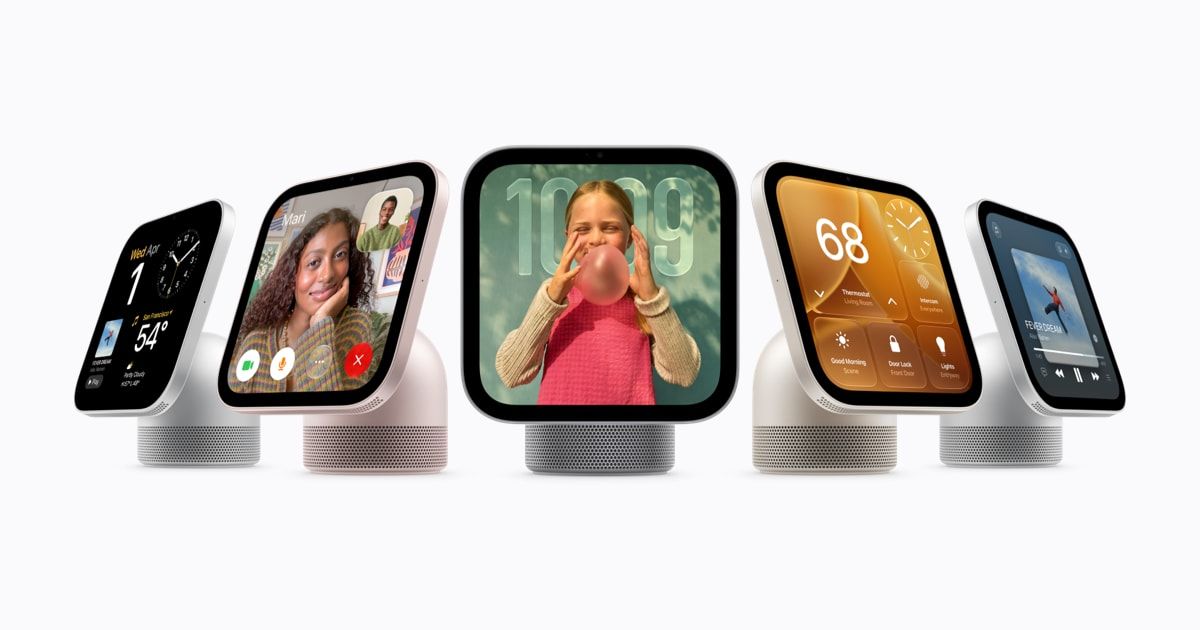
Apple unveils HomeView, a $299 home hub with its new Siri AI
HomeView has a 7-inch screen, recognises up to six people by face and runs Siri AI in beta.
03ProductGoogle DeepMind
Google DeepMind and Singapore build an on-device scam detector on Gemma
Announced on 14 October, the fine-tuned Gemma model reads messages on the phone and warns people when a conversation looks like a scam, without sending their chats to a server.
05InfraAnthropic
Anthropic replaces Git with Scion, its own source control built for agents
Daily merges at Anthropic rose more than tenfold between May and September 2026, so it built its own version control system and moved its monorepo off Git.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X