

ModelLiquid AIConfirmed
Story 6 of 15 in the Monday 16 November editionLiquid AI releases d1.2 and d1.2-ultra omnimodal decision models
Live on the 64k-context Liquid API at $0.02 and $0.042 per million input tokens with zero output fee, adding audio input and five structured extraction tasks.

 Edited by Ashutosh Shrivastava
17 Nov 2026, 09:20 IST · 3 min read
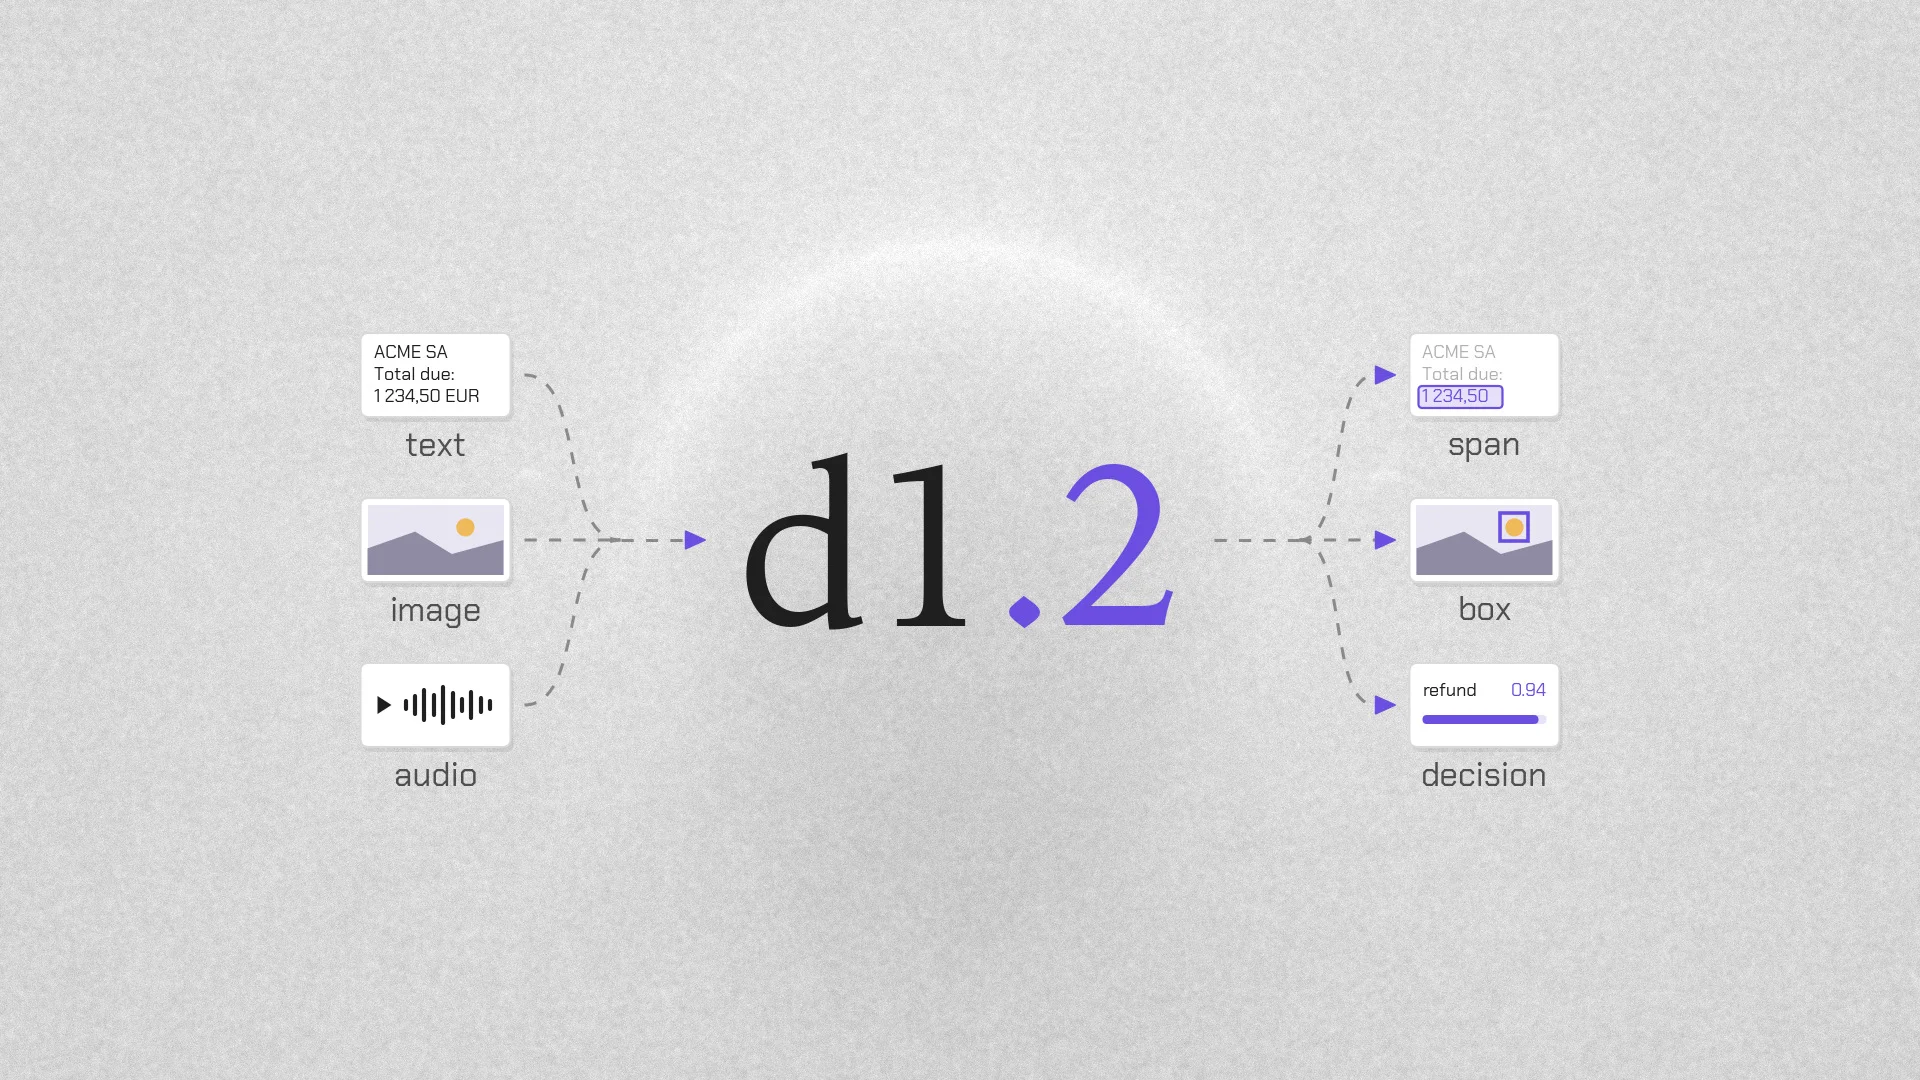
Liquid AI launched d1.2 and d1.2-ultra on 16 November 2026 on the Liquid API (console.liquid.ai), upgrading its 64k-context decision models beyond text and images to accept spoken or ambient audio while adding five structured extraction and spatial grounding task types. Following Liquid AI’s LFM3 model family, both checkpoints bill strictly for input tokens with zero output-token charge: $0.02 per million input tokens for d1.2 and $0.042 per million input tokens for d1.2-ultra, with OpenRouter and Vercel availability planned.
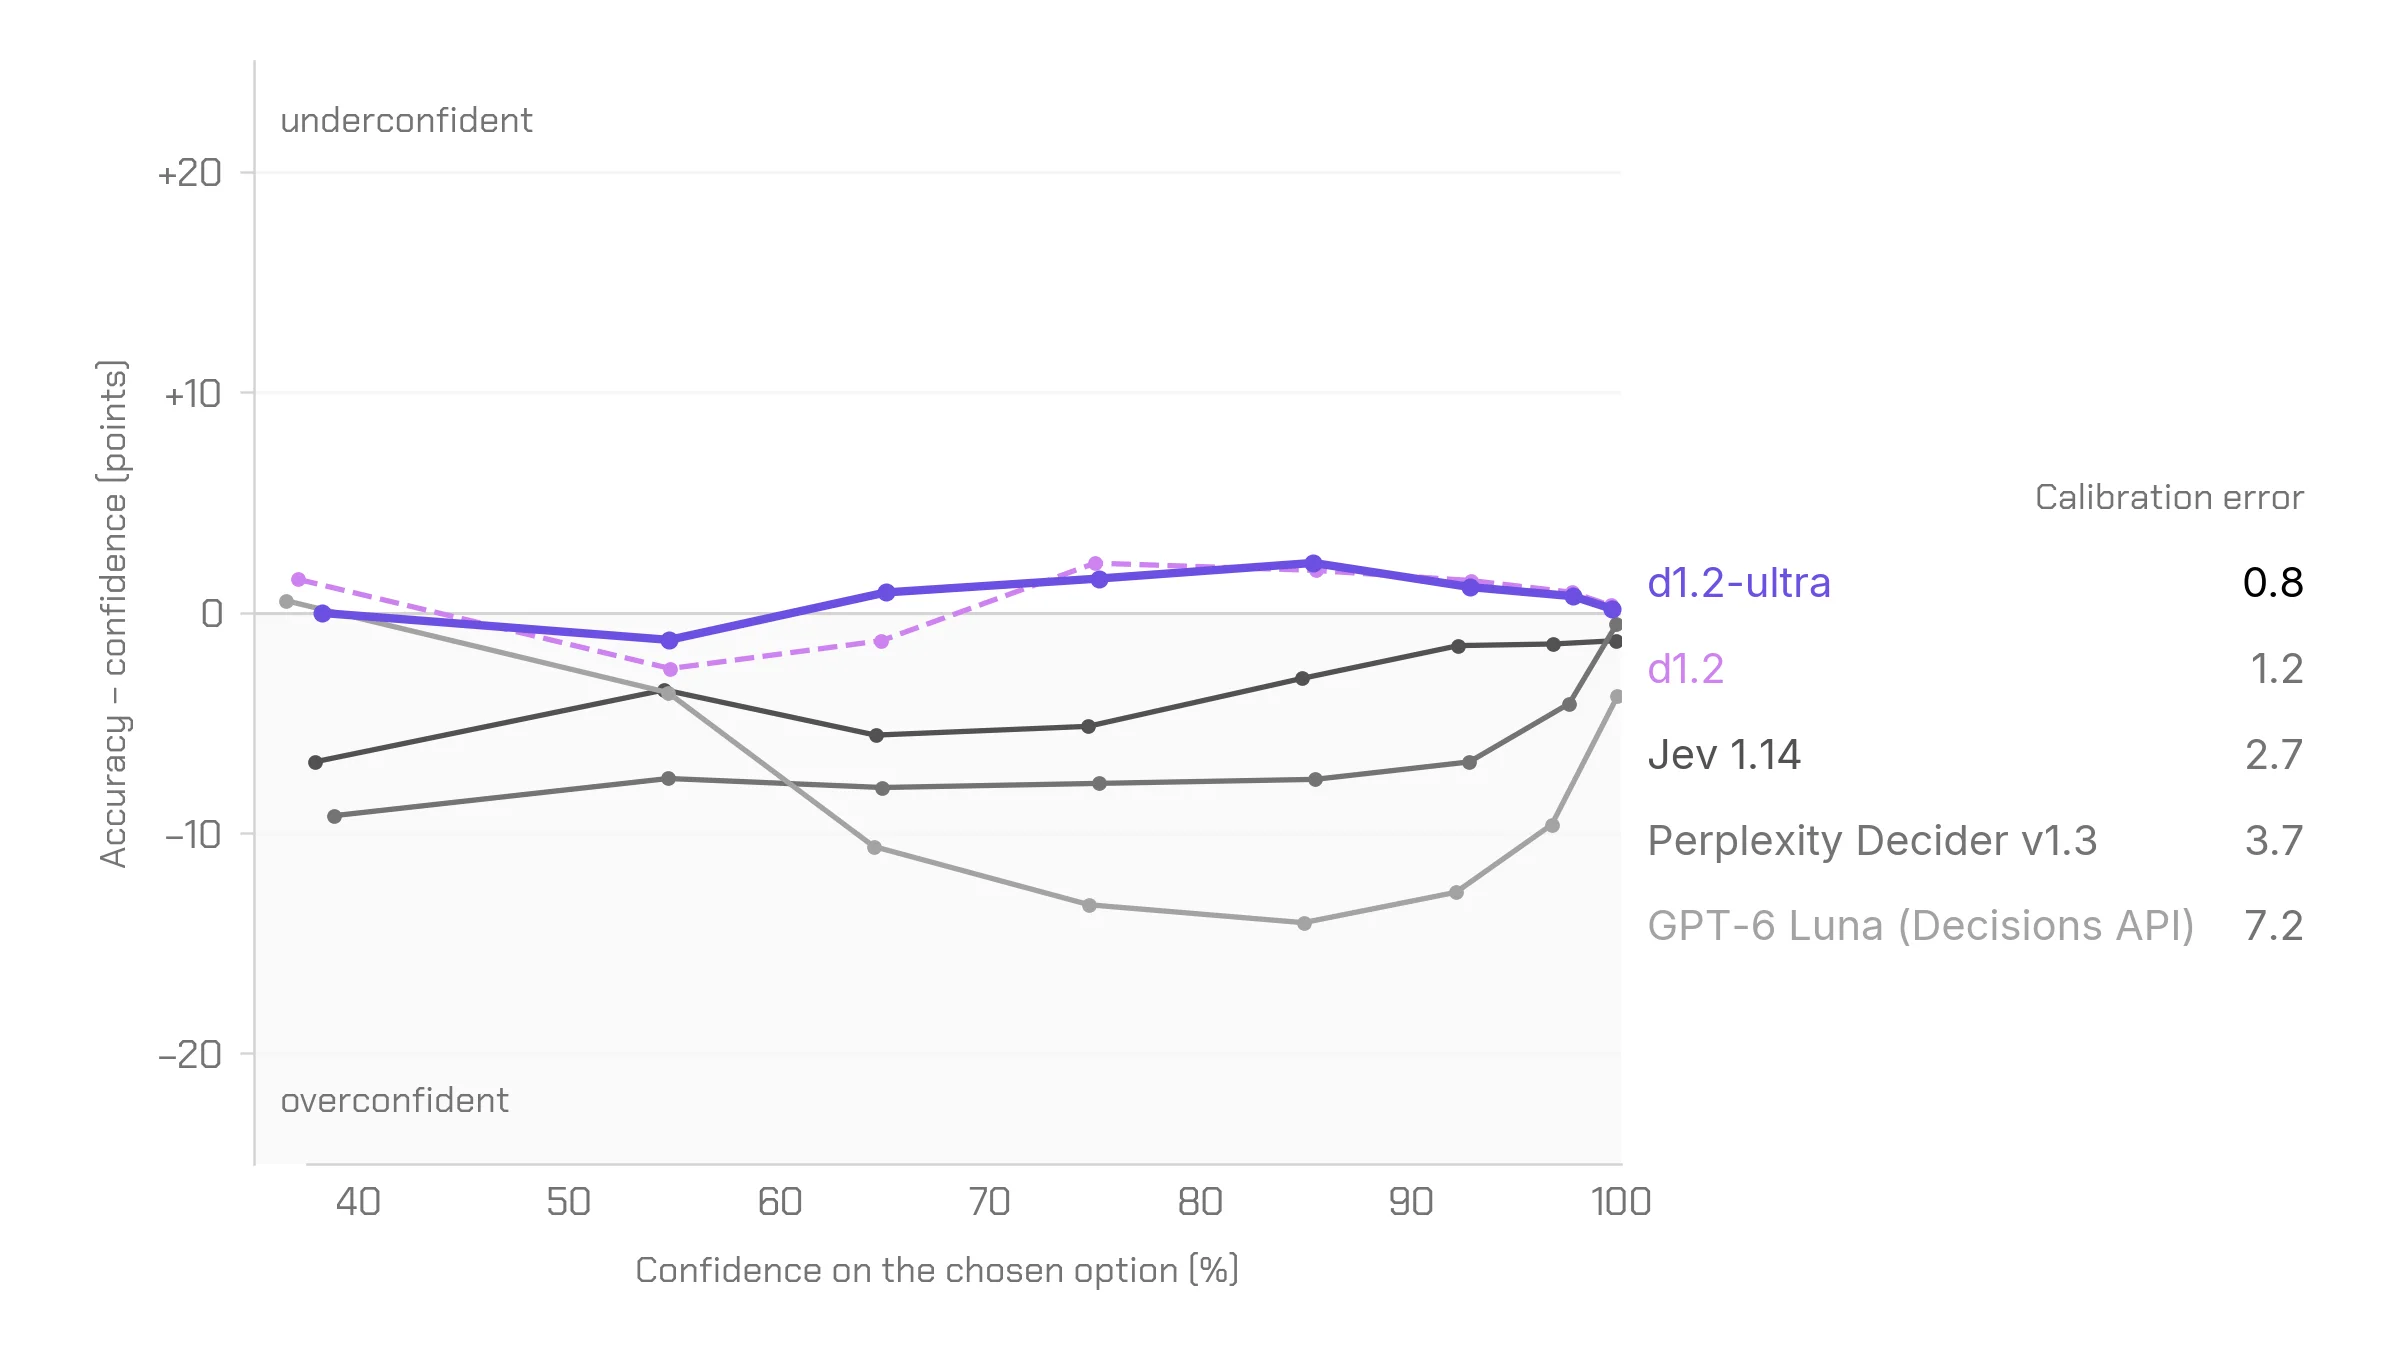
Five extraction primitives, patch token metering and 0.8-point calibration
Using the existing Decisions endpoint, developers can invoke five new output types: reading exact text, number or date values with character spans (returning not found instead of guessing when absent), extracting all matching text spans such as PII, returning single or multi-instance image bounding boxes with counts, estimating quantities with numeric ranges, and multi-label option selection with per-choice probabilities. Images bill 1.5 tokens per 32x32-pixel patch (1,536 tokens for a 1024x1024 image), and multi-question requests pay for shared text and image context once.
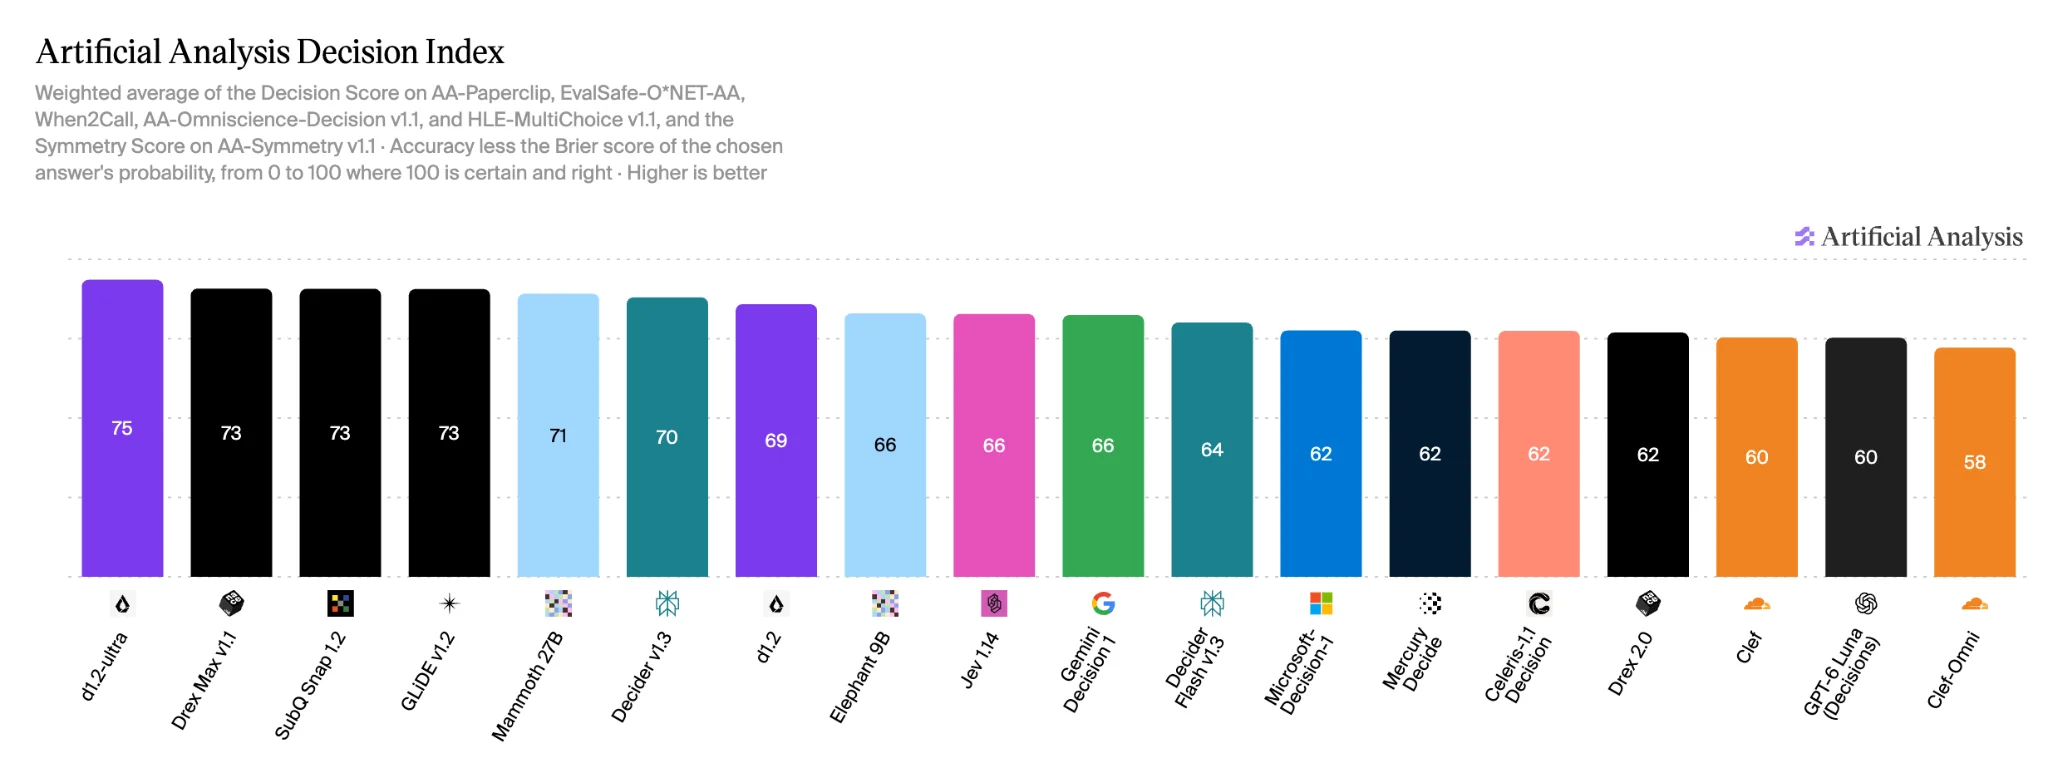
On the Artificial Analysis Decision Index v2.1, d1.2-ultra placed first overall at 75 (and first on private AA-Paperclip at 76, three points clear of Drex Max v1.1), while d1.2 ranked sixth at 69, pricing 1 million Decision Index tasks at $133 and $63 respectively.
Technical details
- Model IDs and context
- d1.2 and d1.2-ultra on console.liquid.ai; 64k-token context window across text, image and audio
- Input-only API pricing
- $0.02/1M input tokens (d1.2) and $0.042/1M input tokens (d1.2-ultra); $0 output tokens
- Image and multi-question metering
- 1.5 tokens per 32x32 patch (1,536 tokens at 1024x1024); shared context billed once per request
- AA Decision Index v2.1 cost
- $133 per 1M Decision Index tasks on d1.2-ultra (score 75); $63 per 1M tasks on d1.2 (score 69)
Release details & context
Held-out audio classification accuracy and extraction evaluation sets
Because public decision suites do not yet cover the five added extraction and spatial tasks, Liquid AI benchmarked them on held-out splits of CORD and SROIE receipts, Nemotron PII documents, RefCOCO/RefCOCO+/RefCOCOg visual grounding and COCO object counting, counting a span read or bounding box as correct only when it locates the target or returns not found when absent.
On held-out audio evaluations where prompts either ask about an audio clip or pose the question itself as spoken audio, both d1.2 and d1.2-ultra answered 95% to 97% of multi-way acoustic event questions on ESC-50 and 43-language spoken identification tasks on FLEURS, including close language pairs such as Spanish and Portuguese.
Common questions
How does the Liquid API bill multiple extraction questions run against the same invoice or image?
Both d1.2 and d1.2-ultra bill the shared document text and image patches once at the input token rate, with each additional question in the request adding only its own prompt tokens and zero output fee.
What do d1.2 and d1.2-ultra return when a requested field or visual object is missing from the input?
Rather than hallucinating a value or bounding box, both models explicitly return not found alongside calibrated confidence scores.
Liquid AI release timeline (3 launches tracked)
- Liquid AI releases LFM2.5-24B-A2B, an open model for agents on laptops and PCs
Liquid AI’s LFM2.5-24B-A2B scores 27.69 on AutomationBench, against 8.72 for the larger Qwen3.6-35B-A3B.
- Liquid AI releases LFM3 open-weight model family with 256K context
Liquid AI released the LFM3 family under open weights, providing 2B-class multimodal models with 256k context that run in 1 GB of memory.