

Open sourceNanbeige LLM LabConfirmed
Story 1 of 2 in the Sunday 25 October editionNanbeige LLM Lab releases Nanbeige4.3-33B under Apache 2.0
Released alongside a base checkpoint with a 512k-token context window, the 33B open-weight model serves as the teacher agent for Nanbeige’s upcoming small-model distillation pipeline.

 Edited by Ashutosh Shrivastava
25 Oct 2026, 23:55 IST · 2 min read
Nanbeige LLM Lab has released Nanbeige4.3-33B and its pretrained base checkpoint, Nanbeige4.3-33B-Base, on Hugging Face under an Apache 2.0 licence. Designed as the flagship 33B teacher model for the Nanbeige4.3 series, the release anchors the lab’s distillation pipeline for upcoming smaller models such as Nanbeige4.3-3B. The model supports a 524,288-token (512k) context window across English and Chinese, uses a configurable chat template with thinking enabled by default, retains prior reasoning turns when preserve_thinking is set to true for multi-turn coding and office workflows, and prefers XML-formatted tool calls alongside JSON compatibility. It runs on Hugging Face Transformers, SGLang and vLLM with four-way tensor parallelism using the Qwen3 reasoning and coder tool parsers.
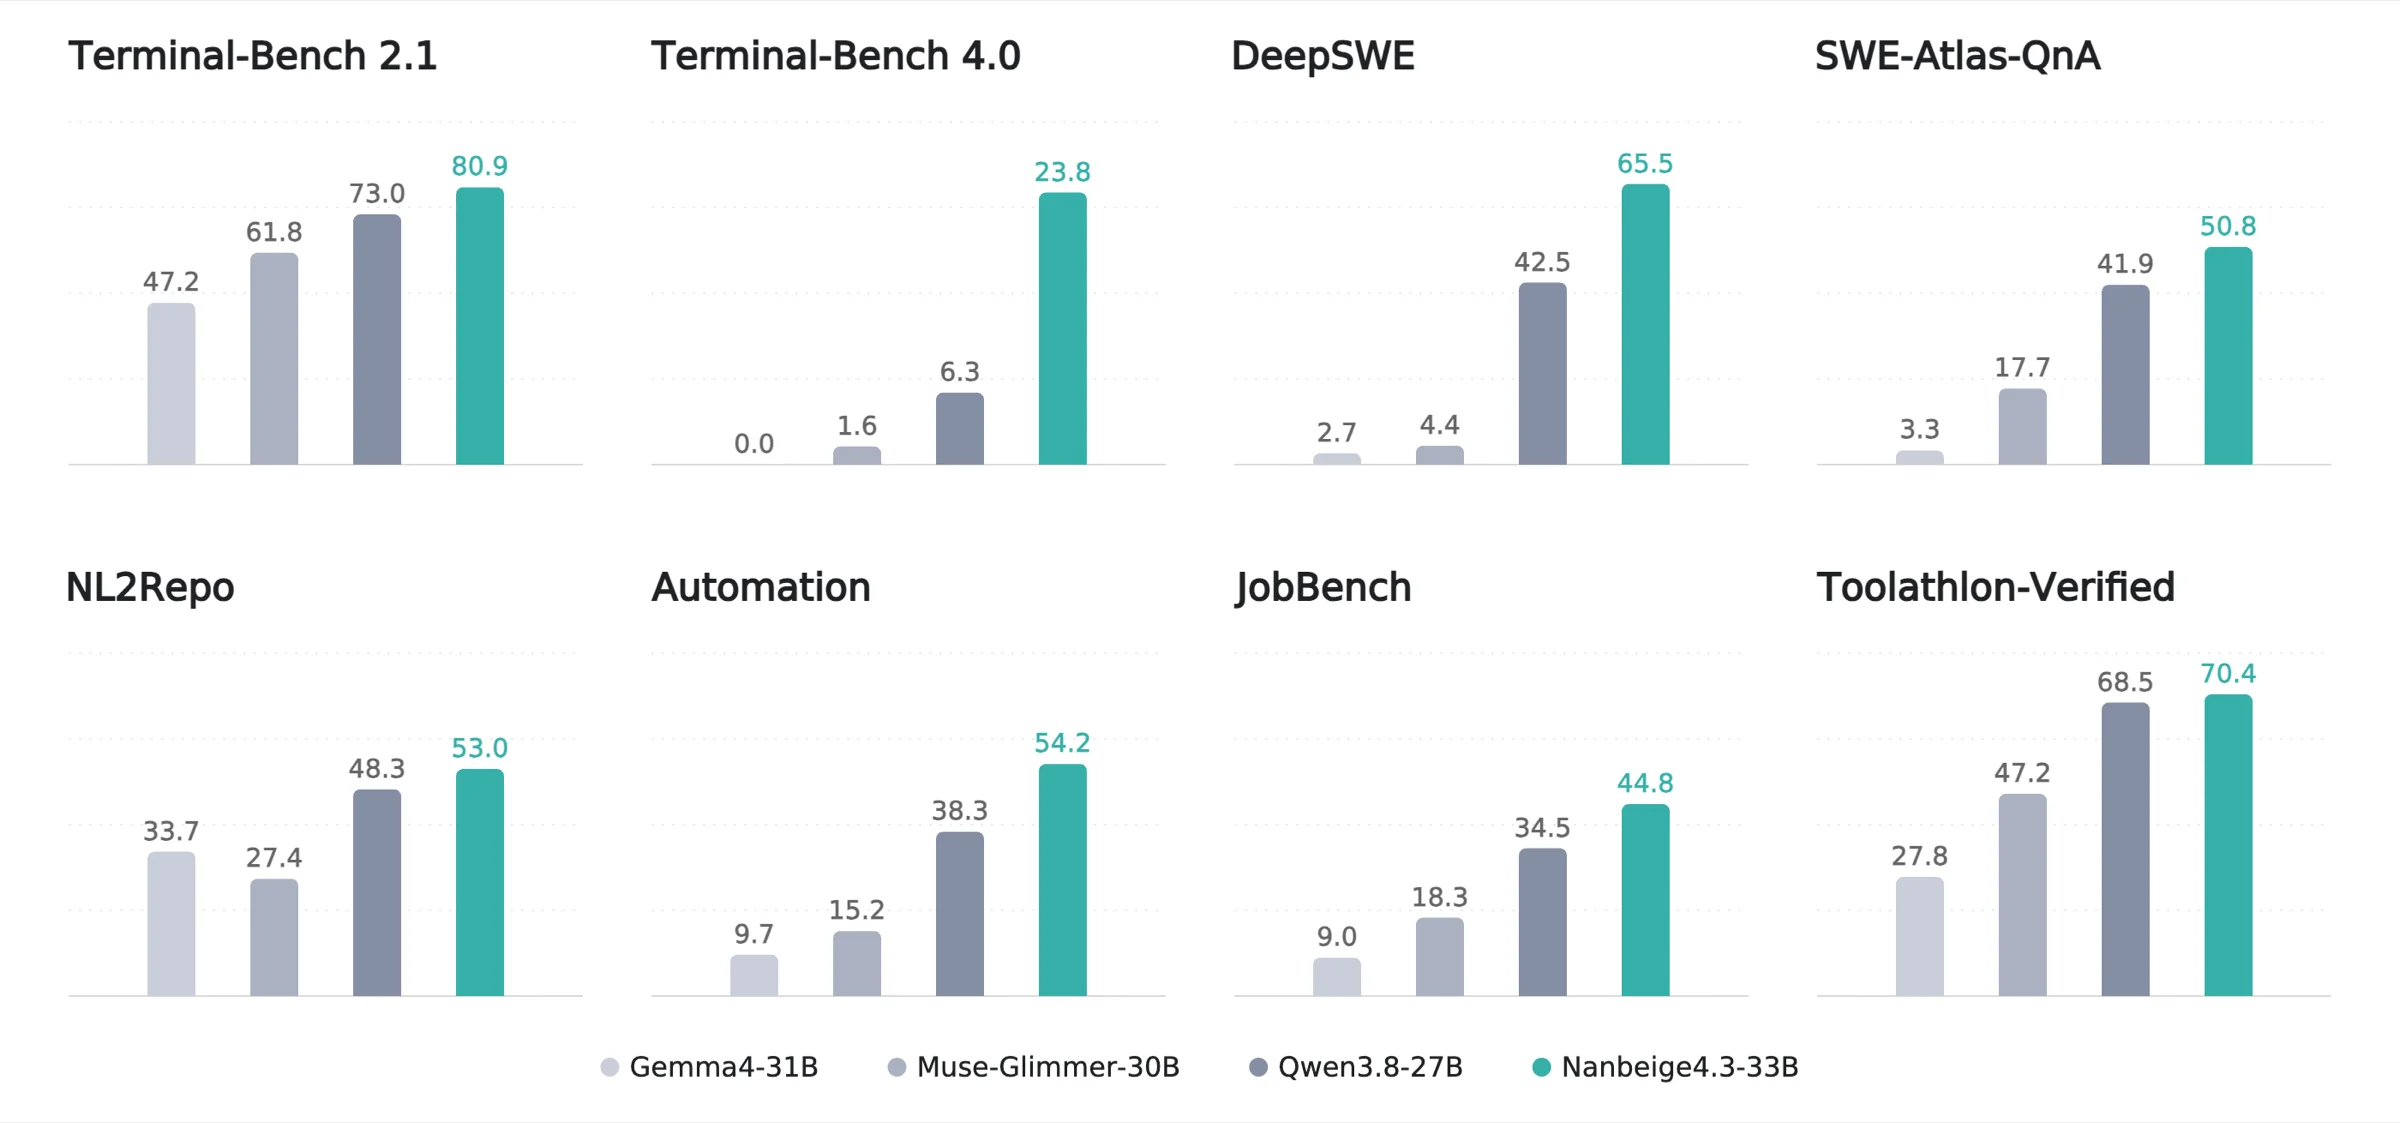
Evaluated at maximum thinking effort with preserve_thinking enabled against 30B-scale open models, Nanbeige4.3-33B leads on 17 of 20 reported coding, cowork and reasoning benchmarks, trailing Qwen3.8-27B slightly on SWE-Bench Pro (60.3 to 61.7) and GDPval (84.8 to 86.4), and Gemma4-31B on GPQA Diamond (89.5 to 91.3). The model card’s summary chart and table differ slightly on two rival scores, listing Gemma4-31B at 33.7 in the chart versus 33.8 in the table on NL2Repo, and Muse-Glimmer-30B at 18.3 in the chart versus 16.6 in the table on JobBench.
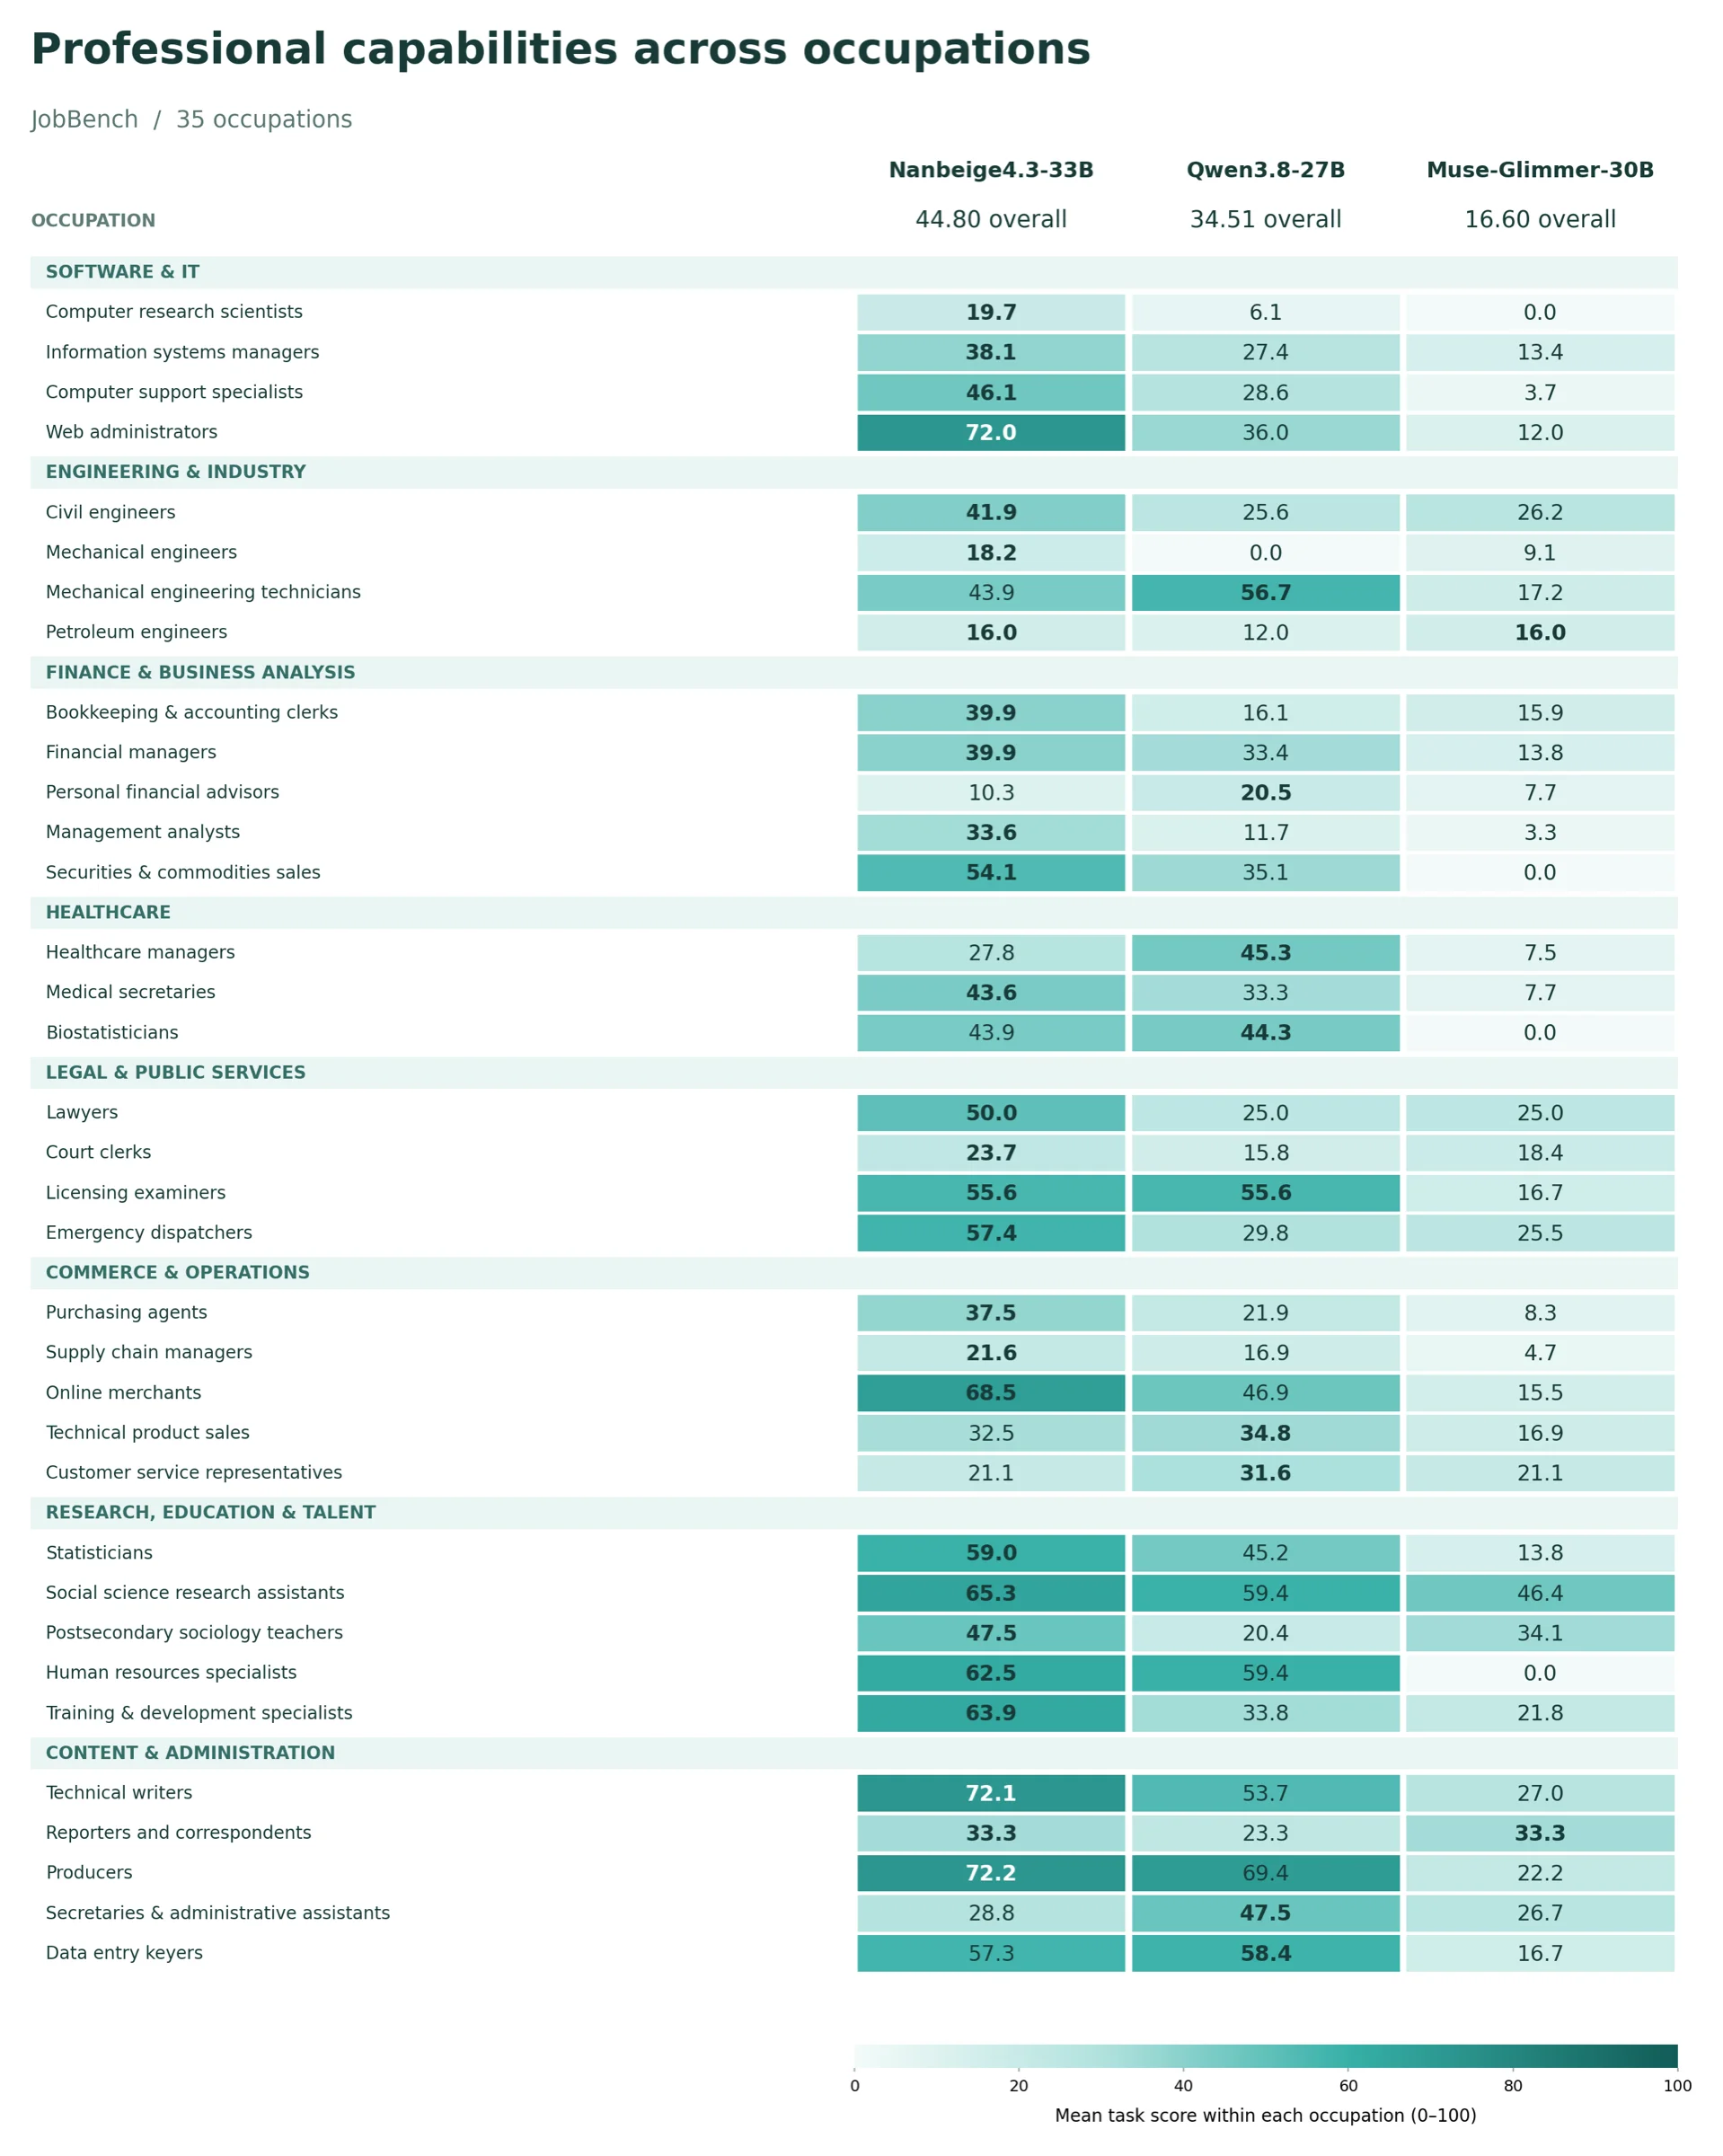
Using the Claude Code harness equipped with a search tool across 35 professional occupations on JobBench, Nanbeige4.3-33B outperforms Qwen3.8-27B and Muse-Glimmer-30B in 29 of the 35 categories, led by producers, technical writers and web administrators.
Key numbers
- Context window: 524,288 tokens (512k), with 65,536 max new tokens recommended for agentic tasks and 262,144 for reasoning
- YC-bench: $1,025,437 across 10-turn dialogue history, compared with $641,290 for Qwen3.8-27B
- Reasoning benchmarks: 95.2 on AIME 2026 and 84.0 on AA-LCR, ahead of Qwen3.8-27B (94.5 and 82.0)
- Licence: Apache 2.0 for both Nanbeige4.3-33B and Nanbeige4.3-33B-Base on Hugging Face
Sources
- PrimaryHugging Face: Nanbeige/Nanbeige4.3-33Bhuggingface.co/Nanbeige
- OfficialHugging Face: Nanbeige/Nanbeige4.3-33B-Basehuggingface.co/Nanbeige
- On XNanbeige (@nanbeige) on Xx.com
The rest of the day
Read the whole day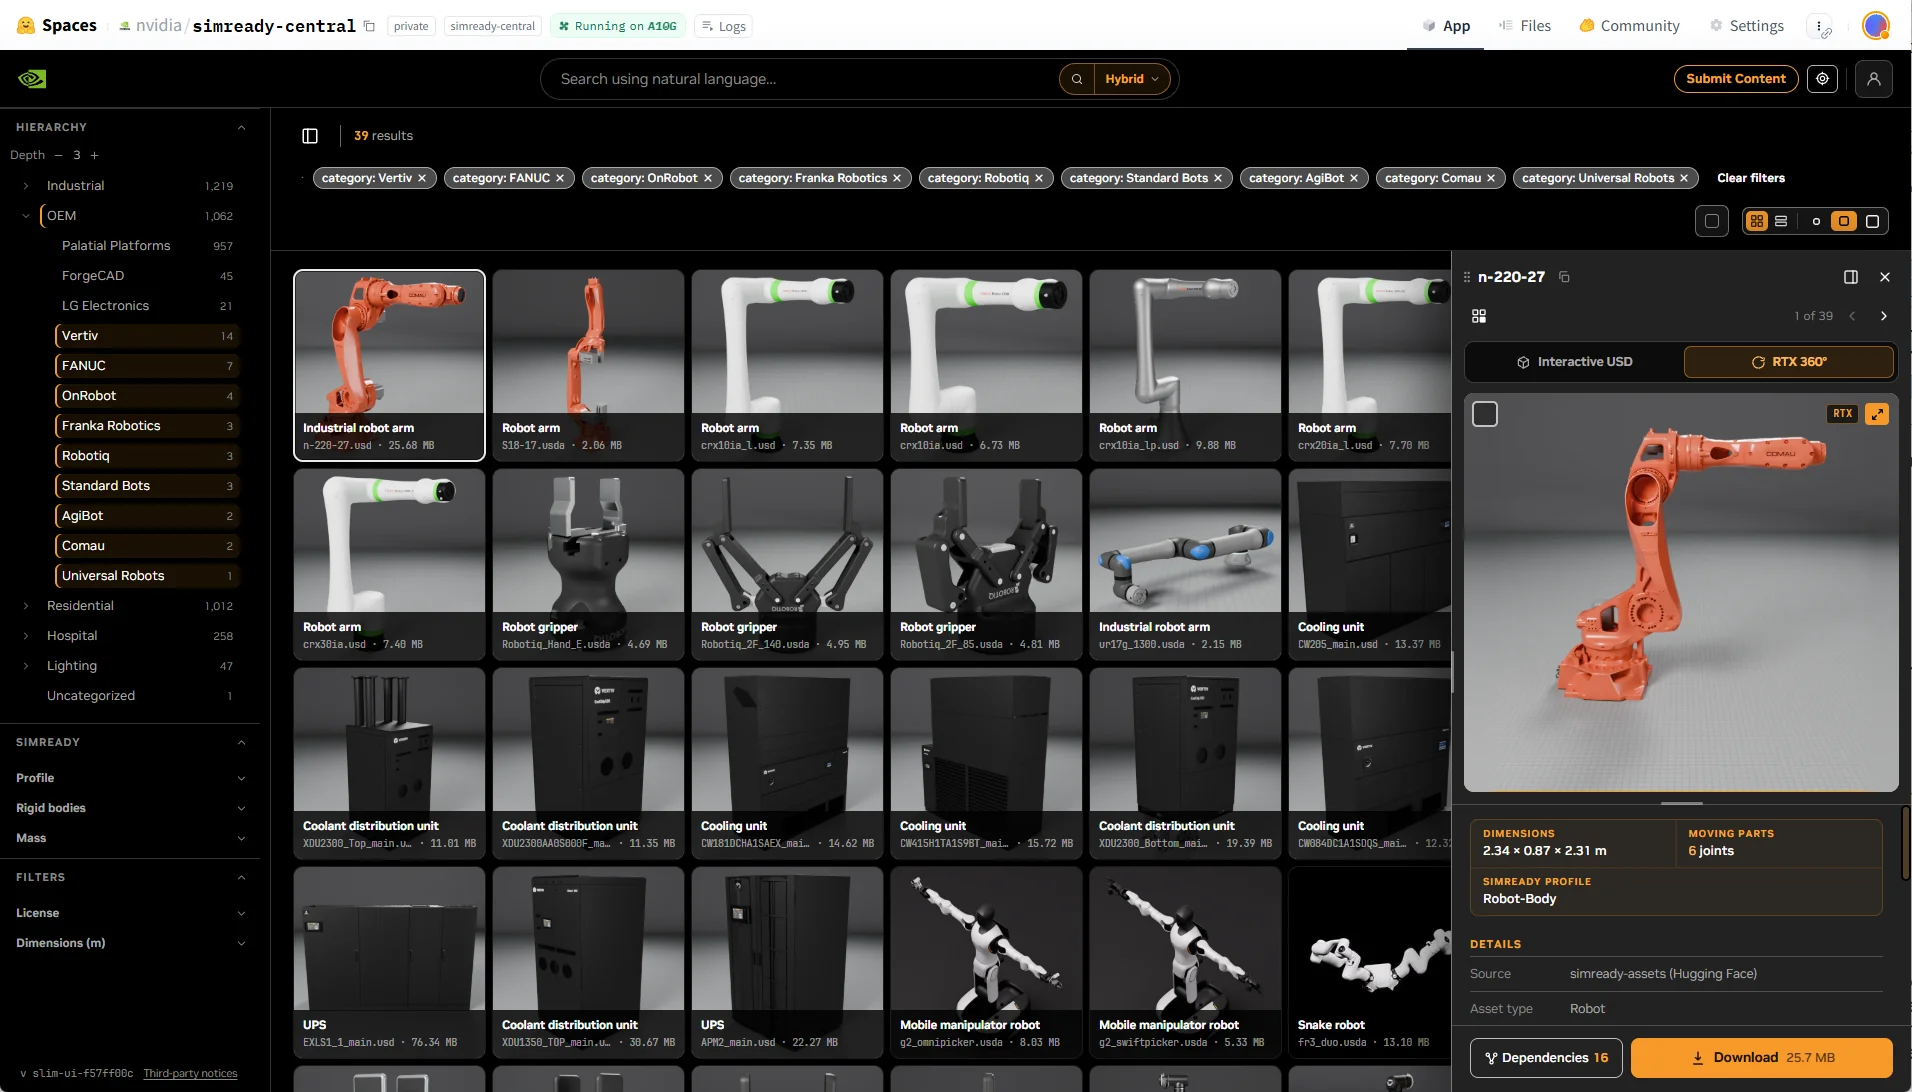
02RoboticsNVIDIA
NVIDIA launches SimReady Central Library with over 2,000 OpenUSD 3D assets on Hugging Face
Announced on 21 October 2026 on the Hugging Face blog, the free library provides physics-validated OpenUSD models of robot arms, grippers, appliances and data-centre cooling gear for Isaac Sim and AI factory digital twins.
Spotted an error? Email aiforsuccess.in+compass@gmail.com or tag @ai_for_success on X