

ModelQwenConfirmed
Story 1 of 15 in the Monday 16 November editionQwen launches 2.4T Qwen4-Max MoE model at $1.5 and $4.5 per million
Live on QwenCloud with OpenAI- and Anthropic-compatible APIs alongside Qwen Studio, QwenWork and Qoder, the 1M-context multimodal model activates 71B parameters per token.

 Edited by Ashutosh Shrivastava
17 Nov 2026, 09:20 IST · 3 min read
Alibaba’s Qwen released flagship Qwen4-Max on 16 November 2026 across QwenCloud, Qwen Studio, QwenWork and Qoder, following its 10 November Qwen4-Max preview on Alibaba Token Plan. Built on the new Qwen4 sparse Mixture-of-Experts architecture, the checkpoint combines 2.4 trillion backbone parameters, 71 billion active parameters per token and 328 billion N-gram Embedding parameters with native image and video understanding across a 1-million-token context window.
Gated DeltaNet, Qwen Sparse Attention and QwenCloud API rates
Every Qwen Sparse Attention layer pairs with three Gated DeltaNet layers that compress sequence history into fixed-size states while a micro-block indexer selects relevant long-context spans. Four parallel Gated Residual branches with dynamic read-write gates and second-layer N-gram Embeddings kept the 2.4T pre-training run free of loss spikes, lowering bits per byte by 5% to 13% over Qwen3.8-Max-Base with 25% fewer active parameters.
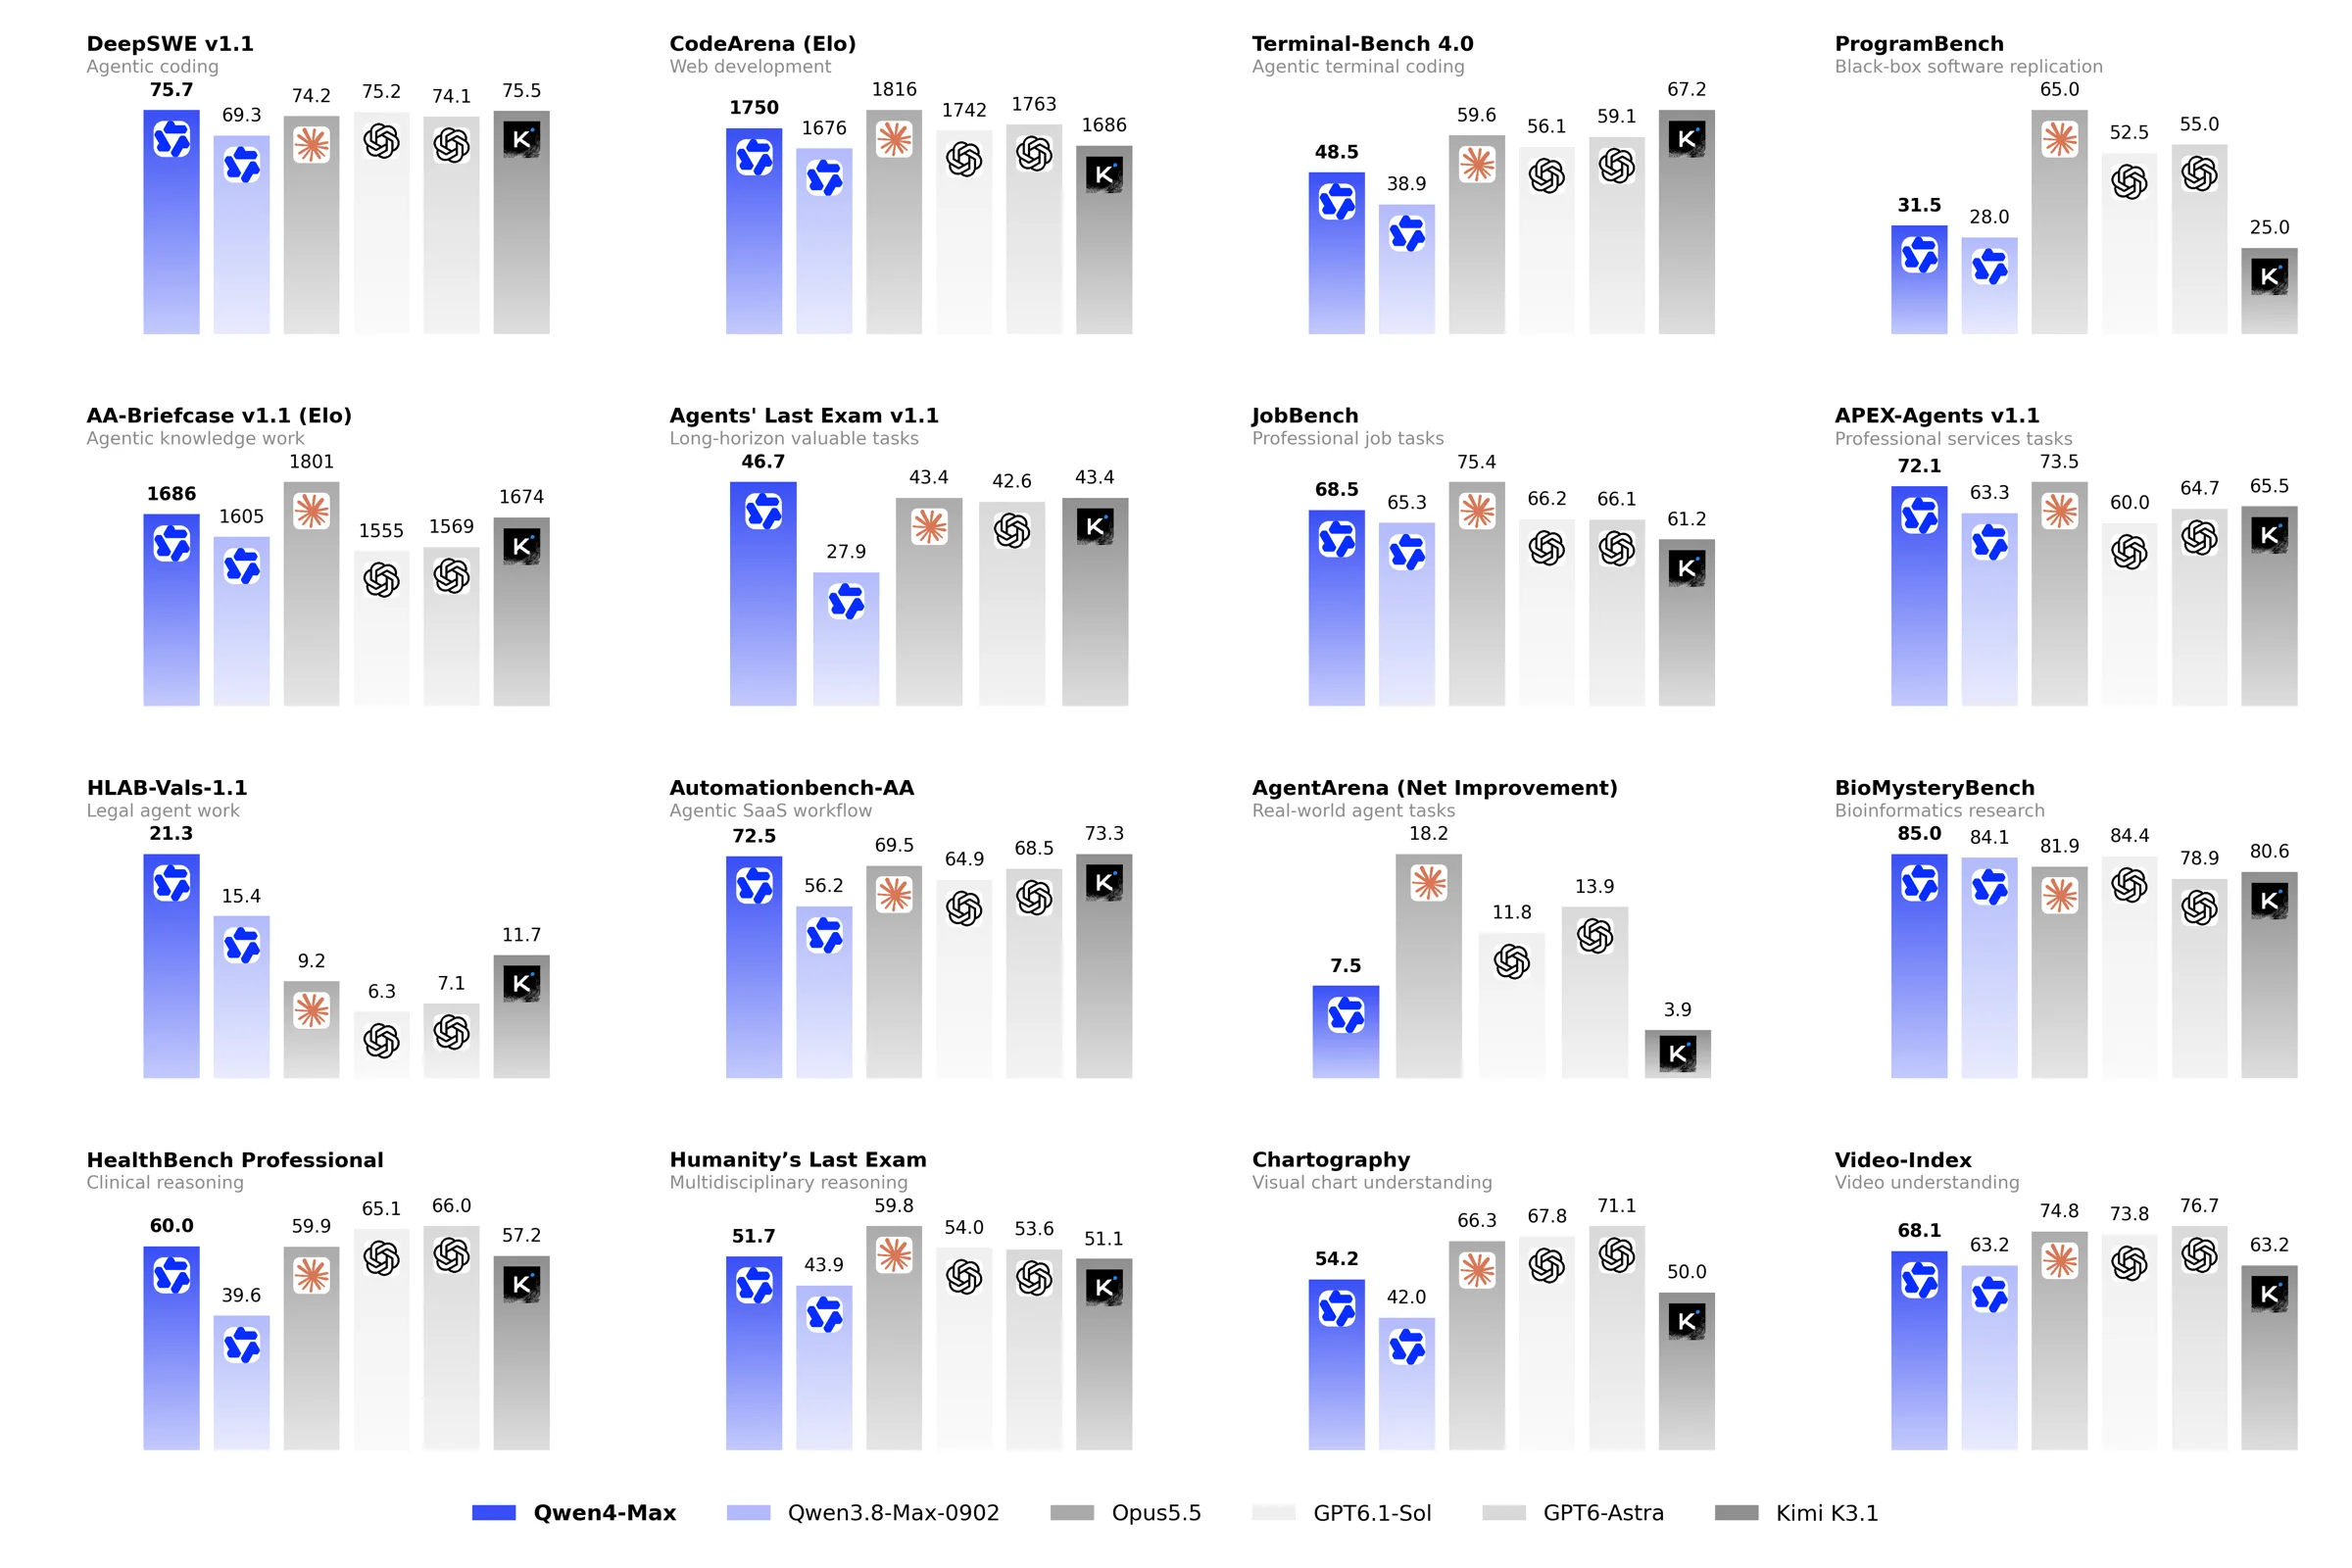
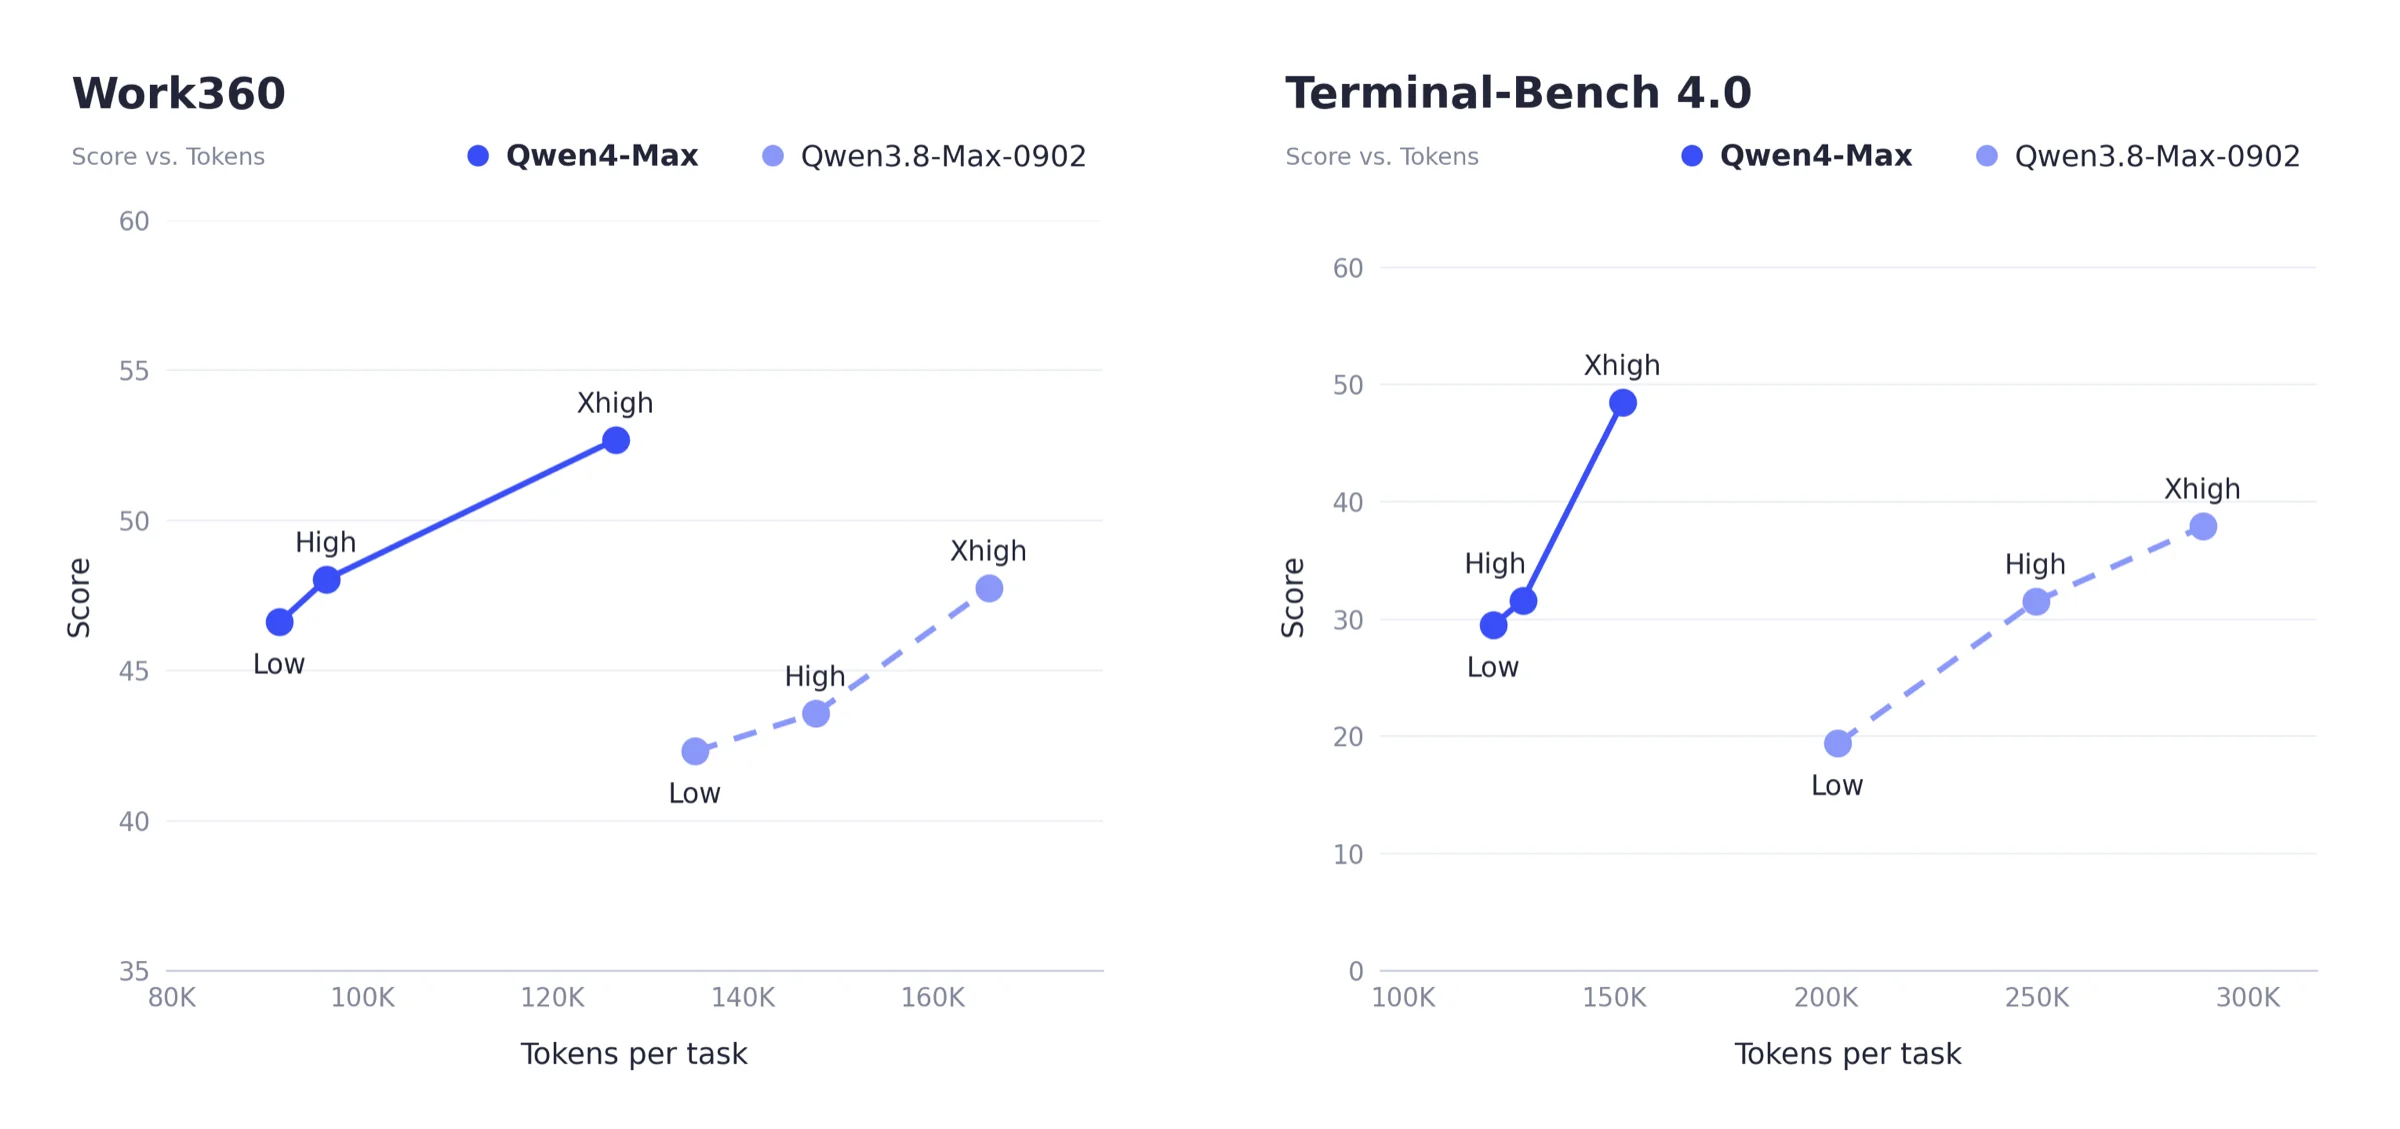
On QwenCloud, Qwen4-Max supports prefix completion, function calling and structured outputs over OpenAI- and Anthropic-compatible endpoints at $1.5 per million input tokens, $4.5 per million output tokens and $0.075 per million implicit or explicit cache reads (down 70% on implicit cache versus Qwen3.8-Max). On Work360 across 721 specialised fields, average task spend fell 62% from $4.43 to $1.67, while Arena placed Qwen4-Max 14th overall (first among Chinese models) on Agent Arena across 14.7k sessions. Qwen stated that open weights for smaller Qwen4 models are planned, without announcing a release date.
Technical details
- Model architecture
- 2.4T sparse MoE backbone, 71B active per token + 328B N-gram Embedding (GDN + QSA + Gated Residual)
- Context and output limits
- 991k input / 131k output standard; 983k input / 262k reasoning and output in thinking mode (5M TPM)
- QwenCloud API pricing (per 1M)
- $1.5 input, $4.5 output, $0.075 cache read, $1.875 5-min explicit cache write, $3 1-hour cache write
- Live surfaces and protocols
- QwenCloud API (OpenAI and Anthropic compatible), Token Plan (from $3 promo), Qwen Studio, QwenWork and Qoder
Release details & context
Explicit cache write tiers, thinking token budgets and 3D Blender workflows
On QwenCloud’s rate card, standard non-thinking calls accept up to 991k input tokens and 131k output tokens, whereas enabling thinking mode allocates up to 262k reasoning and output tokens inside a 983k input ceiling at a 5-million-token-per-minute quota, alongside explicit prompt-cache creation priced at $1.875 per million tokens for five-minute retention or $3 for one-hour retention.
In downstream workflows highlighted by Qwen, Qwen4-Max drives Blender geometry modelling, lighting and rendering for 3D printing and game assets, and rises from 39th for Qwen3.8-Max to 14th overall on Agent Arena (+13% net Praise vs Complaint on Agent Arena and 1750 on CodeArena WebDev).
Common questions
How does QwenCloud’s context ceiling differ between standard and thinking modes on Qwen4-Max?
Standard calls accept up to 991k input tokens and 131k output tokens, while thinking mode accepts up to 983k input tokens with up to 262k reasoning and output tokens.
Are open weights available for the 2.4-trillion-parameter Qwen4-Max flagship model?
No, Qwen4-Max is served via QwenCloud and Qwen apps, while Qwen stated that open weights will be released later for smaller models in the Qwen4 family.
Sources
- PrimaryQwen: Qwen4-Max: Your New Teammate Has Arrivedqwen.ai
- OfficialQwen4-Max Model & API Pricing on QwenCloudqwencloud.com
- OfficialQwenCloud Token Planqwencloud.com
- On XQwen (@Alibaba_Qwen) launch post on Xx.com
- On XArena (@arena) Agent Arena debut thread on Xx.com
Qwen release timeline (3 launches tracked)
- Qwen’s QwenGyre framework speeds up training AI agents on hours-long tasks
Qwen’s QwenGyre paper reports training agents on hours-long tasks up to 1.85 times faster.
- Qwen previews Qwen4-Max flagship model on Alibaba Token Plan
Qwen opens early preview access to Qwen4-Max across Alibaba’s Token Plan, QwenWork, Qoder, the Qwen app and QwenStudio for coding and agentic workflows.