

ModelMicrosoftConfirmed
Story 1 of 18 in the Tuesday 17 November editionMicrosoft unveils seven MAI models, Maia 300, Microsoft IQ and Autopilot
Spanning GitHub Copilot, Microsoft Foundry and private Azure MAI Licensed Weights alongside generally available Cobalt 200 VMs and Foundry IQ retrieval at Ignite on 17 November 2026.

 Edited by Ashutosh Shrivastava
18 Nov 2026, 09:45 IST · 3 min read
Microsoft opened Ignite 2026 in San Francisco on 17 November 2026 with seven task-specialised MAI models, private Azure weight licensing, next-generation custom silicon, the Microsoft IQ context platform and autonomous Copilot modes. Across coding and security, MAI Code 2 and MAI Code 2 Flash reached general availability in GitHub Copilot, hitting 98% of GPT-6.1 Sol’s coding score at 40% of the cost and 96% of Claude Opus 5.5 at 5% of the cost, while MAI Cyber 2 Flash scored 92.3% on CyberGym-E2E at $0.10 input and $0.50 output per million tokens.
Multimodal MAI endpoints, Maia 300 silicon and Microsoft Retriever 1
MAI Image 2.7 ranked first on Artificial Analysis Image Editing v2.1 at $34.82 per 1,000 images alongside MAI Image 2.7 Flash ($10.24 per 1,000) and an interactive Canvas workspace. MAI Realtime 1 launched for speech-to-speech agents at $0.01 per audio minute, Dragon Copilot Transcribe built on MAI Transcribe 2 scaled across 10 million monthly clinical encounters, and multimodal microsoft-decision-1.1 hit general availability on Foundry, OpenRouter and Vercel.
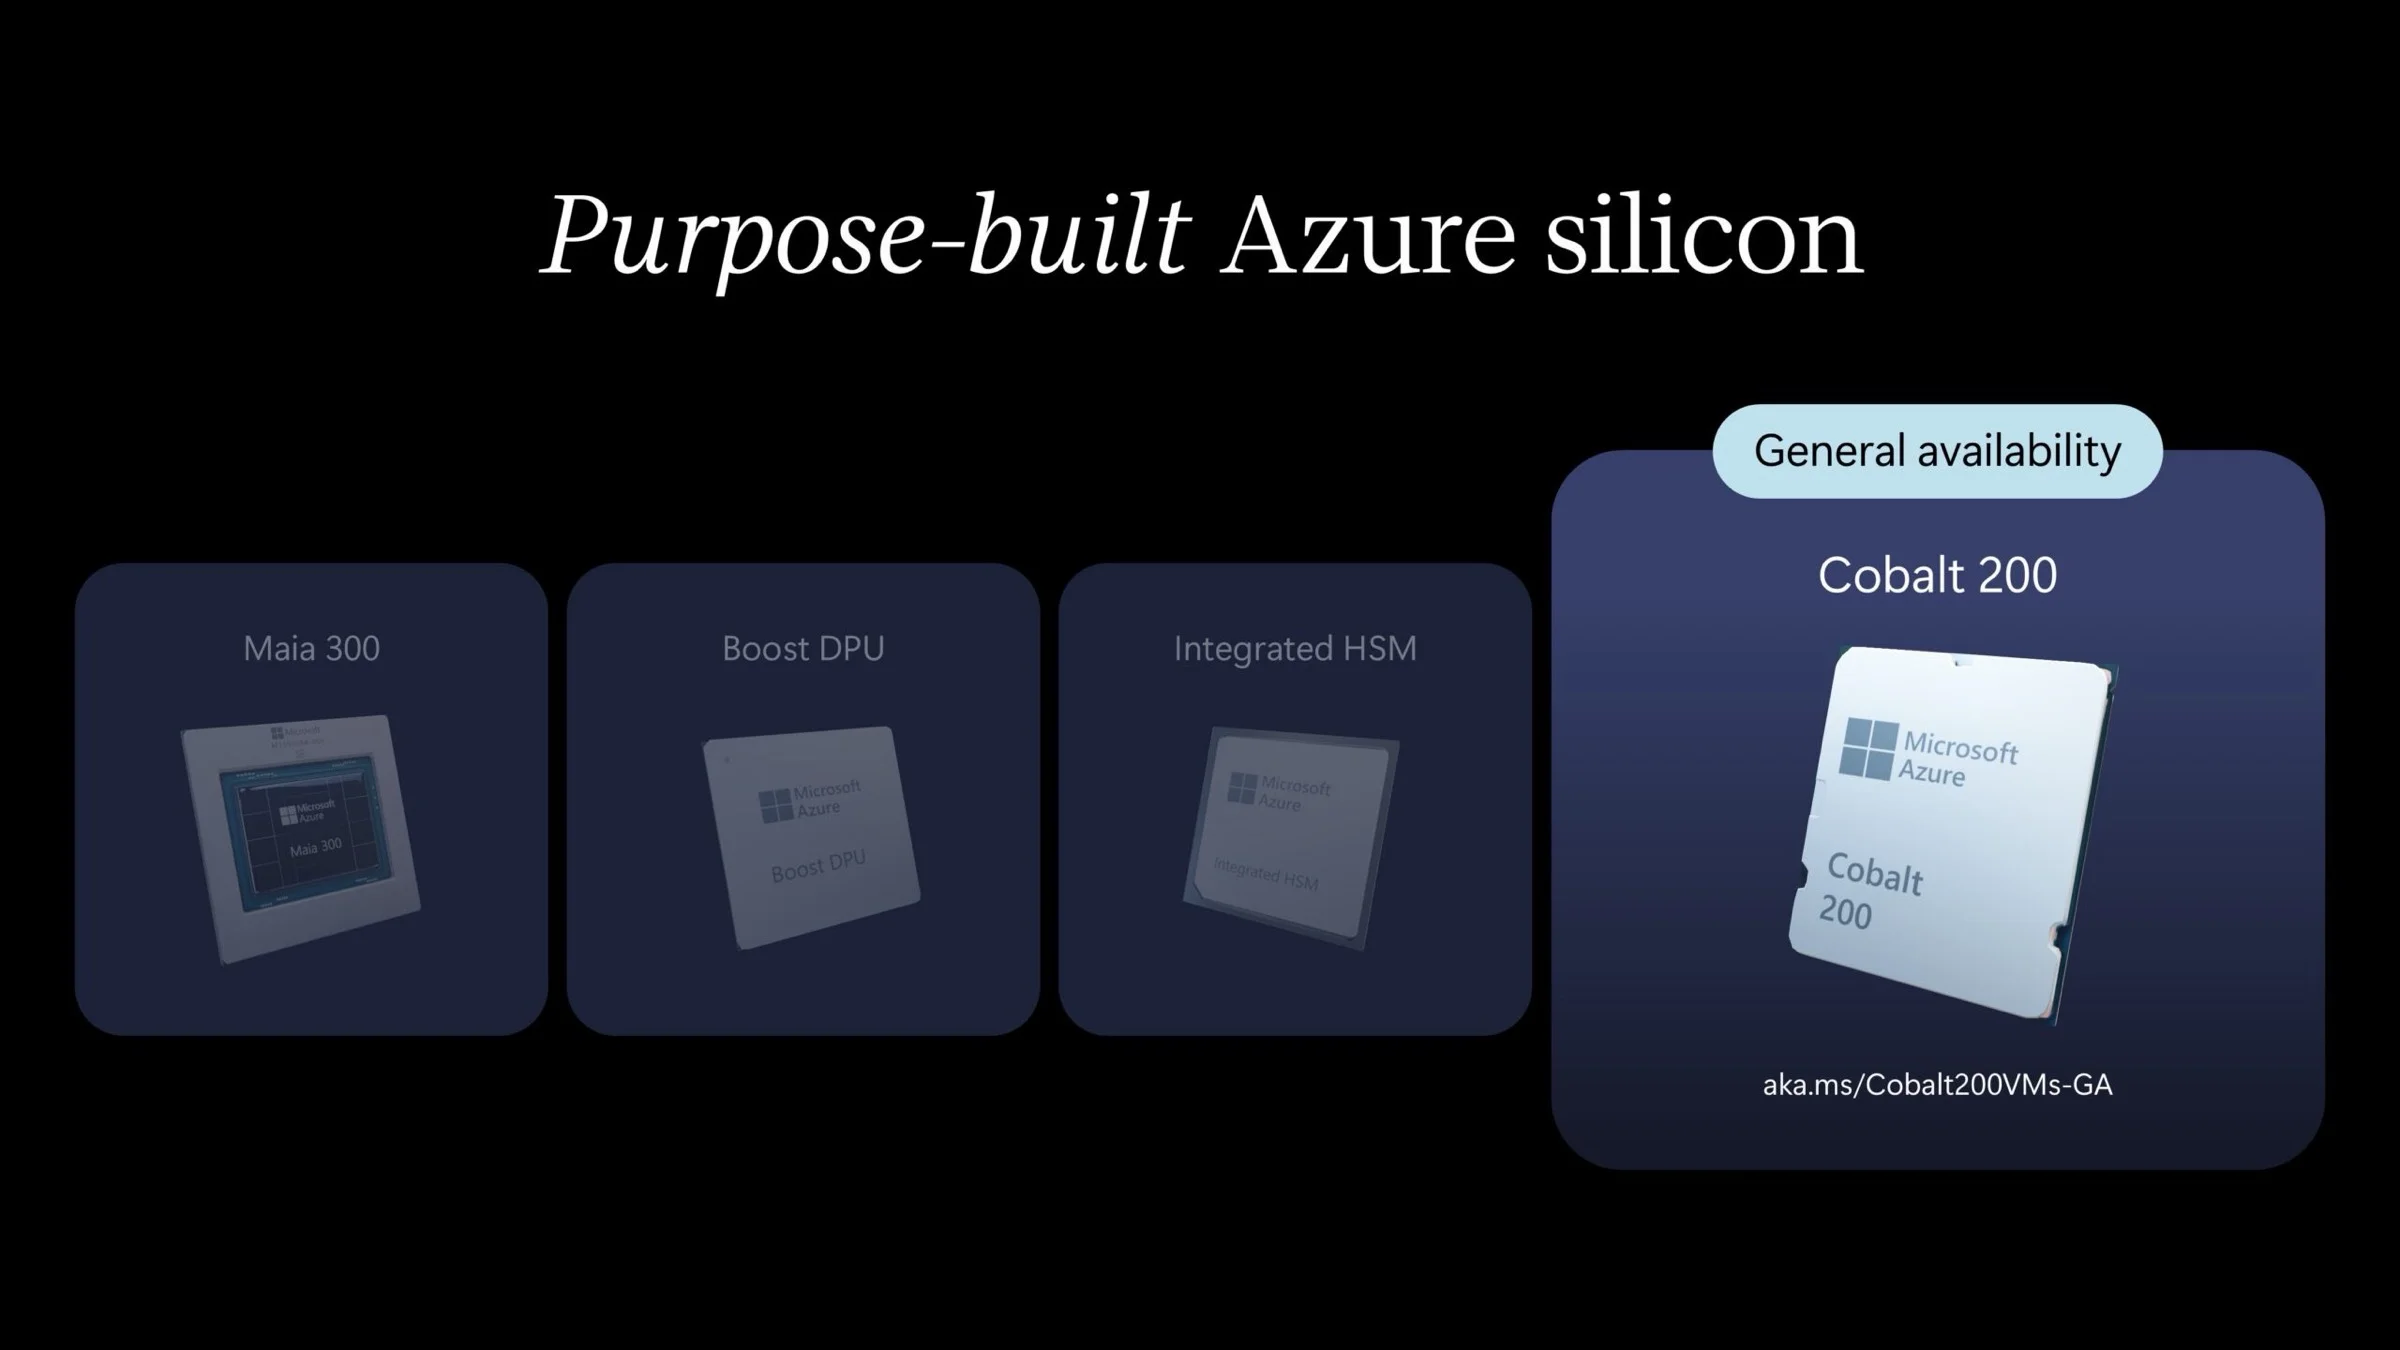
Under MAI Licensed Weights, enterprises fine-tune and host MAI checkpoints inside private Azure tenants. Chief executive Satya Nadella unveiled Maia 300 accelerators targeting 40% more tokens per watt than rival GPU clusters, confirmed Maia 200 in production at 1.7 times more tokens per watt, and shipped Cobalt 200 VMs and HorizonDB generally. Microsoft also launched Microsoft IQ with preview microsoft-retriever-1 cutting retrieval latency 85% to 0.76s, 24-hour Copilot Autopilot, Copilot Workspaces, Salesforce plugins and generally available Microsoft Perception security agents.
Technical details
- Seven MAI models launched
- MAI Code 2, MAI Code 2 Flash, MAI Cyber 2 Flash, MAI Image 2.7 (plus Flash), MAI Realtime 1, Dragon Copilot Transcribe and microsoft-decision-1.1
- Published MAI pricing
- MAI Cyber 2 Flash $0.10/$0.01/$0.50 per 1M; MAI Image 2.7 $34.82/1k (Flash $10.24/1k); MAI Realtime 1 from $0.01/audio min
- Custom Azure silicon
- Maia 200 in production (1.7x tokens/watt); Maia 300 unveiled (+40% tokens/watt vs GPUs); Cobalt 200 ARM VMs generally available
- Microsoft IQ and security stack
- Work IQ, Fabric IQ, Web IQ (GA), Foundry IQ with microsoft-retriever-1 preview, Agent 365 FinOps and Microsoft Perception (GA)
Release details & context
Decision 1.1 MoE backbone, Web IQ commerce index and Agent 365 governance
Under the hood, microsoft-decision-1.1 fine-tunes a Gemma 4 26B A4B Mixture-of-Experts checkpoint behind a custom non-autoregressive decision inference engine across A100, H100, H200, GB200 and GB300 fleets, adding screenshot and photo inputs for more than 4,000 existing customers while running 50 times faster and 79 times cheaper than GPT-6.1 Sol.
Alongside Foundry IQ knowledge graphs, generally available Web IQ introduces Auto and Auto Advanced iterative web grounding with Weather and Places GA plus a 40-billion-offer Commerce private preview. Across enterprise governance, Agent 365 already tracks more than 50 million deployed agents, paired with Agent 365 Business Analytics and the 40-partner Microsoft AI Transparency Initiative.
Common questions
How does MAI Licensed Weights differ from standard Microsoft Foundry API endpoints?
MAI Licensed Weights lets enterprise customers license frontier MAI checkpoints through Frontier Co., fine-tune them on proprietary data and run the resulting weights inside their own Azure tenant without Microsoft training on those adaptations.
How much latency and token spend does Microsoft Retriever 1 save inside Foundry IQ?
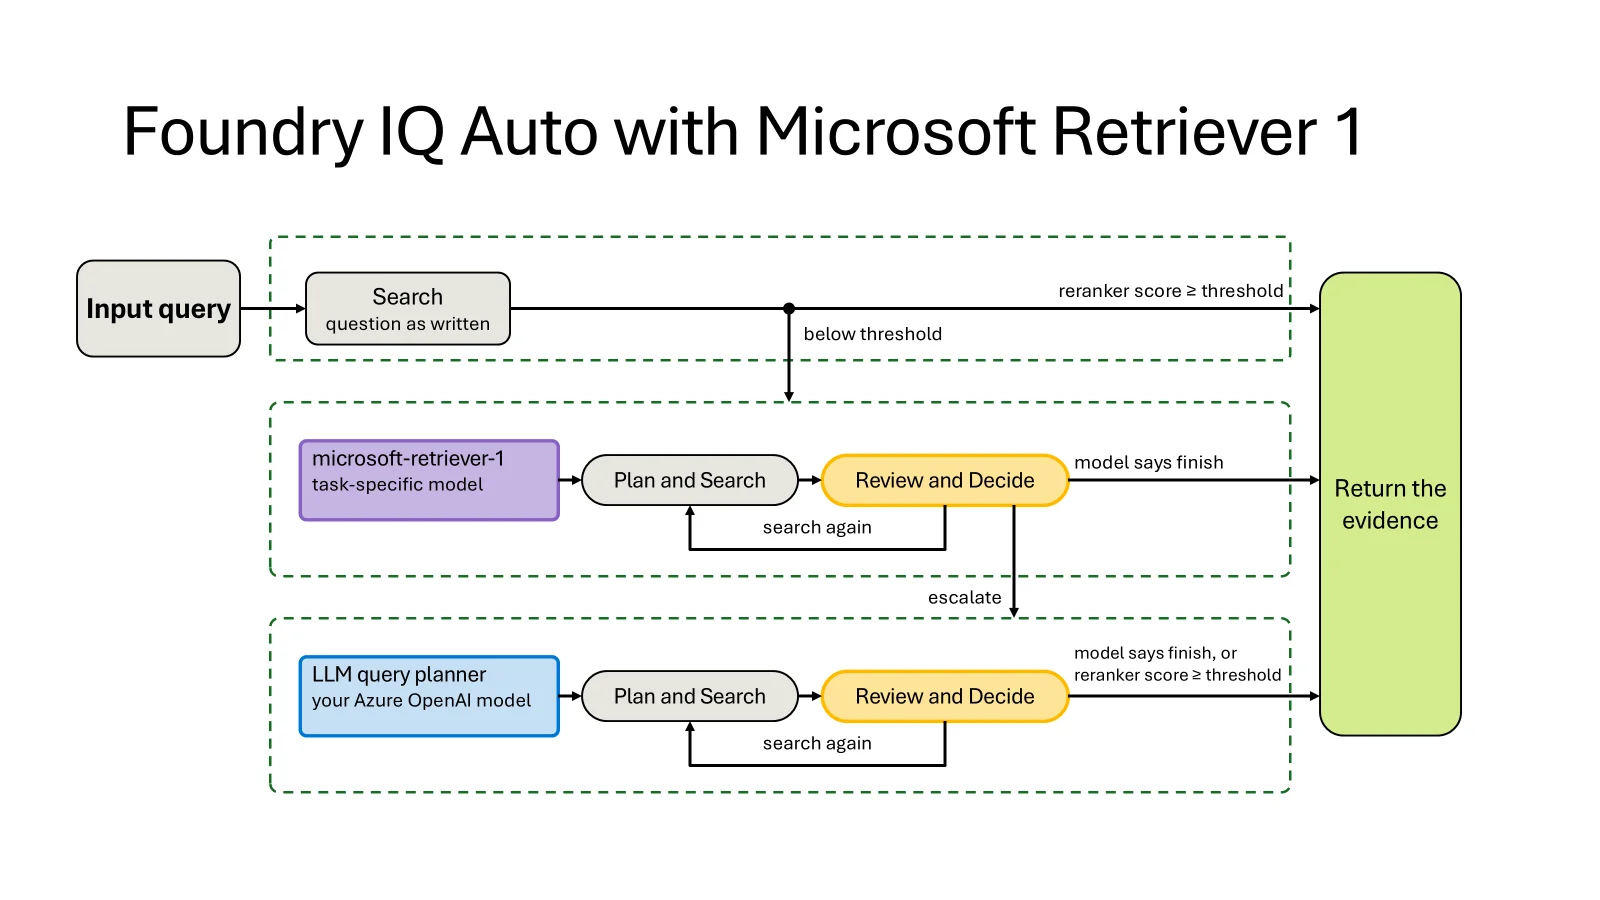
Pairing microsoft-retriever-1 with auto retrieval reasoning effort handles 80% of queries without escalating to an external LLM, cutting median latency 85% from 5.09s to 0.76s and lowering GPT-6.1 Sol token usage by 83.6% while keeping 90% recall.
Sources
- PrimaryMicrosoft: Seven new world class models at scalable price-performancemicrosoft.ai
- OfficialOfficial Microsoft Blog: Ignite 2026: Building the frontier ecosystemblogs.microsoft.com
- OfficialMicrosoft Ignite 2026 Book of Newsnews.microsoft.com
- OfficialMicrosoft-Decision-1.1 general availabilitycommandline.microsoft.com
- OfficialMicrosoft Retriever 1 brings sub-second agentic retrieval to Foundry IQtechcommunity.microsoft.com
- OfficialMAI Code 2 and MAI Code 2 Flash in GitHub Copilotgithub.blog
Microsoft release timeline (8 launches tracked)
- Microsoft AI publishes MAI-DxO sequential diagnosis study in Science and open-sources SDBench
Microsoft AI published its MAI-DxO study in Science, reaching 83% accuracy on 304 NEJM cases (versus 22% closed-book and 36% open-book for physicians).
- Microsoft launches MAI-Image-2.7 in preview and makes MAI-Image-2.6 generally available
Microsoft introduced MAI-Image-2.7 in preview and brought MAI-Image-2.6 and 2.6-Flash to general availability in Azure AI Foundry.
- Microsoft brings the multi-model Copilot harness to Microsoft Foundry
Microsoft exposes the Rust-based Copilot harness in Foundry as an SDK and managed service supporting 20+ models, MCP tools, and BYOK deployments.
- Microsoft AI introduces MAI Transcribe 2 speech model at $0.10 per audio hour
Microsoft AI launches MAI Transcribe 2 across 60 languages at $0.10 per batch hour, transcribing 1 hour in 10 seconds at a 5.2% FLEURS WER.