

ModelGoogleConfirmed
Story 1 of 13 in the Thursday 12 November editionGoogle launches Gemini 4 Hydrogen for everyday coding and agents
Available as gemini-4-hydrogen across Google AI Studio, the Gemini API, Android Studio and Antigravity on 12 November 2026, the model runs 2.5 times faster than Gemini 3.8 Flash and reaches 54 on Artificial Analysis.

 Edited by Ashutosh Shrivastava
13 Nov 2026, 09:15 IST · 3 min read
Google launched Gemini 4 Hydrogen on 12 November 2026, two days after introducing Gemini 4 Carbon, positioning the model ID gemini-4-hydrogen as its workhorse for coding, research and multi-step agent loops. Developers can call the model across Google AI Studio (including a free tier), the Gemini API and Android Studio, while paid Google AI Pro and Ultra subscribers receive access in Google Antigravity and the Gemini app dropdown. Free Gemini app users get it via automatic model routing, Google Search upgrades AI Mode query fan-out with it, and Google Sheets canvas workflows run more than 30% faster.
Configurable thinking, Orchestrator routing and benchmark charts
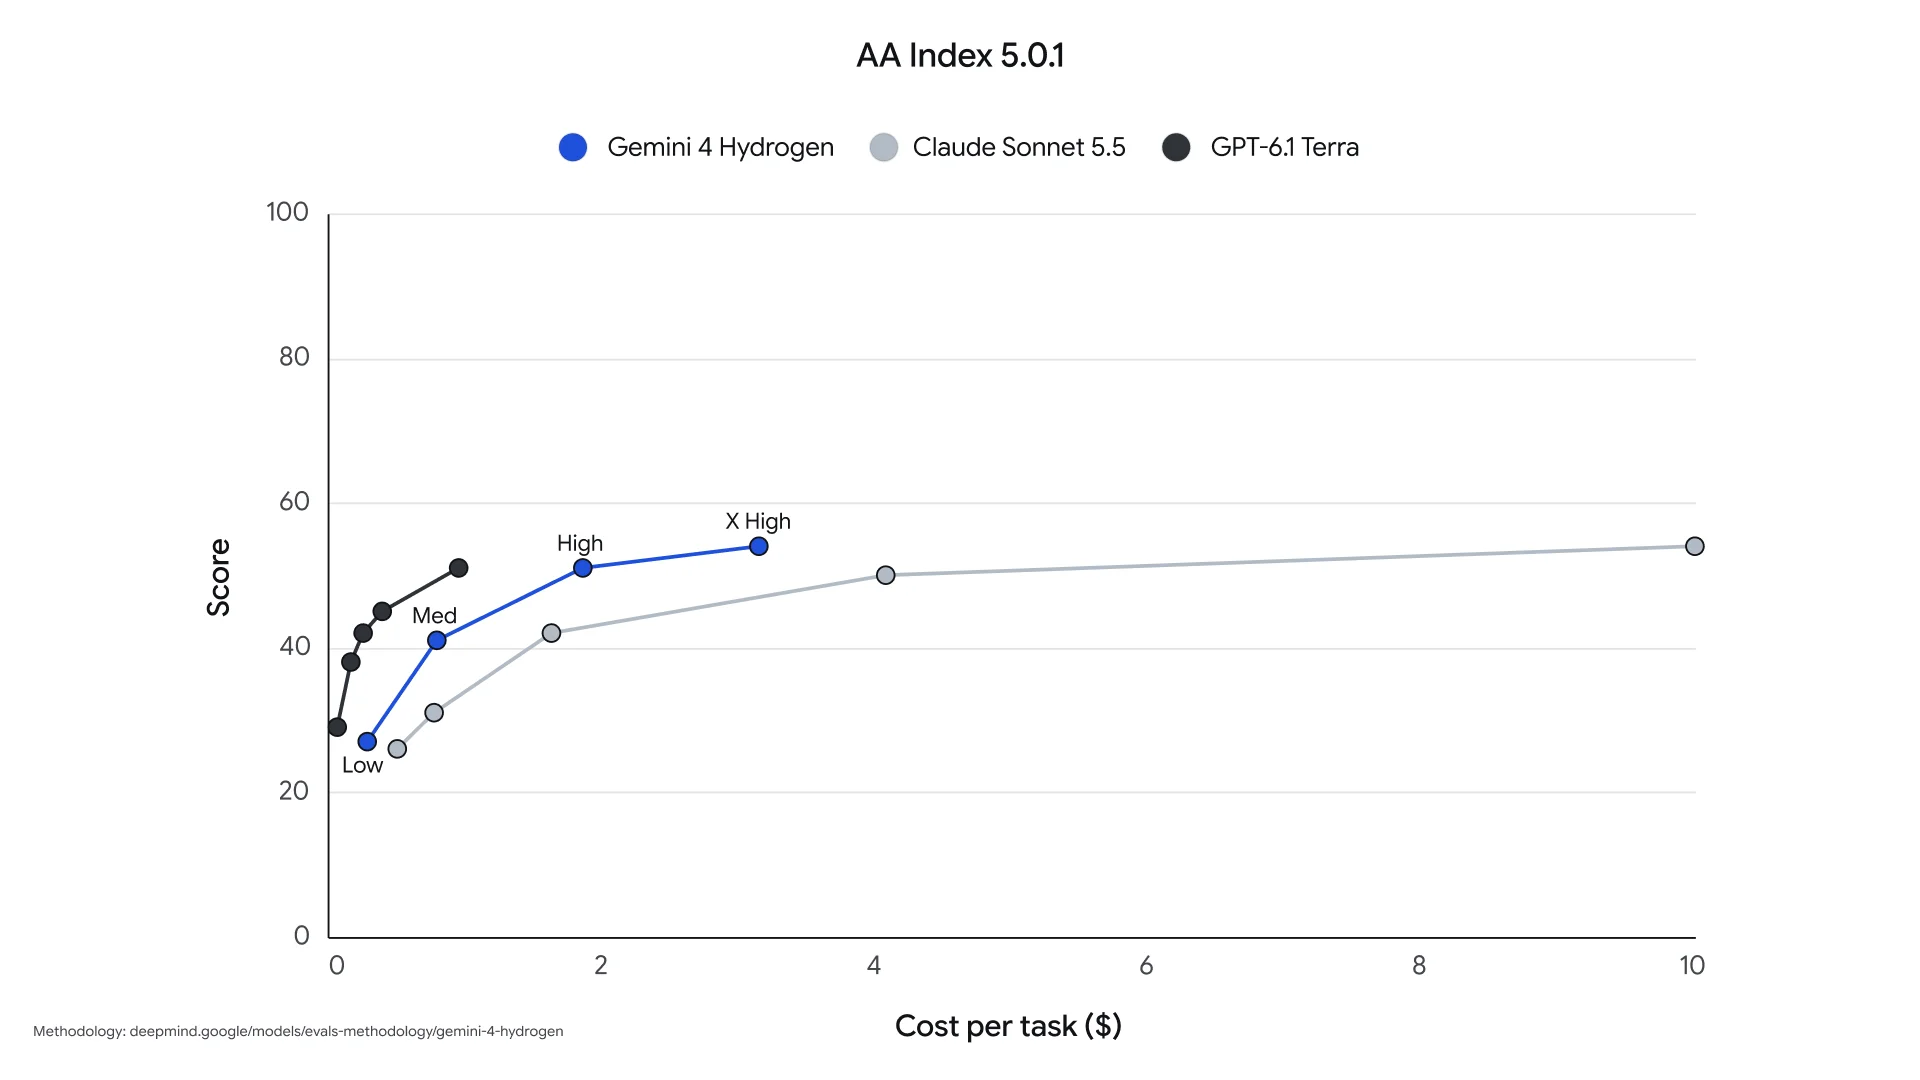
Gemini 4 Hydrogen exposes four thinking levels (low, medium, default high and xhigh) across a 1M-token input and 1M-token output window so engineers can trade latency against deeper multi-turn tool verification. On the Artificial Analysis Intelligence Index 5.0.1, it scores 51 at default high thinking (ahead of Gemini 4 Argon at 50) and climbs to 54 at xhigh.
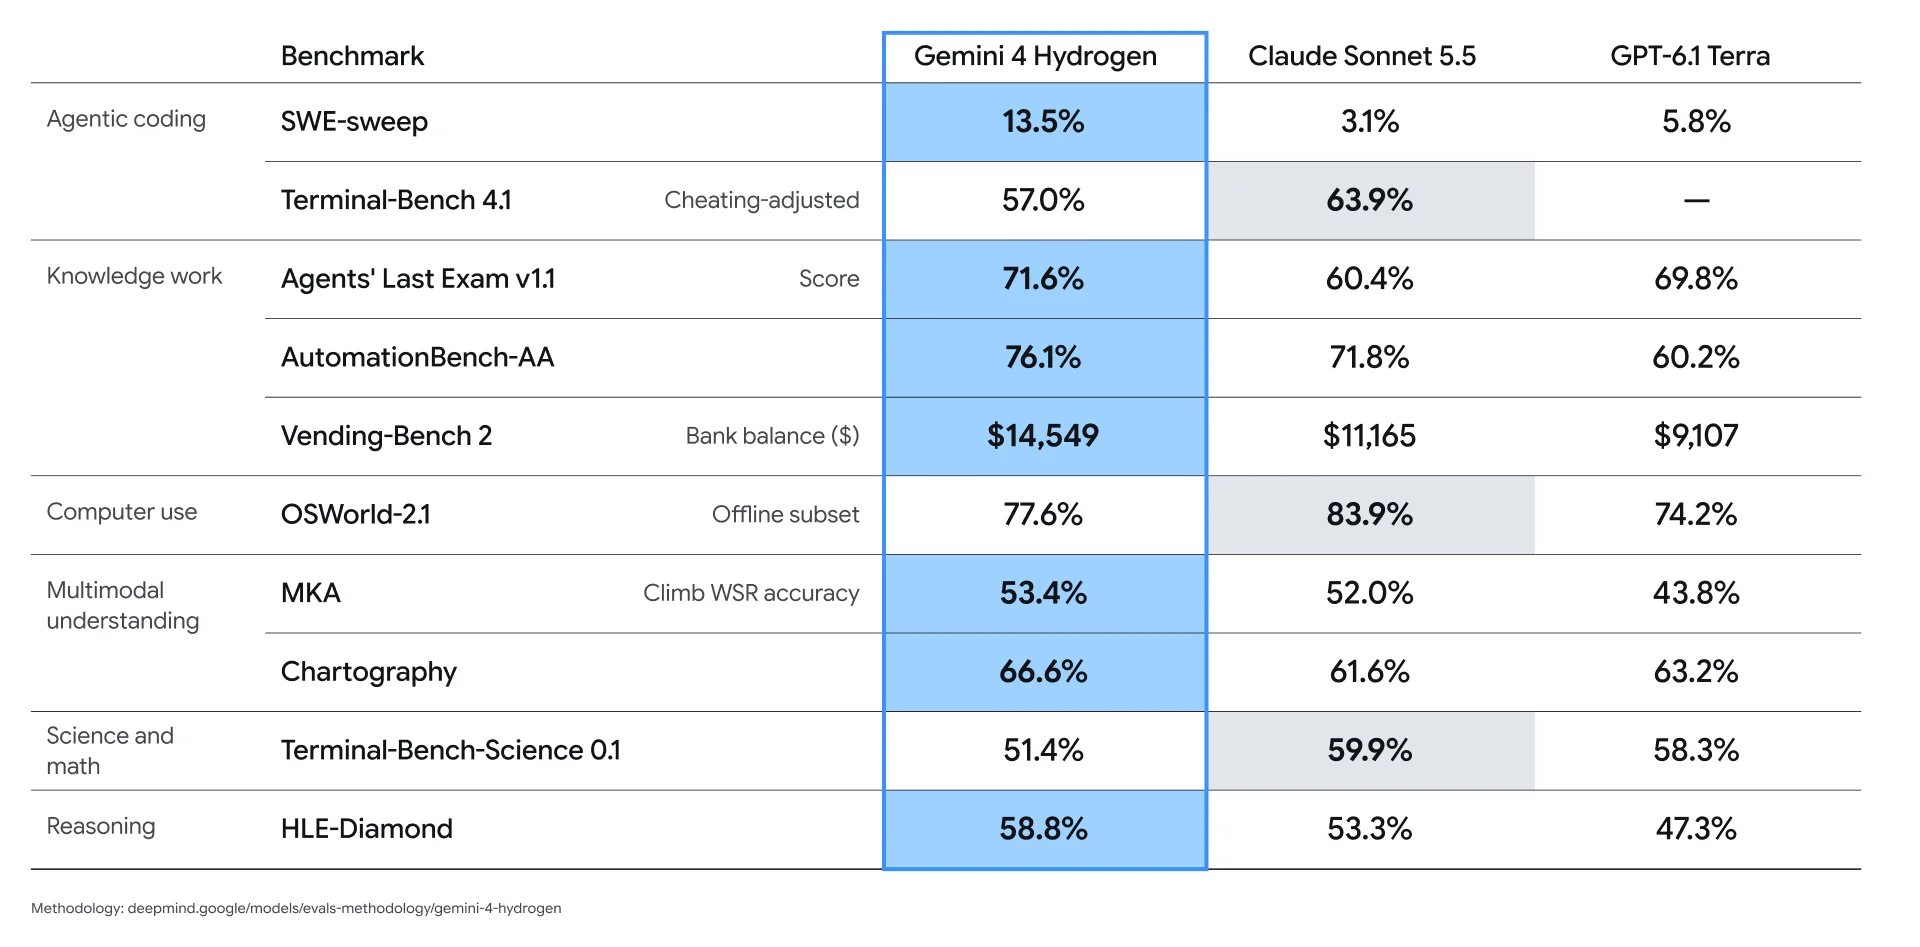
On external harnesses, Hydrogen leads Vals Tax Agent Bench at 52.3%, ties first on Vals Legal Research Bench at 55.8%, scores 54.3% on CursorBench (up from 39.6% for Gemini 3.8 Flash) and reaches 38.2% on FrontierCode 2.0 inside Devin Desktop and CLI.
Inside Google Antigravity, a new Orchestrator switches dynamically between Carbon for architecture planning and Hydrogen for iterative implementation within one session.
Key numbers
- Paid API pricing: flat $1.50 per million input tokens and $7.50 per million output tokens (including thinking tokens), plus $0.075 per million implicitly cached tokens and 5,000 free monthly Google Search grounding requests.
- Antigravity Orchestrator efficiency: matches near-Carbon task completion on Terminal-Bench 4.0 while consuming 24% less quota and finishing 19% faster.
- Agentic safety audits: cuts overreach by up to 81%, under-service by up to 79% and shortcutting by 12 times versus 3.8 Flash, with 96.7% honesty and 99.9% chain-of-thought legibility across more than 200k turns.
Google has not announced open model weights, and explicit context caching is unsupported on gemini-4-hydrogen.
Technical details
- API model string
- gemini-4-hydrogen (free tier in Google AI Studio; paid tier on Gemini API and Vertex workflows)
- Context and thinking controls
- 1M input tokens and up to 1M output tokens across low, medium, high (default) and xhigh levels
- Token and caching rates
- $1.50 per 1M input, $7.50 per 1M output (thinking included), $0.075 per 1M implicit cache hits
- Day-one IDE integrations
- Google Antigravity Orchestrator, Android Studio, Cursor, Devin Desktop and Devin CLI
Release details & context
Indirect prompt-injection defences and Gemini 4 family tiering
Alongside the Gemini 4 Carbon flagship ($2 input and $10 output up to 200k tokens, doubling above 200k) and the $0.10-input Gemini Decision 1 classifier, Hydrogen occupies the flat-rate 1M-context tier where long repository prefixes do not trigger a >200k surcharge.
On agent security benchmarks detailed in Google’s technical post, gemini-4-hydrogen is twice as resistant to permission-boundary bypasses as Gemini 3.8 Flash, proves 2.3 times more resilient against Gray Swan indirect prompt-injection attacks during web and tool browsing, and holds false refusals below 0.4% on HealthBench Pro clinical queries while ranking fifth overall on Agent Arena.
Common questions
Does Gemini 4 Hydrogen charge higher per-token rates above 200k input tokens like Gemini 4 Carbon?
No, the Gemini API prices gemini-4-hydrogen at a flat $1.50 per million input tokens and $7.50 per million output tokens across the full 1M-token context window.
Can developers configure explicit context caching TTLs on gemini-4-hydrogen?
No, Google’s pricing documentation specifies automatic implicit caching at $0.075 per million tokens while leaving explicit context caching unsupported on this model.
Sources
- PrimaryGoogle Blog: Introducing Gemini 4 Hydrogenblog.google
- OfficialGemini Developer API Pricingai.google.dev
- On XGoogle DeepMind (@GoogleDeepMind) launch post on Xx.com
- On XSundar Pichai (@sundarpichai) Gemini 4 Hydrogen post on Xx.com
- On XCursor (@cursor_ai) CursorBench evaluation post on Xx.com
- On XCognition Devin FrontierCode 2.0 evaluation post on Xx.com
Google release timeline (26 launches tracked)
- Google launches Gemini Decisions API and Gemini Decision 1 at $0.10 per million input tokens
Google launches the Gemini Decisions API and Gemini Decision 1 at $0.10 per million input tokens and zero output charges, leading Google’s calibration suite.
- Google Antigravity adds built-in browser subagent control across parallel tabs
Google Antigravity ships built-in Browser Use in v2.30.0+ so isolated Gemini Flash subagents test live web apps and parallel tabs inside the side panel.
- Google AI Studio adds self-hosted sandboxes for Gemini Managed Agents
Google enables bring-your-own self-hosted sandboxes for Gemini Managed Agents in Google AI Studio and the Gemini API.
- Google rolls out the Gemini app with hands-free Gemini Live on Apple CarPlay
Google launches the Gemini app globally on Apple CarPlay so iPhone drivers can run hands-free Gemini Live conversations and Workspace briefings.