

Open sourceTencentConfirmed
Story 2 of 13 in the Friday 20 November editionTencent open-sources 770B Hy4 multimodal MoE and Hy4-FP8 weights
Live on Hugging Face, ModelScope and GitCode on 20 November 2026 alongside pre-trained Hy4-base, a 3.3B DFly2 drafter and 1M context under the Tencent Hy License.

 Edited by Ashutosh Shrivastava
21 Nov 2026, 08:30 IST · 3 min read
Tencent’s Hy Team published open weights for its flagship Hy4 instruct model (tencent/Hy4), FP8-quantised Hy4-FP8, pre-trained Hy4-base and an end-to-end test GGUF build on 20 November 2026 across Hugging Face, ModelScope and GitCode. The release fulfils the open-weight pledge from Tencent’s 4 November Hy4 API launch and follows 220B open-weight Hy4-flash. Its 78-layer language backbone pairs one dense layer with 77 Mixture-of-Experts layers totalling 770B parameters, activating top-8 of 256 routed experts plus one shared expert for 49B active text parameters and 1.23B vision parameters per token across a 1,048,576-token context window.
Gated DeepSeek Sparse Attention, DFly2 zero-KV drafting and serving images
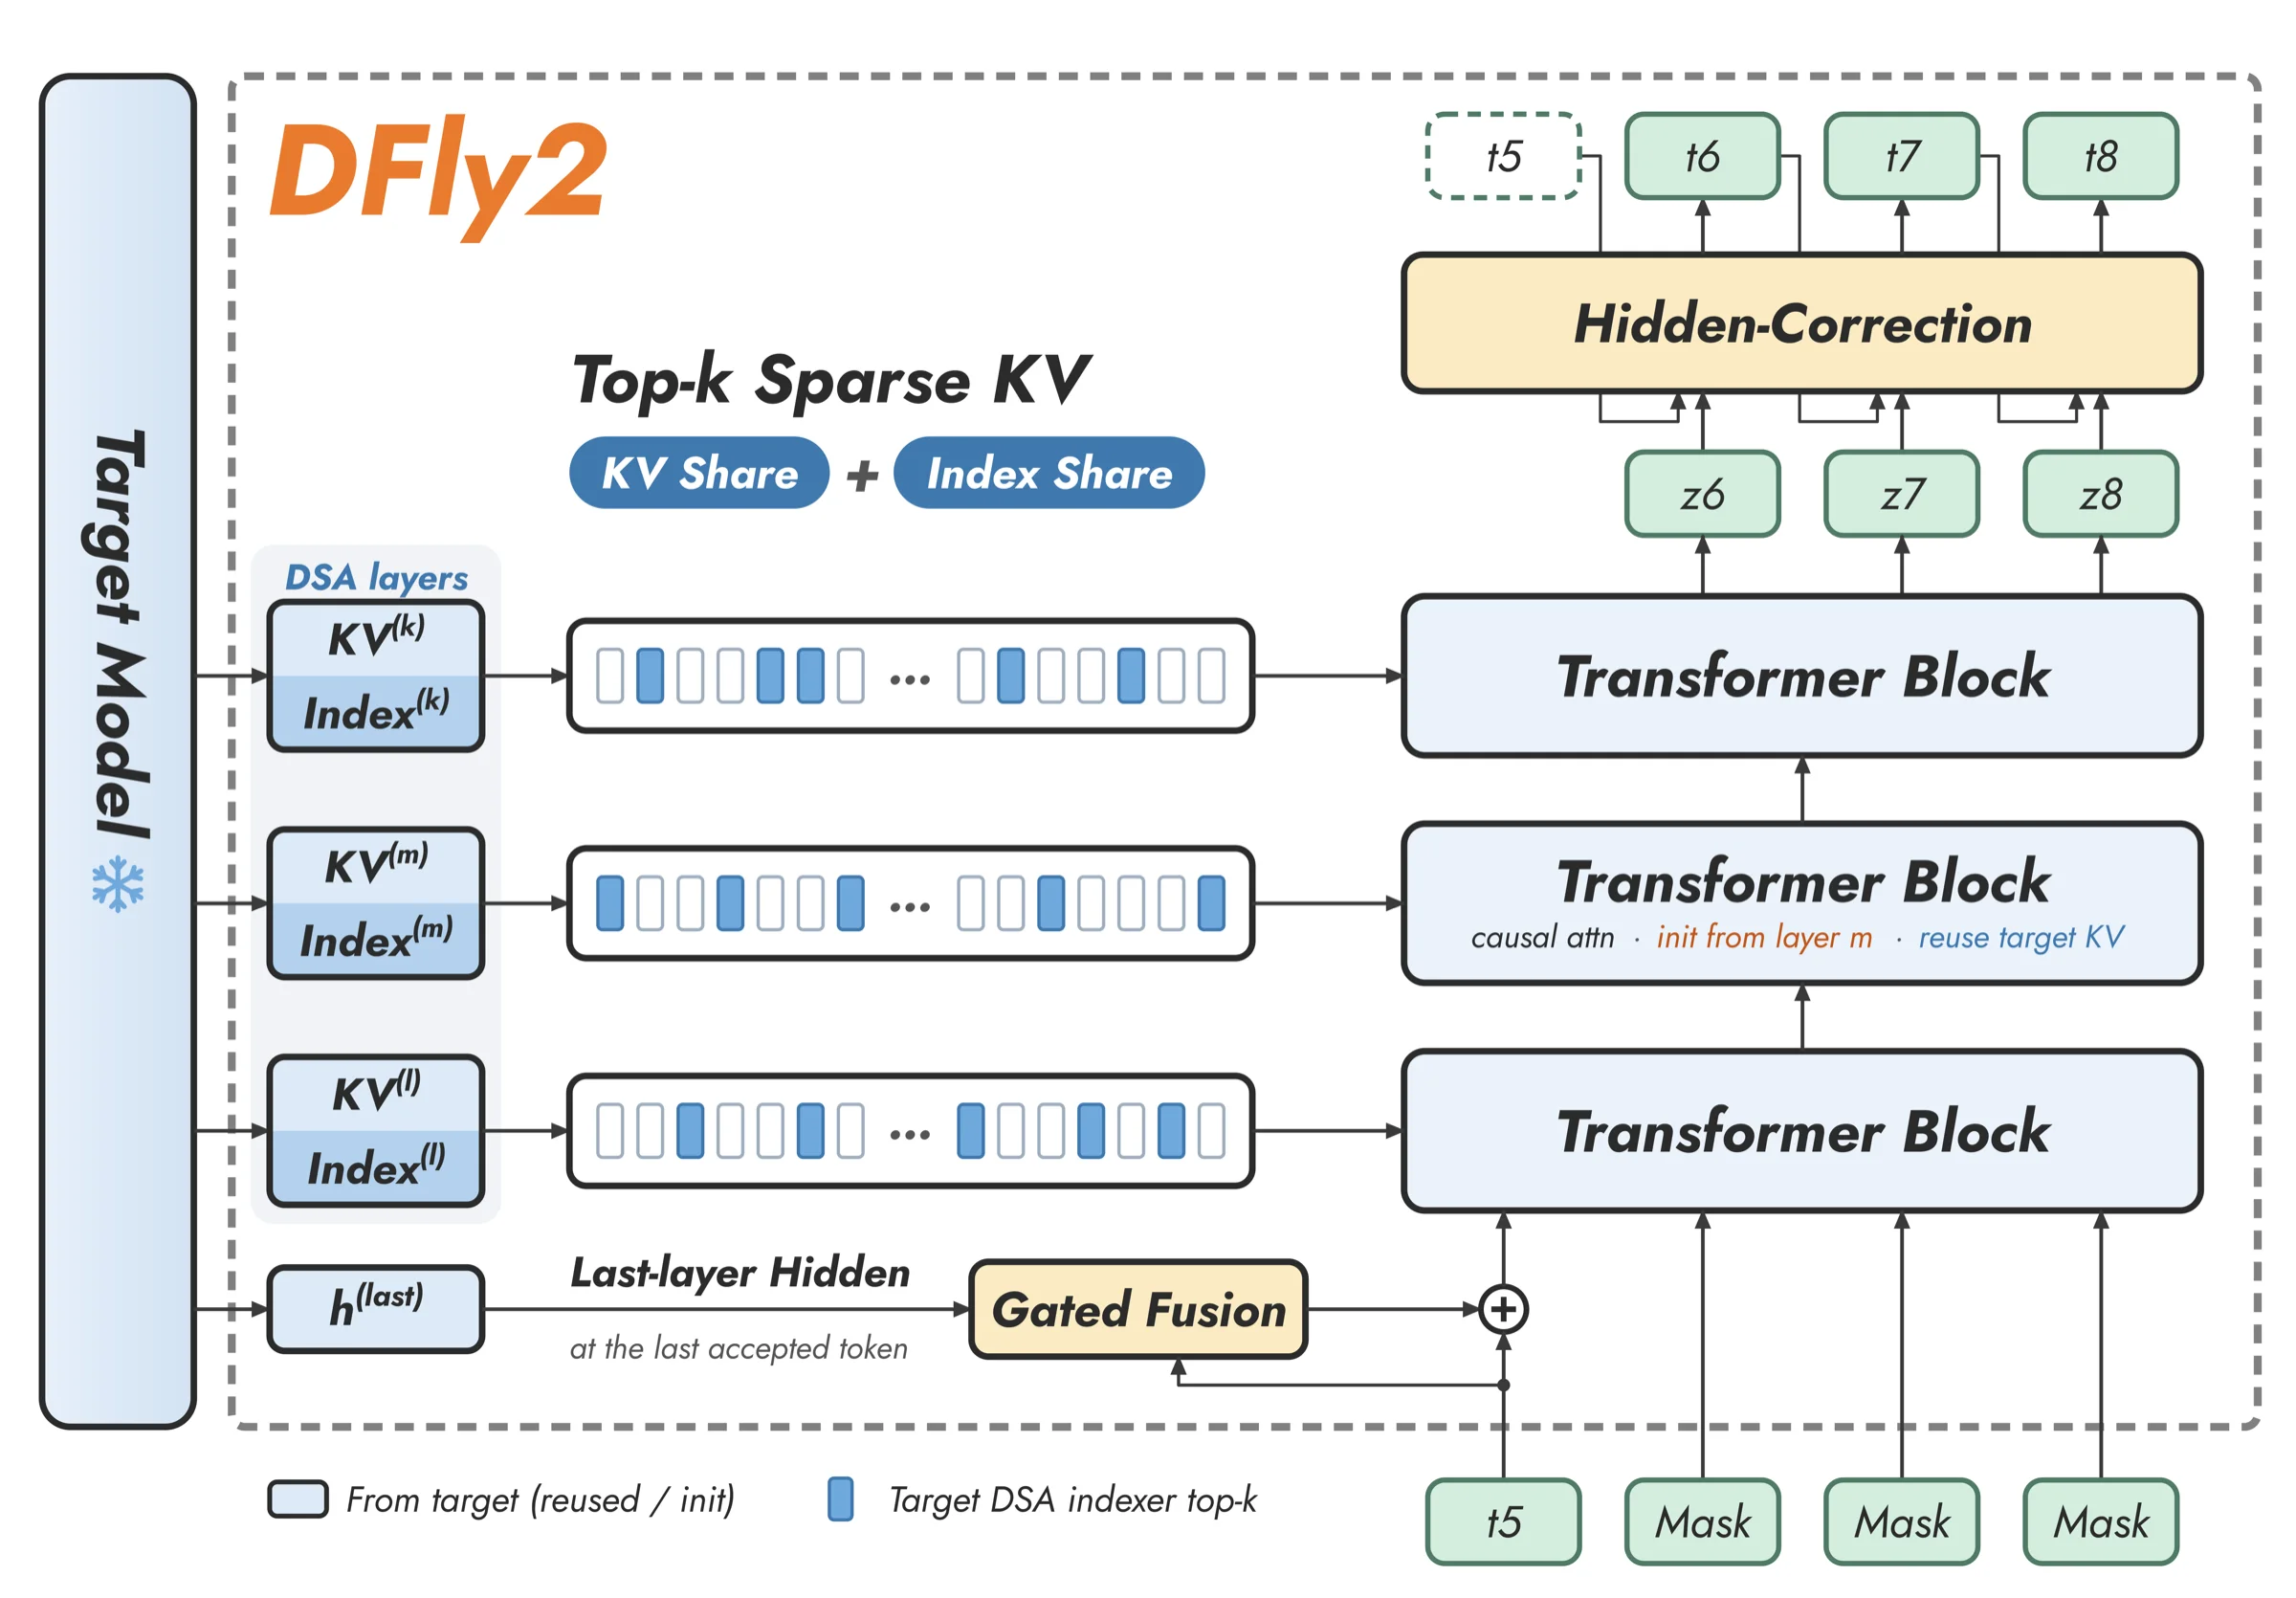
Hy4 combines Multi-head Latent Attention with Gated DeepSeek Sparse Attention, selecting the top 2,048 tokens per step and reusing sparse indices across layers via IndexCache alongside four-stream identity Hyper-Connections. Built directly onto the backbone is DFly2, a five-layer, 3.3B-parameter speculative-decoding drafter trained with AngelSpec that shares Hy4’s KV cache and top-2,048 sparse positions so each draft token attends to roughly 2,000 keys with zero extra KV memory.
Tencent ships prebuilt multi-arch Docker containers (vllm/vllm-openai:hy4 and lmsysorg/sglang:hy4), its AngelSlim compression suite and the Hy4 System Card under the Tencent Hy License, which requires separate commercial licensing above $50 million in annual MaaS revenue or 100 million monthly active users.
Technical details
- Checkpoints published
- tencent/Hy4 (instruct), tencent/Hy4-FP8, tencent/Hy4-base and end-to-end test GGUF
- Backbone and active parameters
- 770B language backbone (78 layers: 1 dense + 77 MoE); 49B text + 1.23B vision active; 3.3B DFly2 drafter
- Attention and serving containers
- MLA + Gated DSA (top-2,048 IndexCache); vllm/vllm-openai:hy4 and multi-arch lmsysorg/sglang:hy4
- Licence and hosted API rates
- Tencent Hy License ($50M MaaS or 100M MAU threshold); API at $0.834 input, $0.042 cached, $2.501 output per 1M
Release details & context
Reasoning modes, prefill-decode disaggregation and safety red-teaming
When served on vLLM or SGLang, Hy4 defaults reasoning_effort to high for deep chain-of-thought math and coding, while passing chat_template_kwargs reasoning_effort set to no_think returns direct answers at recommended sampling settings of temperature 0.9 and top_p 1.0. Because DFly2 skips prefill entirely, prefill-to-decode disaggregation transfers only one final-layer hidden state between nodes.
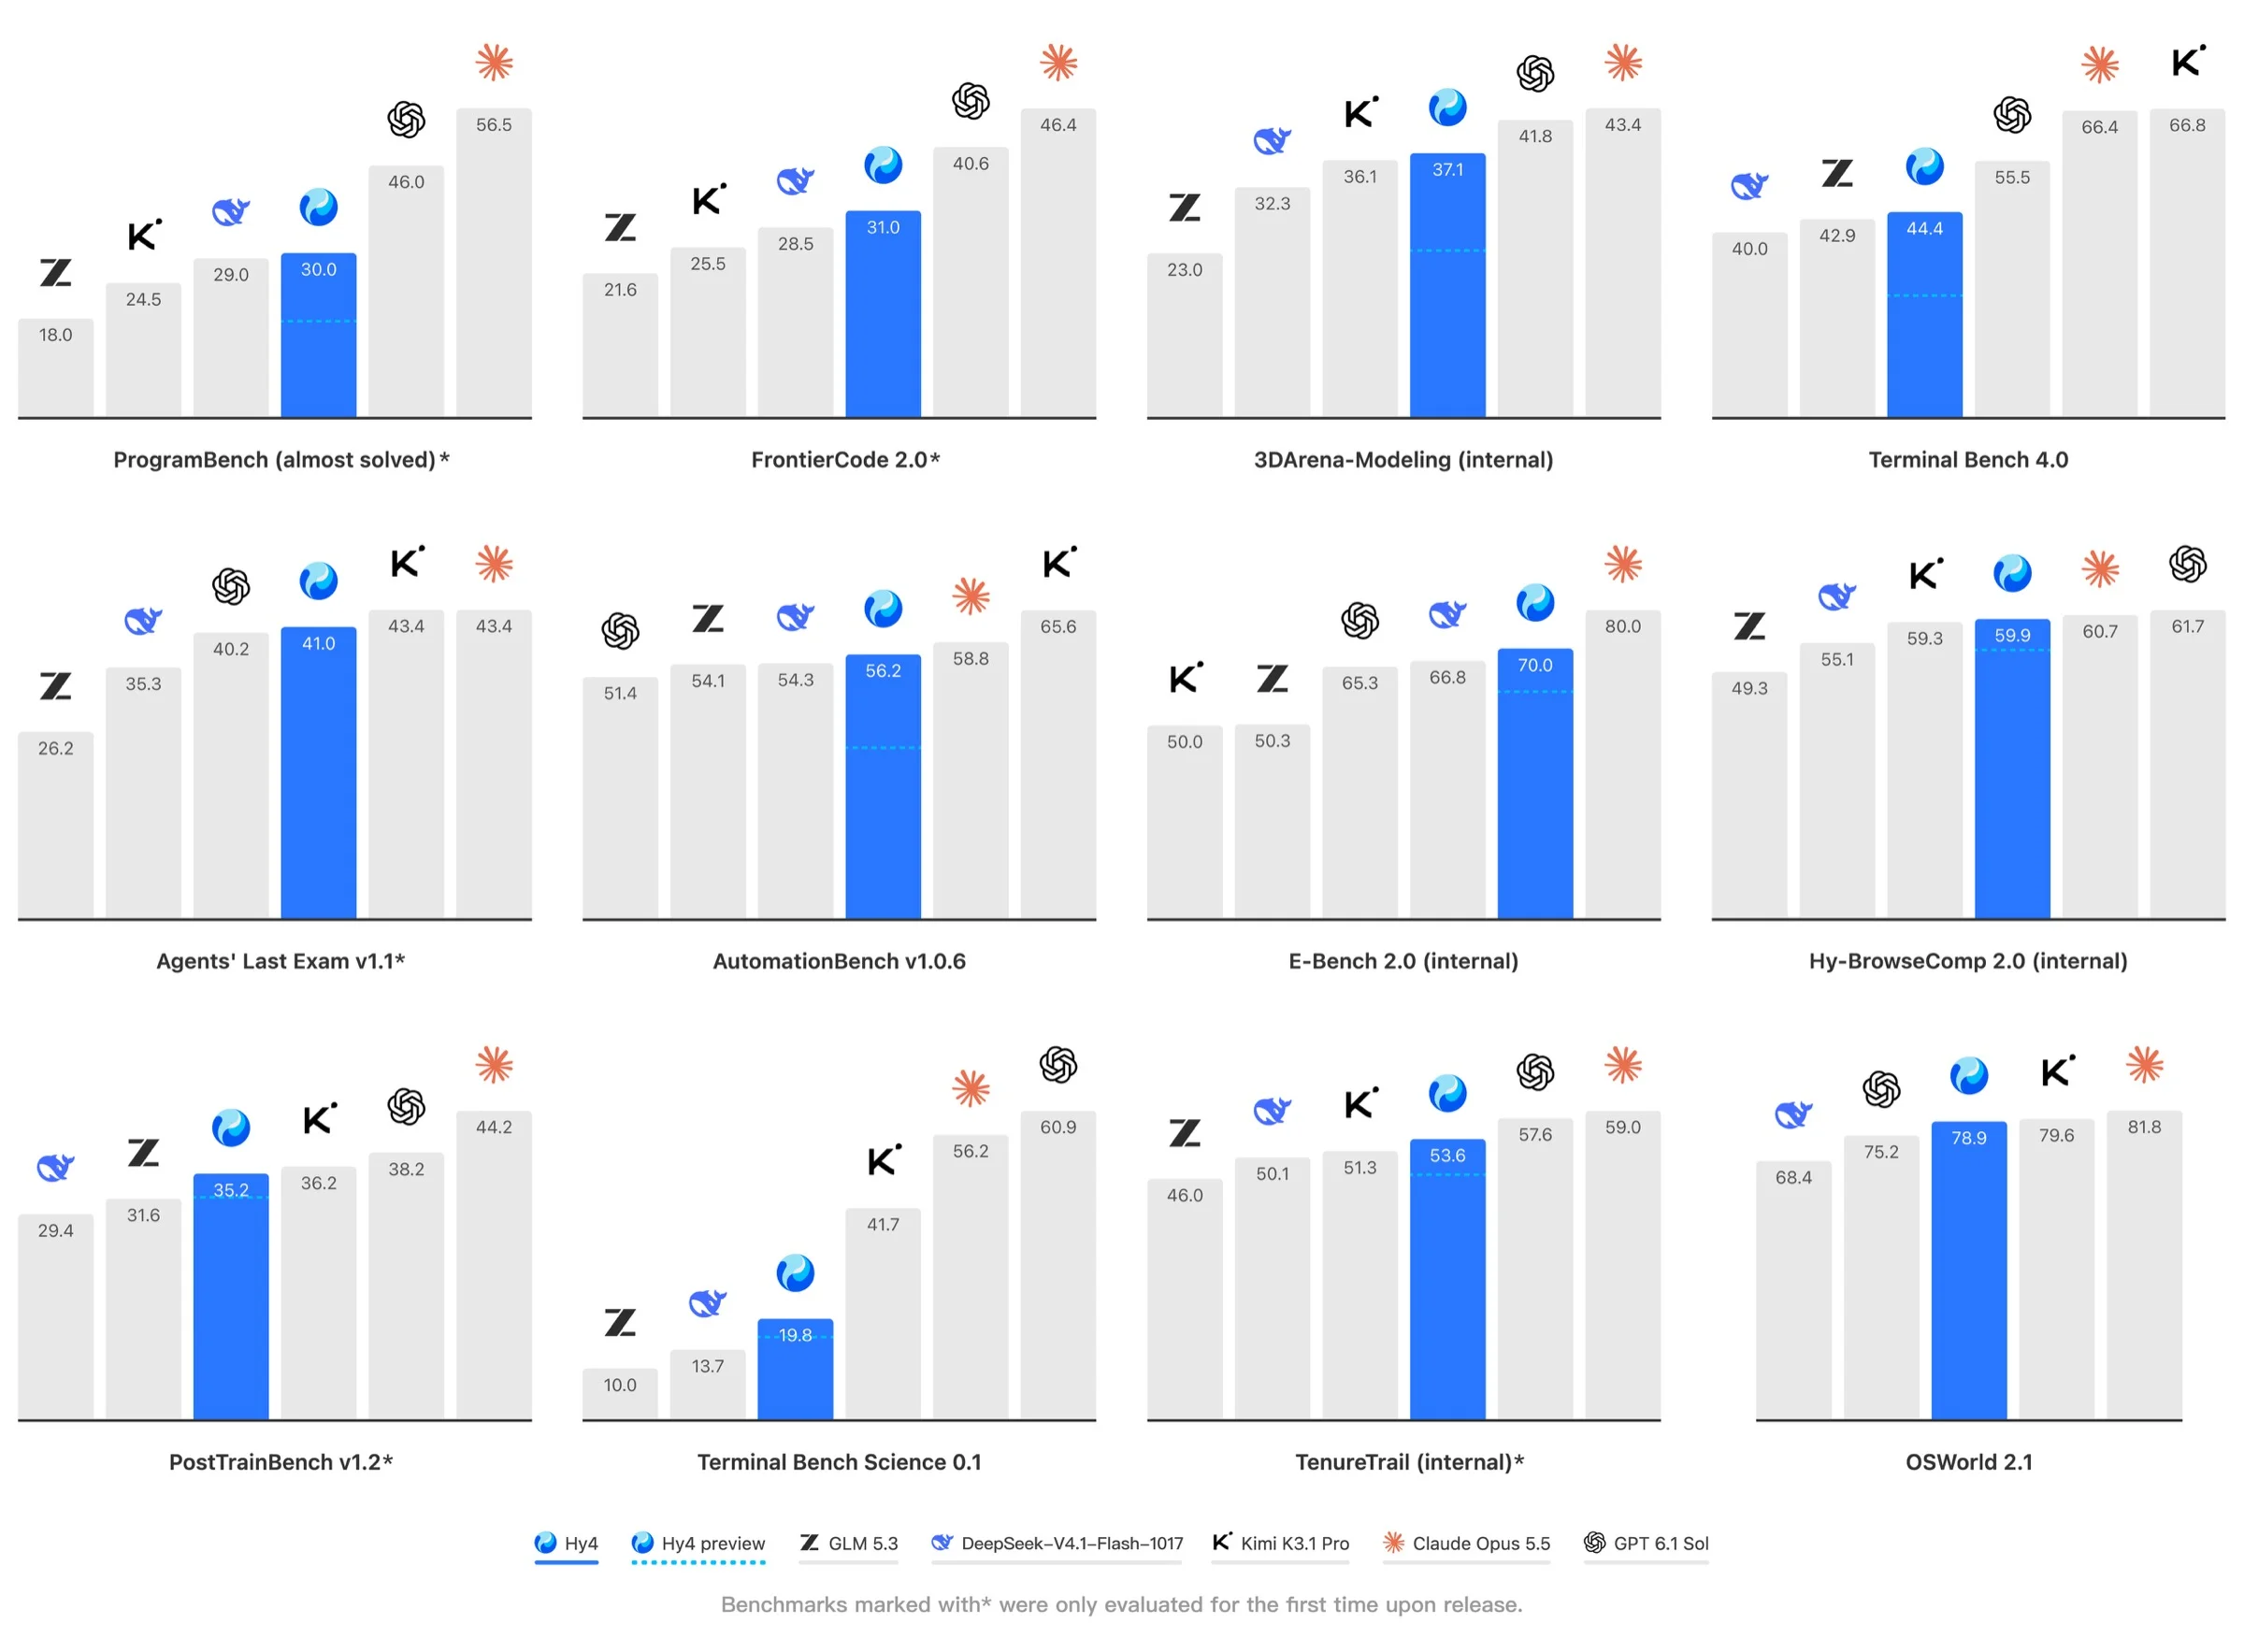
Across domain benchmarks, Hy4 ranked first among open-weight models on TenureTrail (123 scientific tasks across seven disciplines) and cut internal financial hallucination rates from 15.76% on Hy4 preview to 5.45%, while scoring 30.4 out of 100 on Hy-BioExperimentBench and passing offensive cryptanalysis and binary-obfuscation audits by Tencent Xuanwu Lab and Keen Security Lab.
Common questions
How does Hy4’s DFly2 speculative drafter avoid extra KV-cache memory on 1M-token contexts?
Each of DFly2’s five draft layers shares the backbone’s KV cache and Gated DSA top-2,048 selected token indices directly, capping draft attention at roughly 2,000 keys without allocating a separate KV store.
Who needs a separate commercial agreement under the Tencent Hy License?
Organisations operating Model-as-a-Service platforms above $50 million in annual revenue or products exceeding 100 million monthly active users must request a separate commercial licence from Tencent.
Editor’s weekly perspective
Open-weight MoEs, robotics and RL harnesses: Publishes 770B flagship Hy4, Hy4-FP8 and Hy4-base checkpoints (49B active text) with a 3.3B DFly2 drafter.
Sources
- Primarytencent/Hy4 on Hugging Facehuggingface.co/tencent
- Officialtencent/Hy4-FP8 on Hugging Facehuggingface.co/tencent
- Officialtencent/Hy4-base on Hugging Facehuggingface.co/tencent
- OfficialTencent Hy Research: Introducing Hy4hy.tencent.ai
Tencent release timeline (4 launches tracked)
- Tencent launches multimodal Hy4 model with native computer use and 3D engine training
Tencent released Hy4 on Tencent Cloud TokenHub at roughly $0.90 per 1M input tokens, adding multimodal perception, computer use and 3D engine workflows.
- Tencent launches 224B Hy4 flash multimodal MoE at $0.070 input
Tencent launches its 224B-total, 12B-active Hy4 flash multimodal model at $0.070 input and $0.281 output, at one-twentieth of Hy4’s task cost.
- Tencent releases open-weight 220B Hy4-flash models with 1M context
Tencent open-sources its 220B-total, 12B-active multimodal Hy4-flash, Hy4-flash-FP8 and Hy4-flash-base models on Hugging Face.